Receipt rewards and shopper marketing
The Receipt Rewards Offer That Mistook Brand Affinity For Lift
Organization byline: Measurement Press editorial desk. This page does not list an individual author or reviewer. Read the editorial method and corrections policy.
About 11 min read
A realistic receipt rewards scenario showing how offer activation and receipt submission can turn pre-existing brand affinity into an overstated sales lift claim.
Simulated Worked Example. This is a constructed, synthetic, and anonymized editorial scenario using simulated data; no named advertiser, campaign, client, or observed result is asserted. The figures are for method demonstration and are not reported client results.
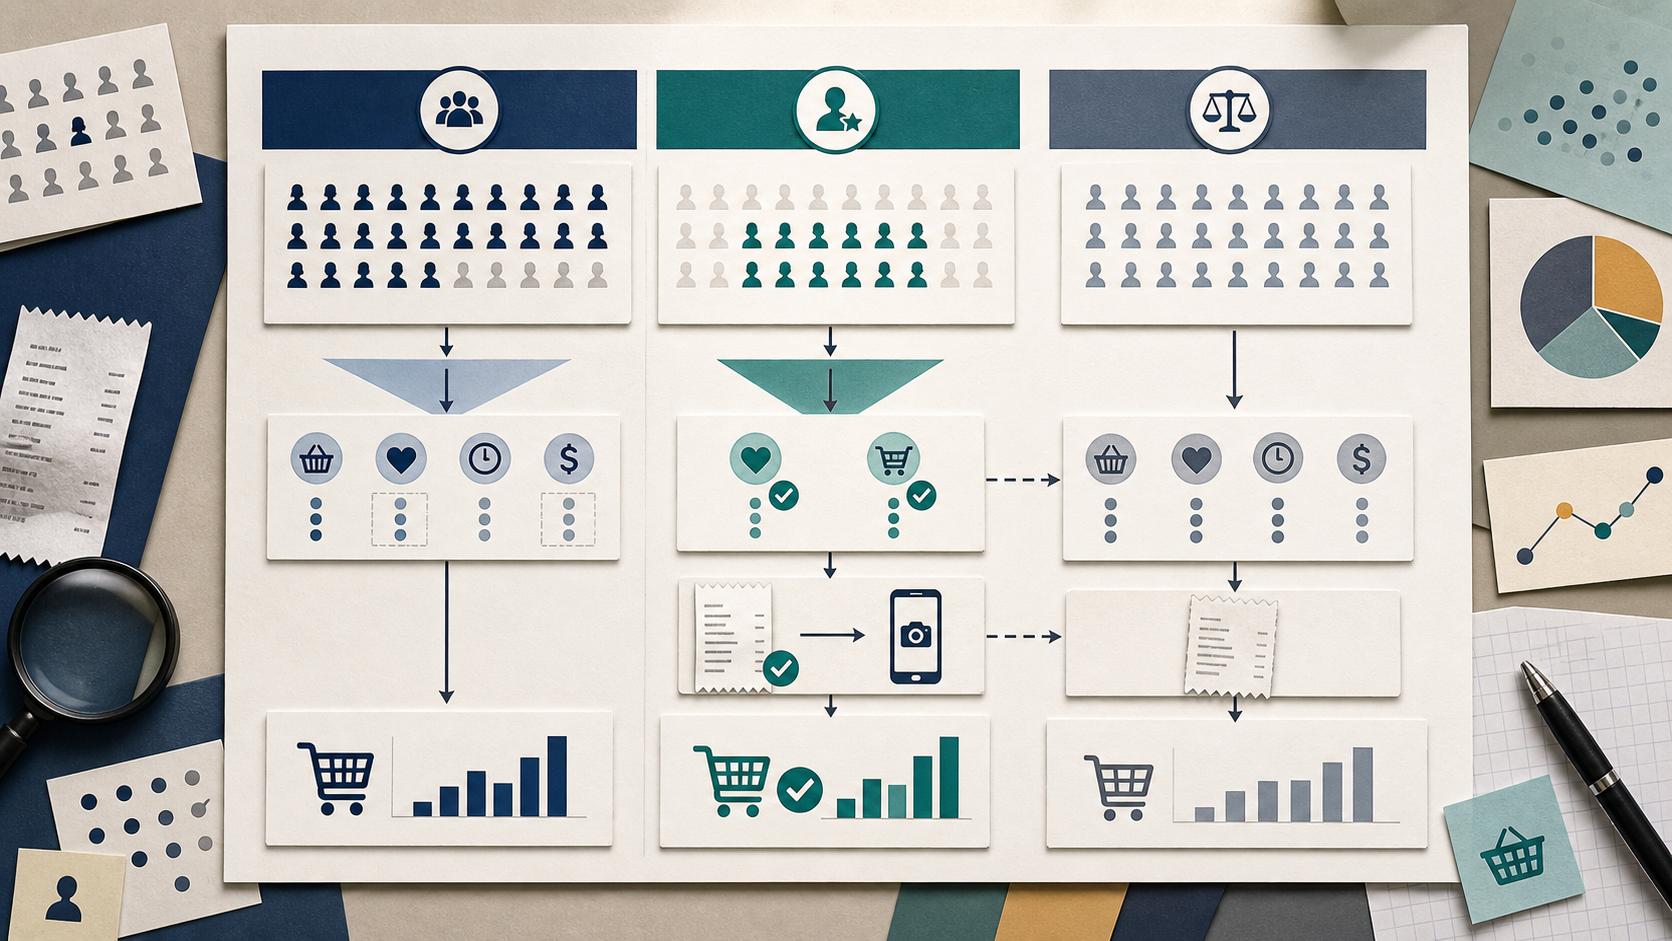
Archetype: Receipt-scanning rewards app with personalized brand offers
Bias mechanism: Users who clip, activate, or submit qualifying receipts are already more engaged with the category and more likely to buy the brand. The action required for treatment reveals intent that the control group never had to reveal.
Business model pressure
Brands fund offers, shopper campaigns, or audience programs inside a rewards app where users submit receipts and earn points. The channel can be useful because receipt capture is close to purchase behavior, but the advertiser needs to know whether the offer changed demand or mostly attracted shoppers who already had category interest and were willing to document a trip.
Advertiser proof claim
A campaign report can show that offer activators or receipt submitters bought more of the brand than broad app users. The relevant question is whether those submitters were already stronger category buyers before the offer, and whether a comparable rewards-eligible group would have produced a similar receipt pattern without the personalized offer.
Primary-source boundary for the method
These sources define the measurement boundary used in this simulated case; they do not validate the fictional data or describe a named rewards app. Google distinguishes attributed conversions from incremental conversions and describes lift as a treatment-versus-control comparison. We use that distinction to set a claim ceiling: an affinity-balanced diagnostic can expose selection risk, but it is not a substitute for randomized offer visibility.
- Official user-based Conversion Lift measurement guide — Defines incremental conversions as the difference between treatment and control conversions and separates that measure from standard attributed reporting.
- Display & Video 360: set up Conversion Lift measurement — Describes randomized controlled experiments, treatment exposure, control holdback, and considerations for interpreting incrementality.
- Official lift studies guide — Explains why a controlled treatment/control split is needed before a difference is described as campaign-driven lift.
Source-to-decision handoff
Use the official measurement guidance to decide what a real receipt-rewards readout must show. These sources set the claim boundary for this simulated case; they do not validate its fictional shopper records, rates, or modeled benchmark.
| Source-backed point | Evidence to request | Decision consequence |
|---|---|---|
| Official user-based Conversion Lift guidance Incremental conversions come from the treatment-versus-control difference; standard attributed conversions follow configured attribution rules. | The eligible rewards population, offer visibility, activation, receipt submission, treatment/control assignment, and conversion windows. | Call activator or submitter purchases attributed participant outcomes unless the comparison represents equivalent offer opportunity. |
| Display & Video 360: set up Conversion Lift Conversion Lift uses randomized treatment and control groups and warns about contamination, seasonality, and measurement-coverage limits. | Randomized offer availability, protected holdout records, cross-channel exposure, concurrent campaigns, seasonality, and receipt-measurement coverage. | Do not promote an affinity-balanced diagnostic to causal lift when offer visibility or the receipt opportunity was not protected. |
| Official Conversion Lift measurement guidance Incremental conversion value and iROAS subtract the control outcome before dividing by spend; attributed ROAS is a different measure. | Treatment and control value, media cost, reward cost, rejected or duplicate receipts, refunds, margin, and the exact value definition. | Keep the simulated $283,314 and 2.02x figures labeled as attributed proxy arithmetic; they are not incremental revenue or iROAS. |
| Official lift studies guidance A lift study is a controlled experiment whose treatment/control difference estimates the increase driven by ads. | A predeclared outcome, comparable eligible audience, locked analysis window, and the result for a protected comparison group. | Use this case for diagnosis and test planning; require the stronger design before making a budget or renewal claim. |
Statistical result
| Metric | Naive read | Stratified read | Modeled benchmark |
|---|---|---|---|
| Brand purchase-rate lift | 15.8 pts | 1.1 pts | 0.7 pts |
| Attributed incremental purchases | 9,139 | 640 | 406 |
| Attributed brand sales | $283,314 | $19,827 | $12,580 |
| Attributed sales after media cost | 2.02x | 0.14x | 0.09x |
The activator-versus-broad-user report is 14.3x larger than the affinity-balanced estimate in this worked example.
Reproduce the simulated readout
The numbers below are generated by the repository's deterministic case-study simulator, not imported from a campaign. Re-run the case-study generator from the repository root to regenerate the page and JSON artifact; the seed, population, formulas, and claim boundary are intentionally exposed so a reader can audit the arithmetic.
| Item | Calculation or assumption |
|---|---|
| Seed and population | Seed 777001; 95,000 fictional rewards-eligible shopper records; the simulator assigns 57,971 records to the activator/treatment lane and 37,029 to the comparison lane (61.0% / 39.0%). |
| Selection mechanism | For each record, three seeded uniform draws create an affinity score; a logistic intent rule then feeds treatment assignment: logistic(-2.3 + 4.0 × affinity + 1.4 × intent). |
| Outcome mechanism | The comparison purchase probability is logistic(-3.4 + 3.4 × affinity + 1.2 × intent). Treatment adds the configured 0.7 percentage-point synthetic lift, capped at 92%; value per conversion is $31 and simulated media cost is $140,000. |
| Naive arithmetic | Treatment purchase rate 37.4% minus comparison rate 21.6% = 15.8 points; 15.8% × 57,971 = 9,139 proxy incremental purchases; 9,139 × $31 = $283,314; $283,314 ÷ $140,000 = 2.02x. |
| Affinity-balanced diagnostic | Within the usable treatment-propensity deciles, the count-weighted difference is 1.1 points; 1.1% × 57,971 = 640 proxy incremental purchases; 640 × $31 = $19,827; $19,827 ÷ $140,000 = 0.14x. |
| Interpretation limit | The 14.3x naive-to-adjusted ratio is a diagnostic of this fictional data-generating process, not a confidence interval or causal estimate. Unmeasured affinity, receipt-submission behavior, leakage, timing, and model misspecification could still change the result. |
Assumptions: The scenario assumes one binary purchase outcome, one eligible population, fixed $31 value per conversion, $140,000 media cost, no interference between records, and a 0.7-point configured treatment effect. The simulator does not model rejected or duplicated receipts, reward cost, frequency, privacy loss, delayed purchases, or real app delivery rules. A randomized offer-visibility holdout with equivalent receipt opportunity is the evidence request that would change the conclusion.
Limitations: The simulator is not a real rewards-app, retailer, advertiser, or shopper dataset and supplies no offer-eligibility file, randomized availability flag, pre-period brand or category purchase history, receipt deduplication audit, reward-cost ledger, confidence interval, conversion-lag distribution, cross-channel contamination audit, privacy review, or observed campaign result. Propensity stratification can reduce measured mix differences but cannot recover unmeasured affinity or replace randomized offer availability. The displayed sales and ROAS figures are attributed simulated proxy values before reward cost, refunds, margin, repeat purchases, or other business adjustments.
Readout audit questions
Use this pass before the case becomes a budget argument, buyer proof point, or channel lesson. The goal is to separate what the dashboard observed from what the campaign plausibly changed.
| Check | Question to ask | Evidence in this case | Safer claim boundary |
|---|---|---|---|
| Credited outcome | What is the report counting as campaign impact? | Separate attributed outcomes from incremental outcomes. In this case, the naive lift is 15.8 pts while the stratified read is 1.1 pts. | Treat path, click, form, survey, or matched-outcome reporting as descriptive until the counterfactual is visible. |
| Comparison group | Were treatment and control groups comparable before the campaign? | Users who clip, activate, or submit qualifying receipts are already more engaged with the category and more likely to buy the brand. The action required for treatment reveals intent that the control group never had to reveal. | Ask for a protected holdout, balanced market, suppression test, or matched comparison before using causal verbs. |
| Budget threshold | Would the decision survive the adjusted read? | The naive read is 14.3x larger than the stratified estimate, and adjusted ROAS is 0.14x after media cost. | Use the result for diagnosis, repair, or test planning unless the adjusted evidence clears the decision threshold. |
| Next evidence | What would change the conclusion? | Test whether reward activation measured brand affinity more than campaign-caused demand. | Name the missing evidence request before turning one worked example into a general rule. |
For the next review, pair this case with Retail media incrementality checklist and the claim confidence rubric.
Reward-activation decision logic
Before this case becomes proof that the receipt rewards offer created brand lift, read the result through the activation and receipt-submission steps. The useful question is whether comparable rewards-eligible shoppers without the offer would have bought and submitted similar receipts.
| Review point | Evidence to request | Decision consequence |
|---|---|---|
| Eligible audience | The full rewards-eligible population, offer-ranking rules, category purchase history, brand affinity indicators, app engagement, receipt-submission history, and whether every eligible shopper had the same opportunity to see the offer. | If the report starts with activators or receipt submitters only, describe the result as participant response rather than incremental brand lift. |
| Activation and receipt filters | Offer activation rate, time from activation to purchase, receipt-submission friction, prior basket patterns, loyalty indicators, and whether submitters were already more willing to document purchases. | If activation and submission reveal stronger prior intent, remove causal lift and ROAS language until an eligible-audience counterfactual is visible. |
| Purchase evidence | Brand purchase rate, category purchase rate, basket size, repeat purchase, reward cost, rejected receipts, duplicate submissions, and new-versus-existing buyer split. | If the outcome is gross matched purchases among submitters, call it tracked submitter sales rather than incremental demand. |
| Comparison design | Randomized offer availability inside the eligible audience, suppression records, pre-period brand and category balance, locked attribution windows, and whether comparison shoppers had equivalent receipt-submission opportunity. | If no protected comparison exists, use the case for diagnosis and test planning, not budget expansion. |
| Readout boundary | A prewritten claim ladder separating activation, receipt capture, observed purchases, affinity-balanced lift, and randomized incrementality. | If renewal depends on causal proof, require the stronger design before turning the receipt rewards result into public or buyer-facing lift language. |
Worked downgrade
The headline version of this case says reward activators and receipt submitters produced a 15.8 point brand purchase-rate lift, 9,139 incremental purchases, and $283,314 in attributed brand sales. The result sounds practical because the receipt is a real purchase record and the reward path looks close to the sale.
The weaker read appears when the activation log shows that participants already had stronger category affinity, more app engagement, more receipt-submission history, and a higher chance of buying the brand before the personalized offer could change behavior. After comparing shoppers within similar activation-propensity strata, the estimated movement falls to 1.1 points and $19,827 in attributed sales against $140,000 of media cost. The modeled benchmark is 0.7 points.
The safer readout sentence is: reward activators and receipt submitters bought the brand at a higher rate, but the evidence does not prove incremental demand because activation and receipt submission selected shoppers with stronger prior affinity. The next action is to rerun with randomized offer availability among rewards-eligible users, receipt-submission balance reporting, and a protected holdout before using lift or ROAS language.
The advertiser-facing story
The campaign appears strong because the report begins with shoppers who activated a reward, submitted a qualifying receipt, and then produced a purchase record that feels closer to revenue than a click or visit. The offer path can look like clear proof: a reward was available, a shopper acted, a receipt arrived, and the brand purchase appeared inside the measurement window.
What broke
The treatment condition requires behaviors tied to category interest and record-keeping willingness. A shopper who activates a brand offer and submits a grocery receipt is not comparable to a broad app user who never had the same offer opportunity, never had to reveal intent, and may not have been equally likely to upload a receipt after purchase.
Better design
Randomize offer visibility among eligible users before activation, compare within pre-offer brand-affinity strata, distinguish activation lift from purchase lift, and report receipt-submission balance alongside pre-period brand and category purchase balance. The cleaner readout starts with the eligible audience, not only with people who completed the reward path.
Propensity-strata audit
The adjusted estimate compares activators and comparison shoppers within similar reward-activation propensity strata. That does not replace randomized offer availability, but it shows how much of the headline purchase gap was carried by shoppers who already looked more likely to buy and submit a receipt.
| Propensity stratum | Rewards-eligible shopper records | Activator purchase rate | Rewards-eligible comparison purchase rate | Within-stratum difference |
|---|---|---|---|---|
| 2 | 3,207 | 8.4% | 5.4% | 3.0 pts |
| 3 | 8,204 | 9.9% | 8.3% | 1.5 pts |
| 4 | 9,797 | 13.3% | 12.3% | 1.0 pts |
| 5 | 9,288 | 16.5% | 16.8% | -0.2 pts |
| 6 | 9,582 | 22.4% | 21.2% | 1.2 pts |
| 7 | 12,478 | 30.2% | 28.8% | 1.4 pts |
| 8 | 18,416 | 39.2% | 39.0% | 0.2 pts |
| 9 | 20,036 | 52.2% | 50.4% | 1.8 pts |
| 10 | 3,989 | 65.1% | 63.4% | 1.7 pts |
Takeaway
A strong receipt rewards readout should not stop at receipt submitters buying more of the brand. It should show the full eligible audience, offer visibility, activation, receipt-submission requirements, prior category purchase balance, reward economics, and how much of the result survives an affinity-balanced counterfactual.
Move from this case to the next review.
Use the case to tighten claim language, choose a better measurement method, and review the next campaign readout without treating a worked example as a rule.
Claim review
Set the claim language
Score whether this evidence supports strong, qualified, tentative, or diagnostic wording.
Method choice
Choose stronger evidence
Pick the holdout, matched-market, MMM, survey, or QA method that fits the next decision.
Readout route
Inspect the report handoff
Move from the case lesson into delivery, response quality, outcomes, comparison strength, and renewal language.