Evidence standard
Claim confidence rubric for media and measurement
Organization byline: Measurement Press editorial desk. This page does not list an individual author or reviewer. Read the editorial method and corrections policy.
About 11 min read
Most weak claims do not fail because every fact is false. They fail because the sentence asks for more confidence than the evidence can carry.
Use this rubric when a headline, research report, dashboard, vendor readout, brand study, or advertising result sounds persuasive. It gives teams a shared language for deciding whether a claim deserves strong confidence, modest confidence, or only a note for further checking.
Picture the common meeting: a report says a campaign "drove" growth, a chart shows a sharp before-and-after increase, or a story says a pattern is spreading. The room wants a yes-or-no answer. The better first question is simpler: what confidence level has the claim earned, and what would lower it?
The confidence ladder
Confidence is not a mood. It is a ladder from "this is only a lead" to "this is strong enough for a bounded decision." Moving up the ladder requires more than a persuasive chart; it requires a visible source, a fair base, a relevant comparison, and language that does not outrun the method.
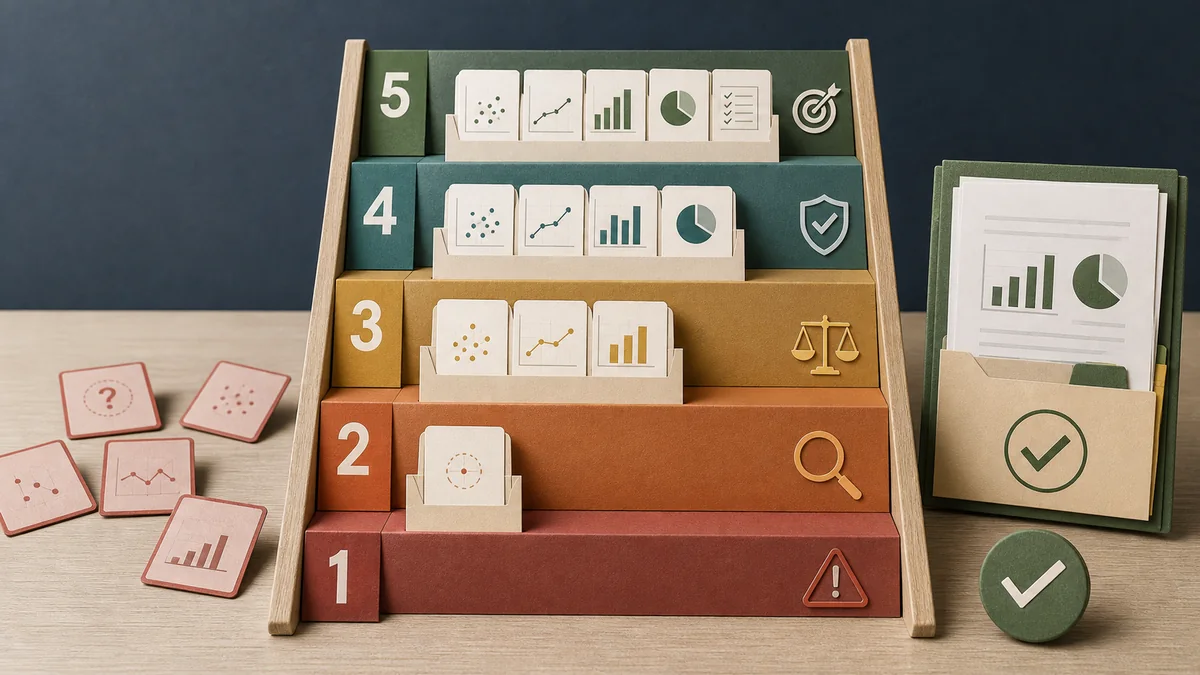
| Level | Evidence pattern | Supportable language | Do not say yet |
|---|---|---|---|
| 5. Decision-grade | The primary evidence is inspectable, the denominator is clear, the comparison is fair, and the uncertainty or sensitivity range is visible. | "The evidence supports this decision within these limits." | That the result will hold in every audience, market, time period, or method. |
| 4. Strong but bounded | The evidence trail is visible and the comparison is plausible, but some assumptions, caveats, or generalization limits remain. | "This is a strong read for this setting." | That the claim is settled outside the observed setting. |
| 3. Directional | The evidence points in a direction, but at least one major piece is incomplete: denominator, source independence, counterfactual, uncertainty, or subgroup base. | "This suggests a pattern worth testing or monitoring." | That the claim proves cause, size, prevalence, or budget impact. |
| 2. Weak signal | The claim relies on anecdotes, partial records, interested-party summaries, descriptive dashboards, or comparisons that may not be like-for-like. | "This is a lead, not a conclusion." | That the frame should drive a decision without more evidence. |
| 1. Unsupported frame | The source trail is missing, the denominator is hidden, the comparison is loaded, or causal language is stronger than the design. | "The public evidence does not support this framing." | The original strong claim, even with softer wording. |
Primary source trail and a simulated confidence gate
The confidence ladder is an editorial decision aid, not a probability of truth. Its checks follow the evidence questions in primary guidance: AAPOR's disclosure standards call for enough methodological detail for independent review, including the sponsor, population, sample method, field dates, sample size, weighting, processing, and limitations. The U.S. Census Bureau Statistical Quality Standards define coverage as the relationship between a target population and the sampling frame, including undercoverage and overcoverage. For advertising, Google's Conversion Lift documentation distinguishes treatment and control conversions from ordinary attributed conversions, defines incremental conversions as treatment minus control, and warns that intervals, modeling, and low control volume affect interpretation. Google's Conversion Lift setup guidance also connects study power to conversion volume, duration, estimated lift, and holdout size.
Boundary: A disclosed method can still be a poor fit for the claim, and this rubric level is not a statistical probability or an approval of the source. Census coverage and uncertainty checks expose what is missing; Google's study-power guidance describes the chance of a conclusive lift result under a configured study, not the truth of a broad business claim.
Simulated worked example - not a real article, study, or forecast: A reviewer tests the sentence “The campaign doubled revenue.” The source record is available, but the comparison is a before-and-after chart with no holdout. The reviewer scores five evidence dimensions from 0 (missing) to 2 (inspectable and fit for the claim).
| Evidence dimension | Score | Reason in this simulation |
|---|---|---|
| Source inspectability | 2 | Underlying report and method note are available. |
| Denominator and time window | 1 | Revenue period is stated, but eligible records and coverage exclusions are unclear. |
| Comparison or counterfactual | 0 | A before-and-after chart does not show what would have happened without the campaign. |
| Uncertainty and reproducibility | 0 | No interval, sensitivity check, or independent reproduction is supplied. |
| Scope and limitations | 1 | The reviewer can narrow the wording, but generalization limits are not fully documented. |
| Total | 2 + 1 + 0 + 0 + 1 = 4 / 10 | Under this page's rule, 3-4 is level 2: weak signal, not a decision-grade causal claim. |
The resulting sentence is: “Reported revenue was higher after the campaign in the selected period, but the available comparison does not establish that the campaign caused the increase.” This score does not estimate a p-value, confidence interval, or probability that the claim is true. The result would change if a protected holdout or credible matched comparison, complete denominator, mature outcome window, uncertainty estimate, and documented exclusions became available.
A reproducible claim-ceiling worksheet
Use this smaller packet when a team needs a decision boundary before it has a full study. It does not turn a score into a probability. It records the highest sentence the supplied evidence can carry, then names the missing evidence that would move the ceiling.
Simulated worked example - not a real survey, audience, or budget recommendation: A draft slide says, "62% of buyers prefer channel A, so shift the budget." The fictional source packet reports 744 channel-A selections from 1,200 respondents. The reviewer checks six gates, scoring 1 when the gate is inspectable and fit for the draft sentence, otherwise 0.
| Gate | Score | Reproducible check |
|---|---|---|
| Source, sponsor, and instrument | 1 | The packet names the sponsor, field method, and question wording. |
| Population and frame coverage | 0 | The target buyer population and uncovered parts of the frame are not documented. |
| Denominator and exclusions | 1 | 744 / 1,200 = 62.0%; eligible records and exclusions are stated for the fictional table. |
| Comparison or causal design | 0 | A preference share is not a controlled estimate of budget impact or incremental sales. |
| Uncertainty or precision | 0 | No interval, design-effect treatment, or sensitivity range is supplied. |
| Replication and limitations | 1 | The response table can be recomputed, but generalization limits are only partly documented. |
| Total | 3 / 6 = 50.0% | Under this worksheet, the ceiling is level 3: directional evidence for this respondent set, not a budget-shift conclusion. |
The bounded rewrite is: "In this simulated respondent set, 744 of 1,200 respondents selected channel A (62.0%); the packet does not establish population preference, incremental sales, or a budget recommendation." The next request is a documented target population and frame, a precision or sensitivity analysis, and a comparison design that matches the budget decision. This boundary follows AAPOR's disclosure items for population, sampling, dates, sample size, weighting, processing, and limitations; Census guidance on coverage and uncertainty; and Google's distinction between attributed conversions and treatment-versus-control incremental results.
Assumptions and limitations: The counts, respondent labels, and draft sentence are fictional and intentionally small enough to recompute by hand. The 62.0% share is descriptive only; it is not a margin of error, causal estimate, market prevalence estimate, or evidence that channel A should receive more spend. A different frame, exclusion rule, question wording, or outcome definition could change the ceiling.
Two-minute triage
A quick triage pass is useful when the team cannot run a full audit before a call. The goal is to slow down the strongest sentence long enough to see whether the source, baseline, and limits are visible.
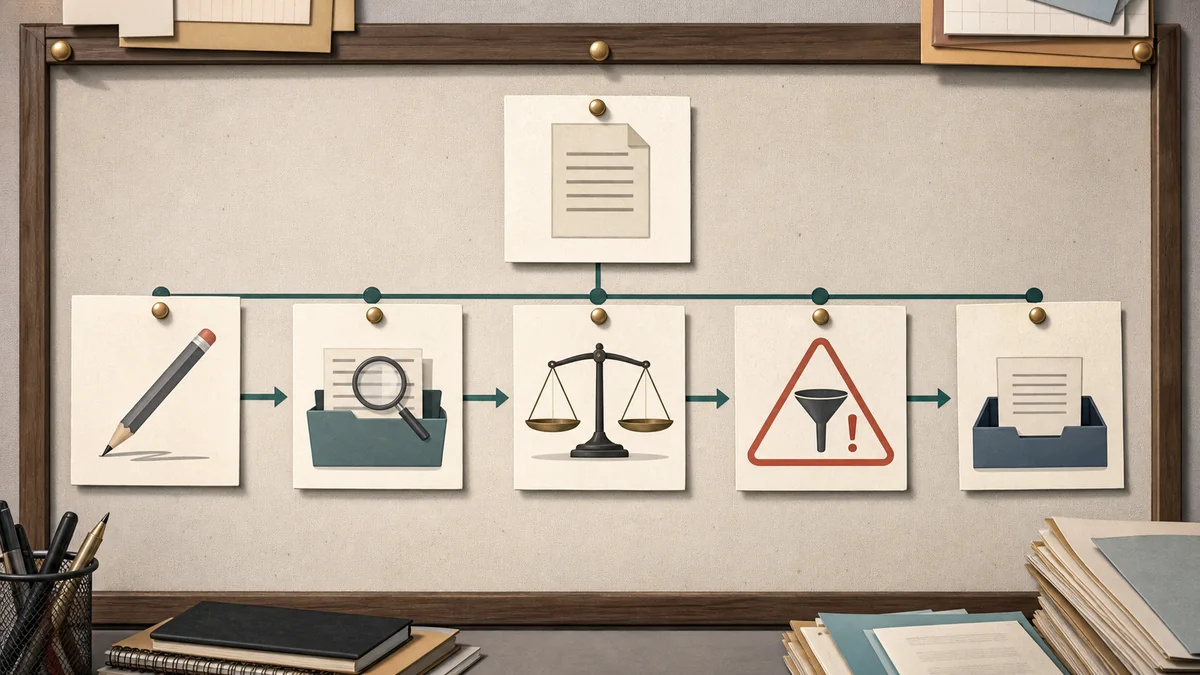
1. Rewrite the claimTurn the headline, slide title, or summary sentence into a plain testable sentence. Name the actor, population, metric, time window, and implied comparison.
2. Find the closest sourcePrefer the original record, full table, method note, questionnaire, model document, experiment plan, or readout appendix. A summary can be useful, but it should not hide the source underneath it.
3. Name the missing baselineAsk what would have happened anyway. For media claims, that may be a base rate, peer group, prior period, or complete record universe. For advertising claims, it may be a holdout, matched market, modeled counterfactual, or pre-period trend.
4. Downshift if limits are hiddenMove the confidence level down when the claim hides sample source, inclusion rules, field dates, uncertainty, outcome definitions, exclusions, or incentives that shape the result.
5. State the next evidence neededA good review ends with the document, test, denominator, sensitivity check, or disconfirming fact that would most change confidence.
Media framing checks
Media confidence depends on whether the reader can inspect the source trail and compare the claim against a fair baseline. A story can be accurate at the sentence level and still overstate prevalence, novelty, motive, or certainty.
| Claim type | Raise confidence when | Lower confidence when |
|---|---|---|
| Prevalence | The story shows counts, totals, time windows, and the population at risk. | It uses anecdotes or percent changes without starting levels. |
| Public-record finding | The record owner, inclusion rules, missing universe, and revision risk are visible. | A partial administrative record is treated as the full reality. |
| Source claim | Interested sources are identified and balanced against documents or independent context. | One side gets documents while another gets paraphrase or reaction labels. |
| Causal frame | Timing, documents, design, or direct evidence supports cause, motive, or impact. | Sequence, correlation, or quote volume is upgraded into proof. |
| Survey or poll frame | Population, sample source, wording, weighting, field dates, and uncertainty are available. | The headline treats a limited respondent group as a clean public verdict. |
Advertising measurement checks
Measurement confidence depends on whether the method matches the decision. A report can describe observed performance accurately while still failing to show what the media changed.
| Readout type | Raise confidence when | Lower confidence when |
|---|---|---|
| Lift test | Assignment, holdout protection, primary outcome, leakage checks, and uncertainty are stated before the result is read. | The exposed group could self-select or the holdout could be reached through another path. |
| MMM | Controls, priors, calibration, response curves, diagnostics, and uncertainty are visible. | Predictive fit is treated as proof that each channel estimate is causal. |
| Brand study | Exposed and control respondents are comparable, field dates are clear, and outcomes match the decision. | Survey recall or favorability movement is translated directly into sales impact. |
| Attribution report | The report is labeled as descriptive path evidence with clear identity, window, and channel limits. | Credit allocation is presented as incrementality. |
| Attention or viewability report | The metric is used as an exposure-quality diagnostic tied to a practical planning rule. | Attention is treated as proof of business impact by itself. |
Worked downgrade example
Downgrading a claim is not the same as rejecting the work. The reviewer preserves what the evidence can support, then removes the part that needs a stronger design or a cleaner denominator.
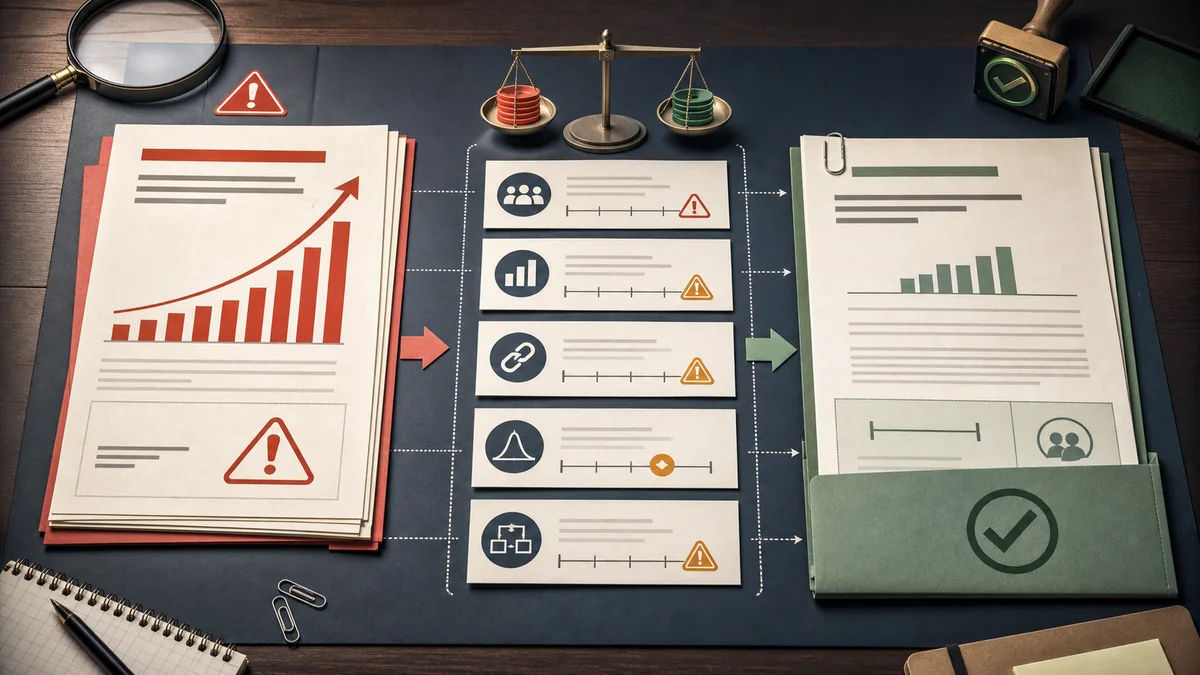
| Draft claim | Confidence problem | Better sentence | Next evidence request |
|---|---|---|---|
| "The campaign drove a 38% revenue increase." | The report shows exposed-path revenue, but it does not show what would have happened without the campaign. | "Revenue from tracked exposed paths was 38% higher than the selected baseline, but the readout is descriptive until a holdout or matched comparison is available." | Holdout, matched-market, or matched-customer comparison with the same outcome window. |
| "This trend is spreading quickly." | The story shows vivid examples, but not the full record universe, starting level, or comparable time periods. | "The examples show a pattern worth checking; prevalence is not established without the full denominator and prior-period counts." | Complete record pull, inclusion rules, and counts by period and subgroup. |
| "The brand study proves the media changed opinion." | Respondent balance, exposure leakage, question wording, and uncertainty are not visible in the summary. | "The survey suggests movement in the measured sample, but causal confidence depends on respondent balance, leakage checks, wording, and uncertainty." | Method note with exposed/control construction, field dates, question wording, base sizes, and interval estimates. |
Language that matches confidence
| Evidence level | Better wording | Risky wording |
|---|---|---|
| Decision-grade | "The test supports increasing spend within this audience and window." | "The channel is proven to work everywhere." |
| Strong but bounded | "The records support the claim for the reported period." | "This proves the broader trend." |
| Directional | "The pattern is consistent with lift, but the counterfactual is not fully established." | "The campaign drove the result." |
| Weak signal | "This should trigger a source request or test plan." | "The finding confirms the frame." |
| Unsupported frame | "The available evidence is not enough for the claim." | "The claim is true with caveats." |
Use it with the rest of the library
For media claims, pair this rubric with the media claim audit worksheet, headline and source-mix framing checklist, public records and denominator checklist, and survey and poll claim checklist.
For measurement claims, pair it with the measurement method selector, incrementality test plan template, brand lift readout checklist, MMM causal validity checklist, and private marketplace measurement checklist.
Takeaway
The right goal is not permanent doubt. The right goal is calibrated confidence: strong language for strong evidence, careful language for directional evidence, and no settled frame when the source trail is too thin.