Programmatic measurement
Private marketplace campaign measurement checklist
Organization byline: Measurement Press editorial desk. This page does not list an individual author or reviewer. Read the editorial method and corrections policy.
About 12 min read
Private marketplace and sponsorship campaigns are often bought for context, audience quality, and brand fit. The readout should show whether the campaign delivered that environment before it tries to claim business impact.
Use this checklist before a flight launches and again when the report arrives. It is written for marketers, publishers, agencies, and analysts who need a practical way to separate delivery quality, attention, traffic quality, lead quality, and incrementality.
Imagine a renewal meeting two weeks after a contextual display flight ends. The delivery total looks healthy, a few placements drove efficient traffic, the buyer's sales team marked several leads as unqualified, and there was no holdout. A useful measurement review does not ask which metric can make the campaign sound best. It asks which decision each evidence lane can actually support.
Set the campaign's job
A private marketplace deal should start with one primary job. When the job is vague, every metric becomes available for a positive story after the fact.
| Campaign job | Good primary signal | Useful secondary signal | Readout boundary |
|---|---|---|---|
| Reach a professional context | Qualified impressions in the selected desk, topic, or page group. | Viewability, completion, frequency, and device mix. | Do not call context delivery a sales result. |
| Introduce a product category | Reach and frequency against the intended audience and content context. | Brand search, direct visits, assisted sessions, and content engagement. | These are directional signals unless a counterfactual is built. |
| Drive qualified visits | Clean referral traffic, landing-page engagement, and matched campaign parameters. | Return visits, content depth, newsletter signups, or demo starts. | Click quality is not the same as incremental demand. |
| Support lead generation | Lead quality by source, placement, creative, and follow-up status. | Pipeline stage, disqualification reason, and time to sales contact. | Lead volume without quality can reward weak targeting. |
| Test sponsor fit | Engagement by content desk, creative, and offer type. | Brand lift, search lift, or matched-market signals where available. | A fit test should not be generalized to all inventory. |
The job statement is a guardrail, not a slogan. If the job is professional-context reach, the first question is whether eligible pages, placements, and frequency held. If the job is qualified visits or leads, delivery quality still matters, but the decision cannot stop there.
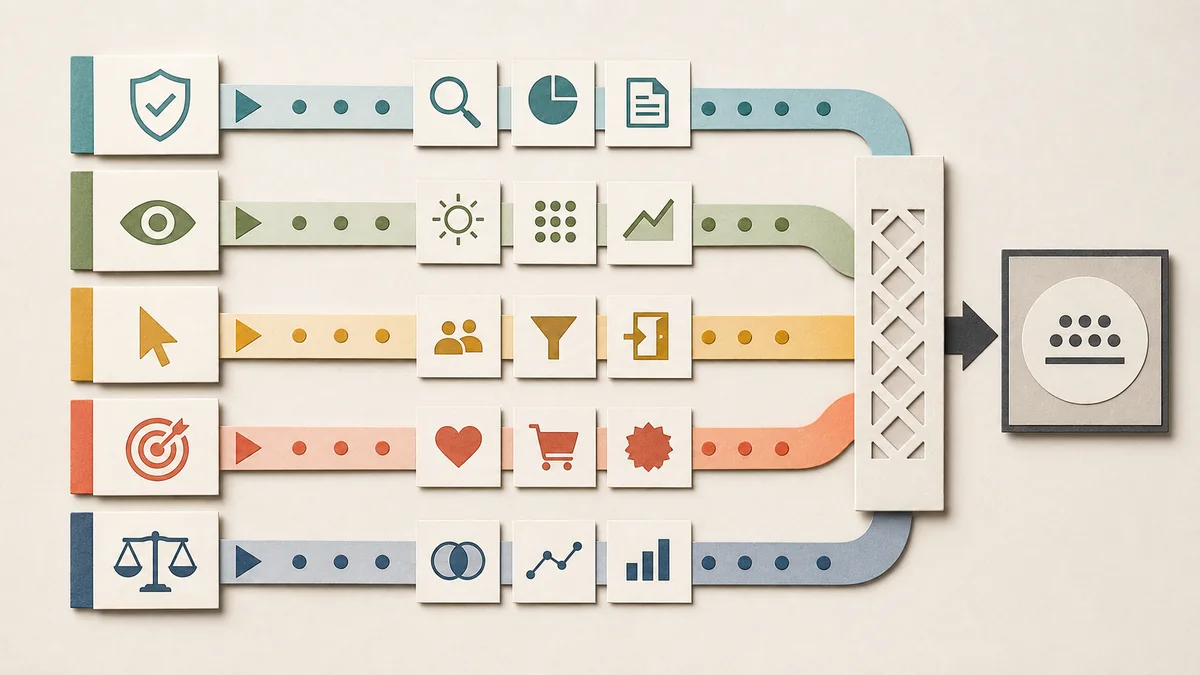
Pre-flight measurement brief
1. Name the decisionWrite the decision the campaign result will inform: renew the package, change creative, shift budget, add a test design, or stop buying the context.
2. Define eligible inventoryList the topic desk, article set, case-study group, placement IDs, device classes, geography, and exclusion rules that count as qualified delivery.
3. Pick one primary outcomeChoose the primary signal before launch. If the campaign is about context, use delivery quality. If it is about visits, use qualified sessions. If it is about pipeline, use lead quality.
4. Preserve the comparisonWhere possible, reserve a holdout geography, time window, audience split, or matched baseline before the campaign starts. If no comparison exists, label the report as descriptive.
5. Lock the readout rulesSet the reporting window, attribution window, minimum delivery threshold, creative naming, URL parameter structure, invalid-traffic review, source-trail fields, and decision threshold before results are visible.
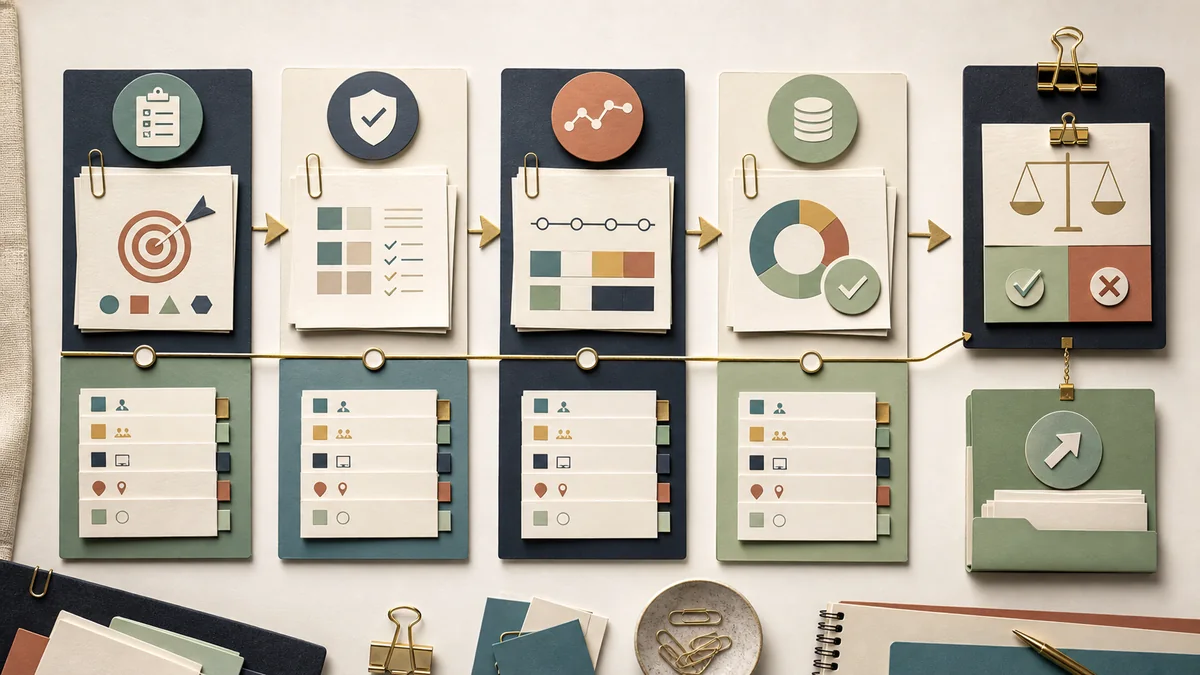
Delivery quality before performance
Delivery metrics do not prove business impact, but they are the first quality gate. A campaign that missed the intended context should not be judged by downstream outcomes alone.
| Check | What the report should show | Why it matters |
|---|---|---|
| Context match | Impressions, clicks, and spend by topic desk, page group, and placement ID. | Confirms the campaign reached the environment that justified the buy. |
| Viewability and format | Viewable rate, measurable rate, creative size, device class, and placement type. | Separates missed exposure from weak message response. |
| Frequency | Reach, average frequency, high-frequency share, and pacing by week. | Prevents a small group of overexposed users from driving the report. |
| Creative rotation | Delivery and engagement by message, asset, landing page, and offer. | Shows whether the result is a context finding or a creative finding. |
| Traffic quality | Bounce, engaged sessions, time on page, return visits, and invalid-traffic review where available. | Keeps cheap clicks from being mistaken for useful attention. |
| Lead quality | Qualified rate, disqualification reason, stage progression, and follow-up timing. | Connects lead volume to the sales process without over-crediting media. |
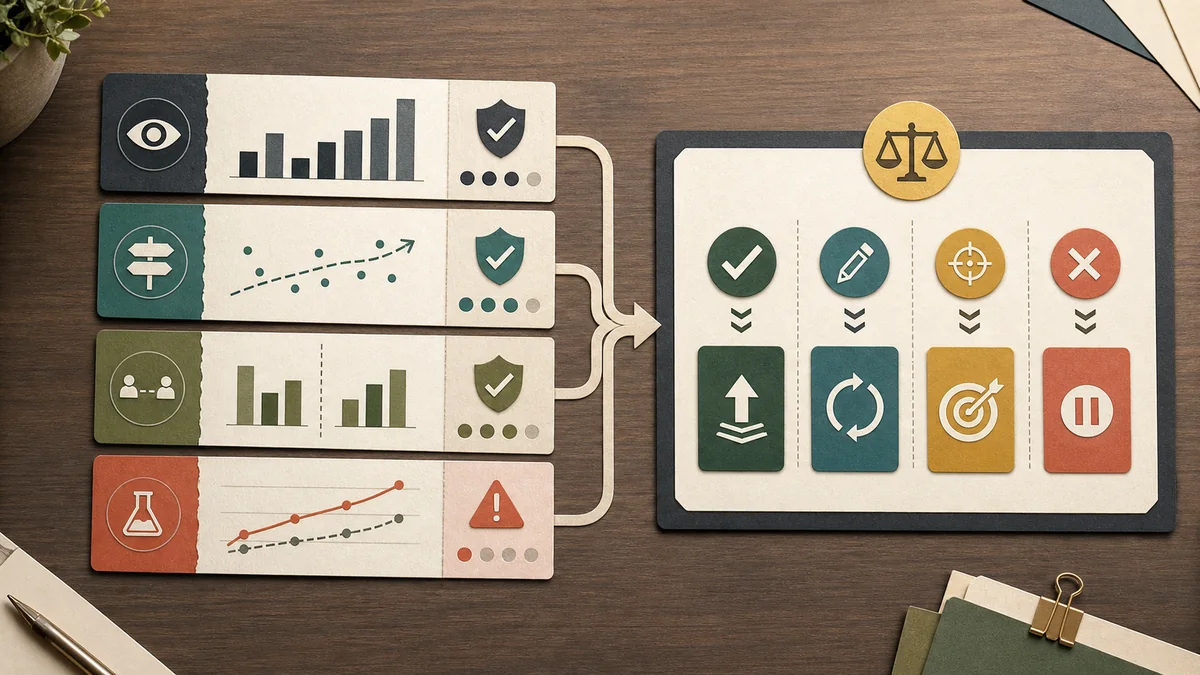
Measurement decision map
Use the first weak lane to set the decision ceiling. That ceiling does not make the campaign bad; it tells the team whether the next action is renewal, repair, deeper testing, or a narrower readout.
| Evidence pattern | What it usually means | Best next decision | Safe wording |
|---|---|---|---|
| Qualified delivery was strong, traffic was engaged, and no comparison was designed. | The context likely reached the intended reader job, but impact is still descriptive. | Renew or expand only with a descriptive readout and a plan for stronger comparison if budget rises. | The campaign delivered the planned context and produced useful engagement signals. |
| Delivery met plan, but traffic or lead quality missed the threshold. | The package may be eligible, while the creative, offer, destination, or lead routing needs repair. | Revise creative, destination, or follow-up before judging the context as weak. | The delivery record was clean, but response quality did not yet support renewal as-is. |
| Traffic and leads improved during the flight, but concurrent activity also changed. | The campaign may have contributed, but other causes are plausible. | Request a matched baseline, holdout, or narrower source trail before causal language appears. | Observed outcomes improved during the campaign window, with attribution limits noted. |
| A holdout or matched baseline exists, but delivery balance or leakage is unresolved. | The test design is promising but the readout needs a quality check before lift language is used. | Hold renewal language until balance, leakage, and uncertainty are documented. | The result is directional until design quality and leakage checks are complete. |
| Delivery missed the promised context or key source fields are missing. | The report cannot answer the original buyer question. | Close the issue, request a makegood or corrected export, and avoid performance conclusions. | The flight should be reviewed as a delivery or reporting-quality issue first. |
Readout template
| Readout question | Evidence to include | Overclaim to avoid |
|---|---|---|
| Did the campaign deliver the intended context? | Qualified delivery by desk, page group, placement, format, and device. | The audience was reached because the total impression count was high. |
| Did creative quality differ? | Results by creative, offer, landing page, and message angle with enough delivery to compare. | The best creative caused demand when it may only have selected high-intent clickers. |
| Did traffic behave differently? | Engaged sessions, return visits, content depth, and landing-page conversion by source. | Higher engagement proves incremental brand or sales lift. |
| Did outcomes improve during the flight? | Outcome trend, baseline period, concurrent activity, seasonality, and known business changes. | The campaign caused every improvement that happened after launch. |
| Was there an incrementality design? | Holdout definition, pre-period balance, assignment rule, leakage check, outcome window, and uncertainty. | A matched dashboard is the same as a lift test. |
| What should change next? | Specific renewal, creative, context, budget, or test-design recommendation tied to the evidence. | The campaign worked because one metric can be framed positively. |
Incrementality options
Not every sponsorship or private marketplace campaign can support a clean causal test. That is acceptable if the readout labels the evidence correctly.
Descriptive readout
Use when there is no holdout or credible baseline. Report delivery quality, engagement, and observed outcomes without causal language.
Matched baseline
Use when a pre-period, similar page group, or similar market gives a better comparison than a raw before-and-after chart. Treat it as directional.
Designed test
Use when geography, audience, timing, or inventory can be held back cleanly. Report balance, leakage, uncertainty, and generalization limits.
Conclusion language
| If the evidence shows | Stronger wording | Weaker wording |
|---|---|---|
| Qualified delivery was strong, but no holdout existed. | The campaign delivered the intended professional context and generated descriptive engagement signals. | The campaign proved incremental demand. |
| One context outperformed others on visits. | This context produced higher observed visit quality and is a candidate for deeper testing. | This context is the highest-ROI inventory. |
| Leads increased, but quality was mixed. | The campaign increased lead volume, while qualification rates require creative or audience adjustment. | The campaign created a strong pipeline result. |
| A designed holdout showed lift with uncertainty. | The campaign produced a measured lift for this audience, window, and design, with the stated uncertainty range. | The result should apply to every future campaign. |
| Delivery missed the planned context. | The flight should be evaluated as a delivery-quality issue before drawing performance conclusions. | The audience did not respond to the message. |
Simulated worked example: set the evidence ceiling
This is a simulated worked example, not a report from a real buyer, publisher, or campaign. It shows how a reviewer can calculate lane-level checks without turning a healthy delivery record into a causal claim.
| Evidence lane | Illustrative count | Calculation | Planning threshold | Result |
|---|---|---|---|---|
| Qualified delivery | 48,000 of 50,000 planned impressions | 48,000 / 50,000 = 96.0% | At least 90% | Pass |
| Measured, viewable exposure | 32,400 of 42,000 measurable impressions | 32,400 / 42,000 = 77.1% | At least 70% | Pass |
| Engaged sessions | 1,260 of 3,000 tagged sessions | 1,260 / 3,000 = 42.0% | At least 40% | Pass |
| Qualified leads | 36 of 90 captured leads | 36 / 90 = 40.0% | At least 35% | Pass |
| Comparison design | No holdout or matched baseline was reserved | 0 / 1 = 0% | Required for causal language | Fail |
Decision: the simulated flight clears its illustrative delivery, exposure, traffic, and lead-quality gates, so a reviewer could recommend a descriptive renewal conversation. The missing comparison design sets the evidence ceiling: the safe conclusion is that the campaign delivered the planned context and produced observed response signals, not that it caused incremental demand.
Assumptions and limits: each percentage uses the denominator shown; the thresholds are planning examples, not industry benchmarks; measurable and viewable are not interchangeable; lead qualification must be defined before the count is made; and the example contains no spend, revenue, leakage, uncertainty interval, or counterfactual. A real readout must replace every illustrative count and threshold with the approved campaign brief and source export.
Preserve the source-field contract
A defensible readout needs a joinable trail from package to destination to outcome. Use a stable campaign ID across the ad-platform export and destination URL, then keep source, medium, campaign, and creative values consistent. Google Analytics campaign-URL guidance documents UTM fields for identifying referring campaigns and warns that inconsistent naming fragments reporting. In the ad-server export, retain the deal or package ID, ad-unit or placement ID, creative ID, delivery status, and reporting window; Google Ad Manager Interactive report dimensions lists current report dimensions and metrics that can be selected for campaign analysis.
Minimum join keycampaign_id + package_id + placement_id + creative_id + destination_url + flight_start + flight_end. If one of these fields changes mid-flight, split the analysis or document the change rather than silently combining unlike rows.
For a causal conclusion, add the assignment rule, treatment and control definitions, leakage check, outcome window, and uncertainty. Google Ads Conversion Lift documentation describes a controlled comparison between people who see ads and people who do not; a tagged click path or matched dashboard is not equivalent to that design.
Primary source trail and method boundary
These sources support the page's campaign-tagging, ad-server field, and controlled-lift method notes. They do not provide the simulated counts, validate any particular package, or establish that a real campaign caused an outcome.
- Google Analytics: URL builders and campaign parameters - documents UTM fields, consistent naming, and where custom campaign data appears in reporting.
- Google Ad Manager: Interactive report dimensions - lists current report dimensions for delivery and campaign analysis; the older Reports tool reference is deprecated.
- Google Ads: About Conversion Lift - describes treatment/control comparisons and why controlled experiments support incremental-conversion claims.
Source-to-decision handoff
Use the source trail as an implementation check, then make the claim from the retained campaign record. A source can explain how a field or study design works; it cannot validate this page's simulated counts or prove that a real package caused an outcome.
| Question | Retain in the review packet | Decision ceiling when missing |
|---|---|---|
| Can destination traffic be joined? | utm_id, source, medium, campaign, content, platform, final URL, and naming version. | Repair tagging or report the result as descriptive; do not infer source-level lift from an unjoined session total. |
| Can delivery be reconciled? | Deal or package, buyer, programmatic channel, placement, creative, impression-counting method, measurement source, and reporting window. | Hold package-quality and renewal conclusions until the export grain and measurement basis are clear. |
| Can outcome impact be tested? | Treatment/control or holdout rule, balance check, leakage review, outcome definition, study window, and uncertainty or study-power record. | Use observed or directional language only; a tagged click path or matched dashboard is not a causal test. |
Reproduction rule: save the source URLs, export date, field dictionary, naming version, eligible-inventory filter, denominator for every rate, and the final wording beside the score rows. If the current source export cannot reproduce the sentence, narrow or remove the sentence before renewal review.
Method boundary
The checklist is an editorial measurement framework, not a claim that any platform, publisher, or private marketplace package will meet the example thresholds. Recalculate from the approved source export, retain the denominator, and lower the conclusion when comparison quality, field continuity, or outcome definitions are incomplete.
Pair with
Use this checklist with the private marketplace readiness index for the full buyer handoff, the media kit for placement IDs and ad-unit paths, the topic taxonomy for reader-intent context, the contextual package proof checklist before pricing or trafficking a package, the contextual package proof sheet for the one-page buyer, operations, and analytics handoff, the private marketplace deal review checklist before activation approval, the creative asset acceptance checklist before display or native files are approved, the landing page launch QA worksheet before paid traffic reaches the destination, the campaign data-layer spec for source-trail fields, the private marketplace readout export sample for package, placement, device, creative, traffic-quality, and outcome-status rows, the private marketplace package performance readout for buyer-ready package language, the private marketplace renewal scorecard before recommending renewal, creative changes, budget shifts, or a lift test, the campaign reporting sample for the finished report structure, the reach and frequency checklist for deduplicated reach, cap, overlap, and high-frequency-tail checks, the incrementality test plan template for causal testing, and the measurement method selector when a campaign result needs stronger evidence than a descriptive readout can provide.