Buyer readiness
Private marketplace readout export sample
Organization byline: Measurement Press editorial desk. This page does not list an individual author or reviewer. Read the editorial method and corrections policy.
About 12 min read
A private marketplace readout is only useful if the export lets a buyer separate package fit, placement delivery, device mix, creative response, traffic quality, and outcome status.
Use this sample as a row-and-column model for contextual display, sponsorship, and curated programmatic campaigns. The values are examples for report structure, not performance benchmarks.
Imagine a renewal meeting is scheduled for Friday morning. The seller has a polished summary slide, the buyer has lead-quality notes from the sales team, and the media lead has a spreadsheet with package, placement, device, creative, and outcome fields mixed together. This page shows how to turn that handoff into a readout export that is useful without pretending the campaign proved lift.
Source trail for the export design
These first-party references anchor the export fields and their limits. Google Ad Manager defines Private Marketplace deals and identifies Deal ID as a reporting dimension; its report documentation warns that placements and key-values can create overlapping rows or require targeted-impression metrics. Google Analytics explains that event parameters preserve interaction context for reporting. Those platform rules support a traceable export, but they do not make the fictional rows below a live report or prove incremental impact.
- Google Ad Manager: About Private Marketplace deals for Preferred Deal and Private Auction definitions.
- Google Ad Manager: Interactive report dimensions for Deal, Deal ID, and delivery dimensions.
- Google Ad Manager: Filter report results for Deal ID filters and report-row behavior.
- Google Ad Manager: Report on targeting keys for key-value and custom-dimension reporting limits.
- Google Analytics: Event parameters for preserving interaction context that feeds dimensions and metrics.
What the sources support in this sample
| Source rule | Use in the export | Still requires production evidence |
|---|---|---|
| Deal ID and report dimensions identify the transaction and delivery breakdown. | Keep deal, package, placement, device, and report-grain fields together so rows can be filtered and reconciled. | A field name does not prove that every request filled through the deal or that the fictional rows came from a live report. |
| Report filters and dimensions affect which rows appear and how they can be interpreted. | Record the selected dimensions, filters, impression-counting method, and measurement source with the export. | Different report setups can expose different rows or conflicts; the export still needs a reproducible configuration record. |
| Targeting-key reporting can use targeted-impression metrics, and key-value overlap or undefined values can change the result. | Keep key definitions, reporting status, date added, and the metric used for targeted delivery beside the row data. | Key-value presence is not additive reach, audience quality, or causal evidence; resolve overlap before ranking cells. |
| Event parameters carry interaction context into dimensions and metrics. | Use stable source-trail and destination fields to explain where a qualified visit or outcome row came from. | Context supports analysis but does not establish lead quality, conversion validity, or incremental impact. |
Boundary: this table translates platform documentation into an export-design decision. It does not validate the simulated rows, certify a production report, or turn descriptive delivery into a lift estimate.
Export grain
Start by choosing the row grain before the campaign launches. If the grain changes after results arrive, the report can hide placement, creative, or device differences that matter to the decision.
| Export level | Use when | Required keys | Weakness |
|---|---|---|---|
| Campaign summary | The buyer needs a short executive view. | campaign_id, package_id, reporting_window, comparison_rule. | Too broad for diagnosing why a result moved. |
| Package by week | The decision is pacing, reach, or renewal at the package level. | campaign_id, package_id, week_start, device_class. | Can average away placement and creative differences. |
| Placement by creative | The decision is placement quality, creative mix, or destination fit. | campaign_id, package_id, placement_id, creative_id, creative_size, destination_id. | Needs minimum delivery thresholds before ranking cells. |
| Outcome status by source trail | The decision depends on qualified visits, leads, pipeline, or matched outcomes. | campaign_id, source_trail_id, destination_id, outcome_status, comparison_rule. | Requires buyer-side status fields and unavailable-field notes. |
Column set
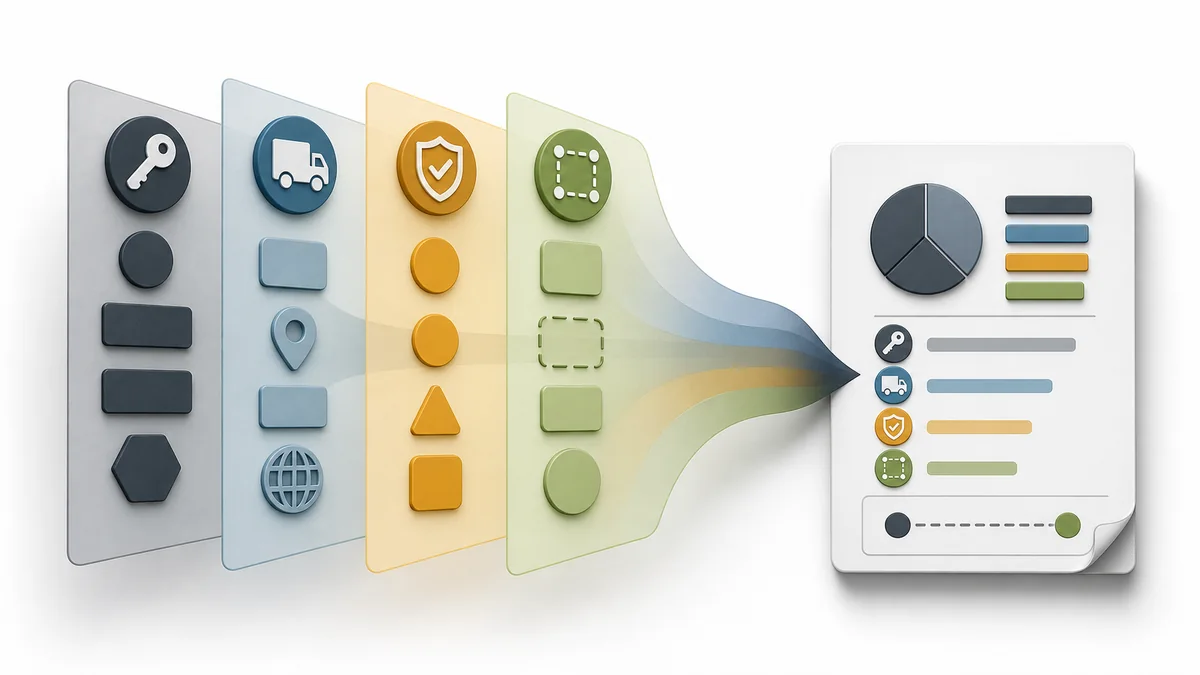
The export should keep commercial, delivery, quality, and conclusion fields together. That makes it harder for a readout to use one strong metric while hiding the field that limits the claim.
| Field | Sample value | Why it belongs in the export | Claim boundary |
|---|---|---|---|
| campaign_id | mp-q3-methods-awareness | Connects proposal, trafficking, delivery, analytics, and invoice records. | Stable naming does not prove performance quality. |
| package_id | measurement-science-desk | Shows the contextual package that was bought. | Package delivery is not the same as audience persuasion. |
| pmp_deal_key | mp-msd-pmp | Connects the transaction route to the package definition. | A deal key is not evidence that every impression matched the intent. |
| placement_id | article-inline-1 | Separates body, rail, archive, native, and post-content delivery. | Placement rankings need device and creative normalization. |
| device_class | desktop | Prevents rail and mobile-capable units from being compared as if they had the same opportunity. | Device class can mix screen size, intent, measurability, and landing-page behavior. |
| creative_size | 728x90 | Shows whether response followed format, message, or placement. | A size can look better because it received better inventory. |
| context_group | measurement method selection | Keeps reader job visible inside the package. | Context response is descriptive unless the comparison is designed. |
| qualified_visit_rule | engaged session, valid geography, non-duplicate | Defines the traffic-quality denominator. | Qualified visits still do not equal incremental demand. |
| outcome_status | qualified lead, disqualified lead, missing status | Prevents raw form fills from becoming the only result. | Buyer-side status must be complete enough to interpret. |
| comparison_rule | prior contextual flight; no holdout | Sets the strongest conclusion language available. | A prior flight is directional, not a protected counterfactual. |
| bounded_conclusion | Observed qualified traffic was strongest in upper-body guide contexts. | Turns fields into a claim that matches the evidence level. | Do not convert observed response into lift language. |
A usable export is not just more columns. It is a field stack: commercial keys say what was bought, delivery context says where the impressions appeared, quality status says which rows can be trusted, and the conclusion boundary says how strong the final claim may be.
Sample export rows
These rows show the minimum shape for a useful readout. A production export can add cost, frequency, geography, date, audience, or order-line fields, but these fields should remain visible in the final interpretation.
| package_id | placement_id | device | size | impressions | viewable rate | clicks | qualified visits | lead status | bounded conclusion |
|---|---|---|---|---|---|---|---|---|---|
| measurement-science-desk | article-inline-1 | desktop | 728x90 | 42,600 | 74% | 171 | 82 | 11 qualified, 5 disqualified, 2 missing | Strong observed response in upper-body guide inventory; compare creative mix before calling the placement best. |
| measurement-science-desk | article-inline-1 | mobile | 320x100 | 31,200 | 67% | 116 | 39 | 4 qualified, 7 disqualified, 1 missing | Mobile clicks produced lower qualified-visit depth; review destination friction before judging media fit. |
| measurement-science-desk | article-rail-1 | desktop | 300x600 | 25,100 | 69% | 43 | 19 | 3 qualified, 2 disqualified, 0 missing | Rail delivery supported desktop reach, but the cell is smaller than inline delivery and should not be ranked alone. |
| buyer-readiness | archive-leaderboard | desktop | 970x90 | 18,400 | 63% | 38 | 14 | 2 qualified, 1 disqualified, 2 missing | Archive discovery created some qualified traffic; it is better evidence for package awareness than lower-funnel impact. |
| buyer-readiness | native-sponsored-card | mobile | fluid | 9,700 | 71% | 61 | 27 | 5 qualified, 3 disqualified, 0 missing | Native card response should be reported separately because format, copy, and reader intent differ from display units. |
Simulated Worked Example: roll up the sample rows
Simulated Worked Example - not a real campaign report or benchmark. Assume the five fictional rows above are complete, deduplicated, and measured under one reporting window. Roll up the rows before ranking placements so the report exposes the denominator, status completeness, and the difference between observed response and causal evidence.
| Calculation | Formula from the sample rows | Result | What the export can support |
|---|---|---|---|
| Total delivery | 42,600 + 31,200 + 25,100 + 18,400 + 9,700 impressions | 127,000 impressions | Defines the denominator for the pooled descriptive readout. |
| Click-through rate | 429 clicks / 127,000 impressions | 0.34% | Describes observed click response; it is not a quality or lift benchmark. |
| Qualified visits per 1,000 impressions | 181 qualified visits / 127,000 impressions x 1,000 | 1.43 | Allows a delivery-normalized descriptive comparison only after keeping placement and device lanes separate. |
| Resolved-status completion | (25 qualified + 18 disqualified) / (25 qualified + 18 disqualified + 5 missing) | 89.58% | Five missing statuses remain open; the qualified-lead interpretation is provisional. |
| Qualification rate among resolved statuses | 25 qualified / (25 qualified + 18 disqualified) | 58.14% | Describes the resolved rows, not every form or visit, and should be recalculated when missing status closes. |
| Inline device contrast | 82 / 42,600 x 1,000 desktop versus 39 / 31,200 x 1,000 mobile | 1.92 versus 1.25 | Routes the next check to destination and device behavior; it does not establish a desktop winner. |
Bounded decisionThe fictional roll-up supports keeping desktop inline, mobile inline, rail, archive, and native rows as separate reporting lanes. It also supports closing the five missing status fields before making a lead-quality recommendation. Because the sample has no randomized holdout or protected matched comparison, it supports descriptive package and placement follow-up—not a claim that the private marketplace caused incremental demand.
Assumptions and limits: the five rows are fictional, complete for this example, deduplicated, and aligned to the same time window; clicks and qualified visits use one stable rule; qualified and disqualified statuses are resolved, while missing status is excluded from the resolved denominator. The roll-up does not control for audience mix, creative rotation, destination friction, auction competition, repeated users, or selection into a deal. A production export should retain the Deal ID, report dimensions, key-value definitions, source-trail parameters, status owner, reporting cutoff, and comparison rule before stronger language is approved.
Simulated Worked Example: export acceptance gate
Simulated Worked Example - not a real campaign report or benchmark. Before a buyer-facing summary is written, score the five fictional rows against six evidence gates. This gate is intentionally stricter than a field-presence checklist: Google Ad Manager distinguishes report dimensions from metrics, targeted-impression handling, and reportable key-values, while Google Analytics event parameters provide context but do not by themselves establish an outcome.
| Gate | Check on these rows | Result | Decision consequence |
|---|---|---|---|
| Stable row grain | Five rows have a declared package, placement, device, and creative-size lane; no row is silently pooled with another. | Pass (5/5) | Keep the lanes separate when reproducing the readout. |
| Commercial and delivery keys | The export design retains campaign_id, package_id, pmp_deal_key, placement_id, device_class, and creative_size as traceable fields. | Pass (6/6 fields) | Allow reconciliation to the proposal, trafficking, and delivery records. |
| Reportability provenance | The fictional rows do not state the selected report dimensions, impression-counting method, Active View measurement source, or whether key-values were reportable/targeted. | Hold (0/4 provenance fields shown) | Do not call the export audit-ready until the report setup and metric provenance are attached. |
| Outcome-status completeness | Resolved statuses are 43 of 48 total statuses; five are marked missing. | Hold (43/48 = 89.58%) | Assign the status owner and keep qualified-share language provisional. |
| Lane separation | All five rows retain device and format context, including the separate mobile native-fluid lane. | Pass (5/5) | Compare like-with-like; do not rank native and display together. |
| Comparison strength | The comparison rule is a prior contextual flight with no randomized holdout or protected matched baseline. | Hold (0/1 protected comparison) | Permit descriptive renewal or retest language only; block lift language. |
Acceptance result: 3/6 gates passFor this fictional export, the next action is revise before renewal language: attach the report configuration and measurement-source notes, resolve the five missing statuses, and define a protected comparison if the buyer needs an incremental-impact claim. Reproduce the score by counting one pass for each row whose result begins with "Pass"; retain every Hold in the denominator rather than treating it as an exception.
What would change the result: a production export could move the provenance gate to Pass by recording the Interactive report dimensions and metrics, the applicable impression-counting method and measurement source, and the key-value reporting mode; it could move the outcome gate to Pass by replacing all five missing statuses with buyer-owned, deduplicated dispositions; and it could move the comparison gate to Pass only after a pre-specified holdout, matched baseline, or other defensible design is documented. These are evidence requirements, not claims that the sample has been run in Google Ad Manager or Google Analytics.
Quality flags
Add quality flags when fields are incomplete or when the row could be misread. A good export makes limits visible before the final slide language is written.
| Flag | Trigger | What to write in the readout | What not to write |
|---|---|---|---|
| low_delivery_cell | Placement, creative, or device cell is below the agreed minimum. | The cell is directional and should be pooled or retested before action. | This cell is the winner or loser. |
| missing_outcome_status | Buyer-side lead, pipeline, or matched-outcome status is incomplete. | Outcome quality is partially observed and may change when status is supplied. | All reported outcomes were qualified. |
| comparison_not_protected | No holdout, randomization, or protected comparison was defined before launch. | The campaign produced observed response under the stated comparison limit. | The campaign generated incremental growth. |
| device_mix_shift | Device share differs materially across placements or creative sizes. | Compare response after separating device and destination behavior. | The highest total response placement is automatically higher quality. |
| creative_rotation_uneven | Creative versions received different inventory, timing, or package mix. | Creative results are confounded by delivery and should guide hypotheses. | The top creative caused the strongest demand. |
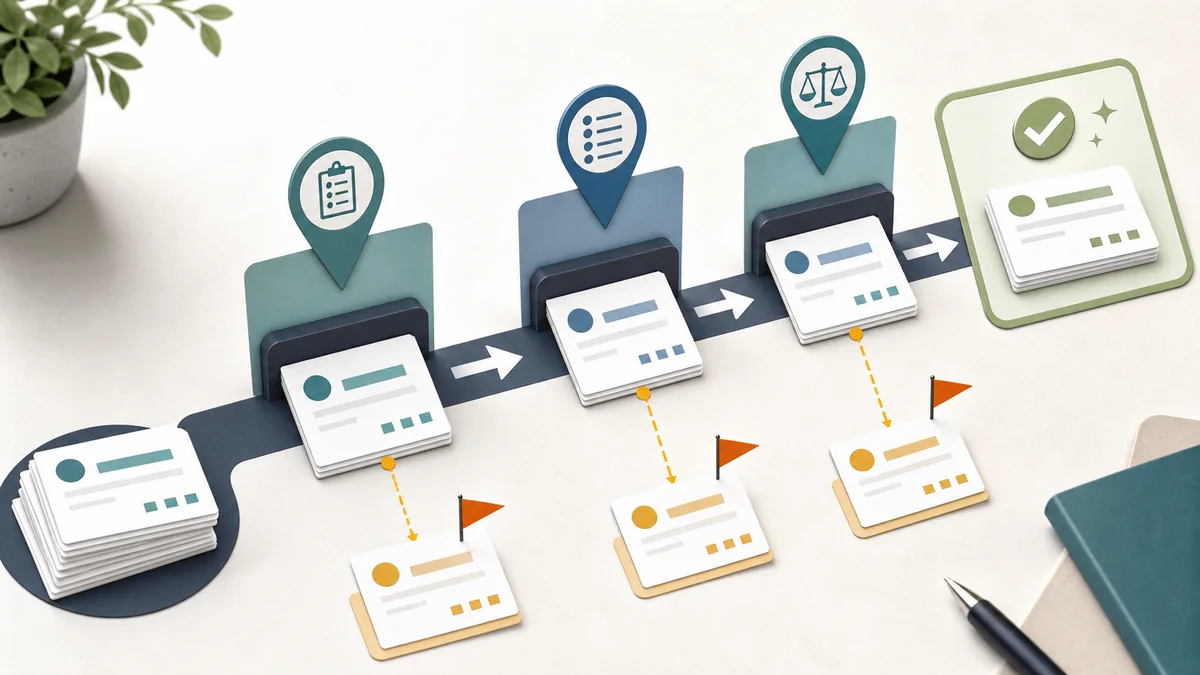
Quality flags are not negative footnotes. They are routing rules. A low-delivery row should be pooled or retested, missing outcome status should be assigned to an owner, an unprotected comparison should block lift language, and an uneven creative rotation should turn the readout into a hypothesis rather than a winner declaration.
Readout summary block
Delivery fitThe campaign delivered in the agreed package and placements, with enough context, device, and creative detail to audit the inventory that carried the result.
Traffic qualityQualified visits were strongest in upper-body guide inventory, but device mix and destination behavior should be reviewed before shifting budget.
Outcome statusLead-quality fields improved the report, but missing status and small cells keep the evidence descriptive rather than causal.
Next decisionRenew only the package and placement mix that matches the buyer's reader-job goal, then add a stronger comparison if the next decision requires lift language.
Decision map for the sample export
The final step is to turn rows into action. The export should not end with a generic performance score. It should say which rows support renewal, which rows need a separate read, which rows need a fix, and which question requires a stronger test.
| Export evidence | Decision it can support | Boundary to keep visible | Buyer-facing next step |
|---|---|---|---|
| Measurement-science desktop inline rows have enough delivery, strong qualified visits, and mostly complete lead status. | Renew a narrower package lane around the strongest reader context. | The row is still descriptive because the comparison was not protected. | Renew the lane and preserve the same row grain for the next readout. |
| Mobile inline rows show clicks but weaker qualified-visit depth. | Review destination friction before judging the media fit. | Device behavior can mix page speed, form design, intent, and measurability. | Fix mobile destination issues, then retest the row rather than dropping the package immediately. |
| Rail delivery is measurable but the cell is smaller than inline delivery. | Use rail as supporting reach evidence, not a ranking winner. | Small cells can move because of sample size, creative mix, or timing. | Pool or retest rail rows before shifting budget based on the table alone. |
| Native-sponsored-card response differs from display placements. | Read native as a separate format lane. | Format, copy, and page context are different enough to make pooling misleading. | Report native separately with its own creative and destination notes. |
| The campaign lacks a reserved holdout or protected matched baseline. | Use directional renewal language, not lift language. | Observed response is not the same as incremental impact. | Plan a holdout, matched market, or stronger baseline before the next report claims lift. |