Incrementality
Incrementality test plan template
Organization byline: Measurement Press editorial desk. This page does not list an individual author or reviewer. Read the editorial method and corrections policy.
About 10 min read
Incrementality work gets weaker when the test is treated as a reporting feature instead of a decision design. A good plan is written before results are visible. It states what decision is being made, what counterfactual is needed, how assignment works, and what result would change behavior.
This template is for marketing teams comparing a campaign, channel, audience, offer, creative, or retail-media package against a credible alternative. It is deliberately plain: if a result cannot pass these checks, it should not be used as a confident budget signal.
Evidence behind this template
These planning rules follow the distinctions in Google Ads current experiment documentation: Conversion Lift describes treatment/control comparisons and incremental conversions; user-based study setup describes study power, holdout size, duration, and tracking readiness; geo-based study setup describes comparable regions and contamination; and the experiments FAQ explains conversion delay, run length, and traffic or budget splits. Platform guidance is not proof that a specific campaign worked, so the plan below keeps the observed test data and decision rule explicit.
Verified source boundary: Google describes study power as a feasibility estimate shaped by historical data, estimated lift, selected conversions, budget, duration, and holdout share; its experiment guidance also warns that overlapping experiments can interfere and recommends allowing for conversion cycles. Use those facts to lock the design and maturity window, not to turn a platform estimate into proof of lift.
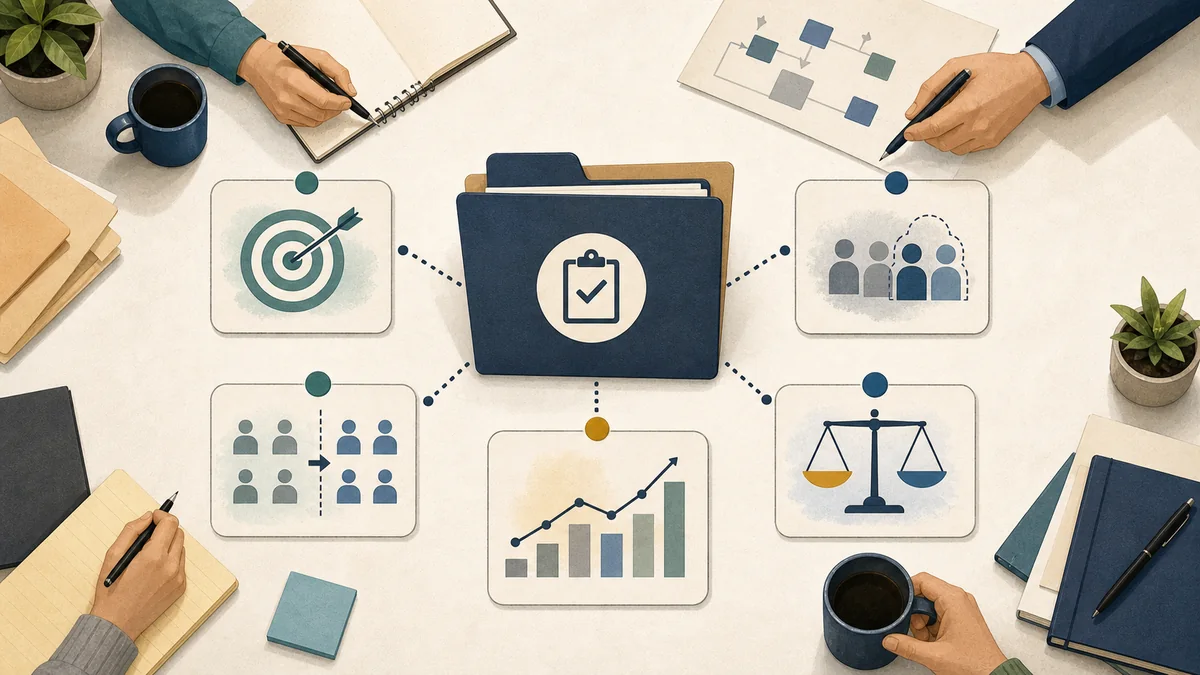
The one-page plan
The one-page plan should make the test answerable by someone who did not sit in the kickoff meeting. If the decision, population, comparison, and action threshold are not explicit, the readout will invite a stronger claim than the design can support.
| Field | What to write before launch | Failure mode it prevents |
|---|---|---|
| Decision | The exact action the result will inform: increase budget, pause spend, change audience, approve a vendor, or redesign the offer. | Running a test that produces an interesting number but no operational choice. |
| Estimand | The causal effect being estimated: incremental conversions, revenue, margin, retained customers, store visits, or another outcome. | Reporting a metric that does not match the business decision. |
| Counterfactual | What would have happened without the tested treatment: no ad, business-as-usual media, different creative, different offer, or delayed launch. | Comparing treatment to an unrealistic baseline. |
| Unit of assignment | User, household, store, market, ZIP code, account, device, or another unit that can be kept meaningfully separate. | Letting exposure spill across treatment and control groups. |
| Eligibility rules | Who can enter the test, when they enter, and which prior customers, employees, outliers, or geographies are excluded. | Changing the population after seeing early performance. |
| Primary outcome | One main outcome with a fixed window and source of truth. | Searching across metrics until one looks favorable. |
| Minimum detectable effect | The smallest effect worth acting on, plus expected sample size and variance assumptions. | Overreading a noisy test that could not detect a useful change. |
| Readout rule | The threshold for action: interval excludes zero, lift exceeds margin hurdle, result clears payback, or test remains inconclusive. | Treating every positive point estimate as a win. |
Simulated pre-launch gate
This is a Simulated Worked Example, not an advertiser result. It shows how to expose the arithmetic before a test is read. Assume 1,000 eligible units are randomized evenly, the primary conversion window is fixed, and every conversion is captured under the same rule.
| Check | Simulated entry | What it permits |
|---|---|---|
| Assignment | 500 treatment units; 500 control units | A balanced comparison, subject to leakage and baseline checks. |
| Primary outcome | 40 treatment conversions ÷ 500 = 8.0%; 30 control conversions ÷ 500 = 6.0% | One fixed-window rate comparison instead of a search across metrics. |
| Lift arithmetic | 8.0% − 6.0% = 2.0 percentage points; 2.0% ÷ 6.0% = 33.3% relative lift | A transparent point estimate. At 1,000 eligible units, the simple rate difference corresponds to 20 additional conversions. |
| Decision rule | Do not scale unless the pre-stated hurdle is at least 1.5 percentage points and the uncertainty interval clears zero. | A point estimate alone cannot trigger a budget decision. |
| Limit | No interval, power calculation, or real campaign data is supplied here. | Use the example to audit a plan, never to claim that lift was established. |
The example changes if assignment is unequal, the conversion window is immature, treatment reaches control, or outcome capture differs between arms. Those changes must be logged before interpretation; otherwise the arithmetic can remain correct while the causal claim becomes unsound.
Pre-launch decision packet
This is a second Simulated Worked Example, built from the 1,000-unit illustration above rather than from a real campaign. The Google Ads links in the evidence section describe incrementality, study setup, feasibility, holdout choices, and contamination; they do not validate these simulated counts, the 1.5-point hurdle, or a budget decision.
| Gate | Simulated record | Status and consequence |
|---|---|---|
| Decision | Scale only when absolute lift is at least 1.5 percentage points and the uncertainty interval clears zero. | Specified. The action rule is written before results are viewed. |
| Assignment | 500 treatment units and 500 control units; one fixed assignment unit; no reassignment after launch. | Pass in the illustration. Audit balance, duplicate identities, and cross-arm exposure in the real packet. |
| Primary outcome | 40 ÷ 500 = 8.0% treatment; 30 ÷ 500 = 6.0% control; 8.0% − 6.0% = 2.0 percentage points, or 20 additional conversions per 1,000 units. | Arithmetic reproducible. This is a point estimate, not proof of lift. |
| Study power | Illustrative baseline 6.0% and 1.5-point minimum detectable effect; no real volume, duration, variance, or platform study-power result is supplied. | Hold. Do not describe the plan as powered or conclusive. |
| Leakage and parity | Simulation flags 0 of 1,000 units, but supplies no real suppression, overlap, exposure, conversion-match, or exclusion log. | Hold. The launch packet needs named counts and reasons before interpretation. |
| Readout | No interval, conversion-lag maturity check, or pre-registered exclusion rule is available in this illustration. | Hold. Revise before launch; never scale from the 2.0-point estimate alone. |
Simulated decision: 2 of 6 gates pass as written, 1 is arithmetic-only, and 3 are held. The correct posture is revise before launch, not “the campaign produced a 33.3% lift.” The packet becomes decision-ready only when the missing study-power, leakage, outcome-parity, lag, and uncertainty evidence is attached under the same definitions.
| Sensitivity case | Recalculation | What changes |
|---|---|---|
| Baseline illustration | 40 ÷ 500 − 30 ÷ 500 = 2.0 percentage points | Above the 1.5-point hurdle, but still held because no interval is supplied. |
| One treatment conversion removed as late or invalid | 39 ÷ 500 − 30 ÷ 500 = 1.8 percentage points | Direction remains above the hurdle; the exclusion rule must have been fixed before viewing results. |
| Three treatment conversions removed as out of window | 37 ÷ 500 − 30 ÷ 500 = 1.4 percentage points | Falls below the hurdle; the action changes to revise or retest. |
| Six control records later flagged as treatment-like | 40 ÷ 500 − 24 ÷ 500 = 3.2 percentage points | Do not celebrate the larger number: post-hoc contamination handling changes the estimand and requires a hold. |
Assumptions and limits: The arithmetic assumes equal assignment, one fixed conversion window, identical outcome capture, and no duplicate or cross-arm records. The numbers are synthetic and cannot establish statistical significance, study power, causal validity, or commercial return. If the assignment unit, holdout share, conversion lag, campaign mix, budget, or geographic contamination changes, rerun the packet and lower the claim ceiling until the new evidence is reviewed.
Design choices
The design choice is really a question about the counterfactual: who or what stands in for the result that would have happened without the tested campaign? The answer determines whether the plan needs user assignment, household assignment, stores, markets, ZIP codes, time windows, or a matched comparison.
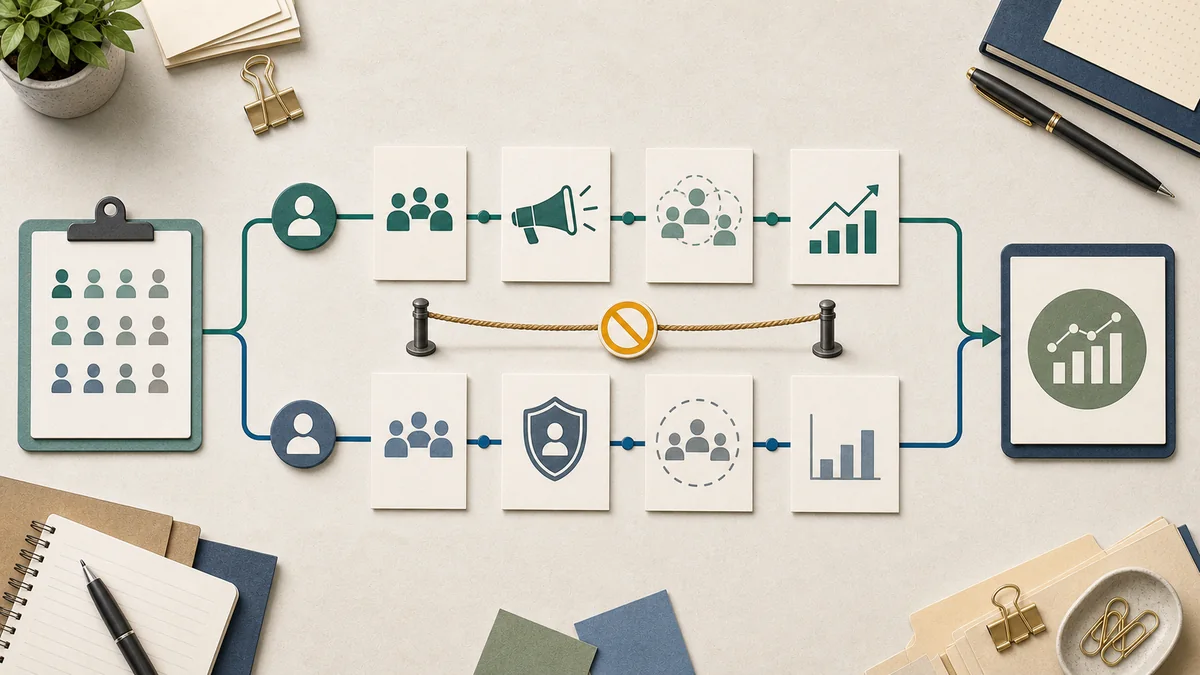
Randomized user holdoutBest when exposure can be controlled at the user or household level and the outcome can be measured consistently for both groups. The main risks are identity gaps, cross-device leakage, suppression failures, and audience changes during the test.
Geo or store testBest when treatment is bought or executed by market, store, or region. Markets should be balanced on pre-period outcome trends, seasonality, media history, price, distribution, and competitive context. A geo test should not rely on one unusually strong control market.
Matched-market designUseful when randomization is not available, but the match must be made before results are visible. Strong matching uses pre-period trend similarity, not only market size or demographic resemblance.
Switchback designUseful when treatment can alternate across time windows, such as bidding rules or merchandising conditions. It works only when carryover is limited and time-period shocks are handled honestly.
Leakage and compliance checks
A lift readout is only as credible as the contrast it preserves. Leakage is any route that lets the control group receive treatment-like exposure or lets the treatment group be measured differently from control. Compliance is the proof that the campaign actually ran as planned.
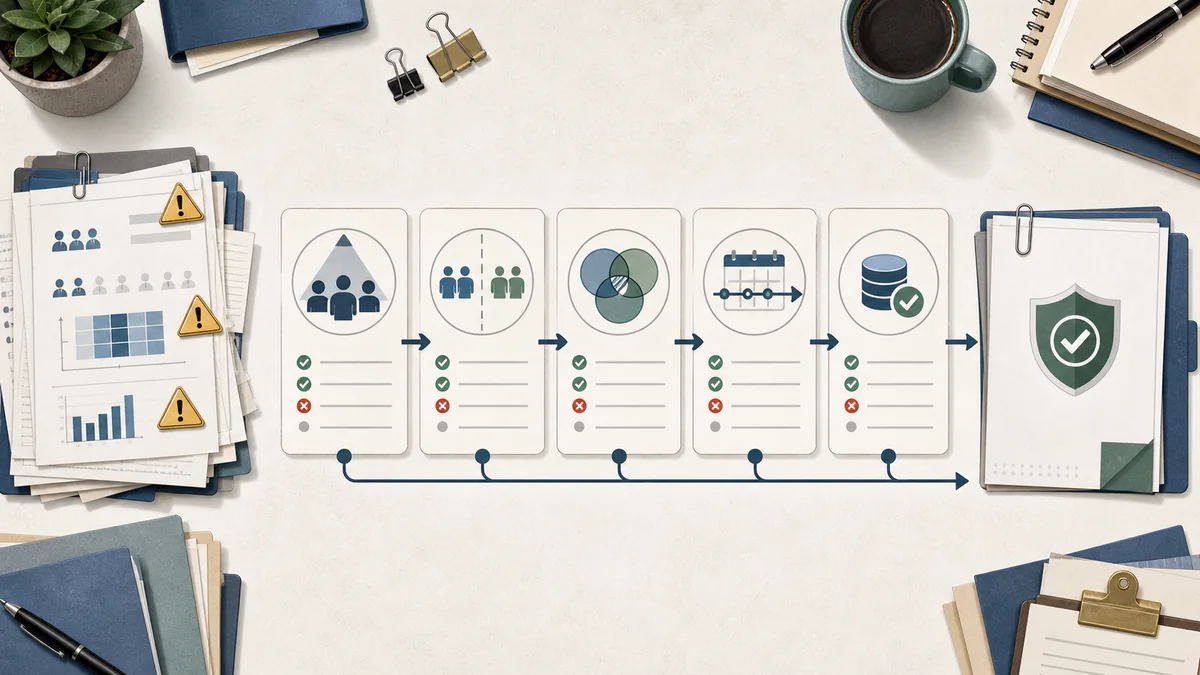
- Control users or markets should not receive the tested exposure through another campaign, reseller, audience extension, or shared household route.
- Treatment delivery should be audited against the planned audience, geography, dates, frequency, and budget.
- Other large changes during the test should be logged: pricing, promotions, inventory, sales coverage, distribution, site outages, and competitor events.
- Outcome capture should be checked equally for treatment and control. A conversion match rate problem can become a fake lift problem.
- Any excluded observations should be named with counts and reasons before final analysis.
Readout table
The readout should map each result pattern to a decision posture. A positive point estimate does not automatically mean scale; an inconclusive result does not automatically mean failure; and a broken contrast should not be rescued with confident causal language.
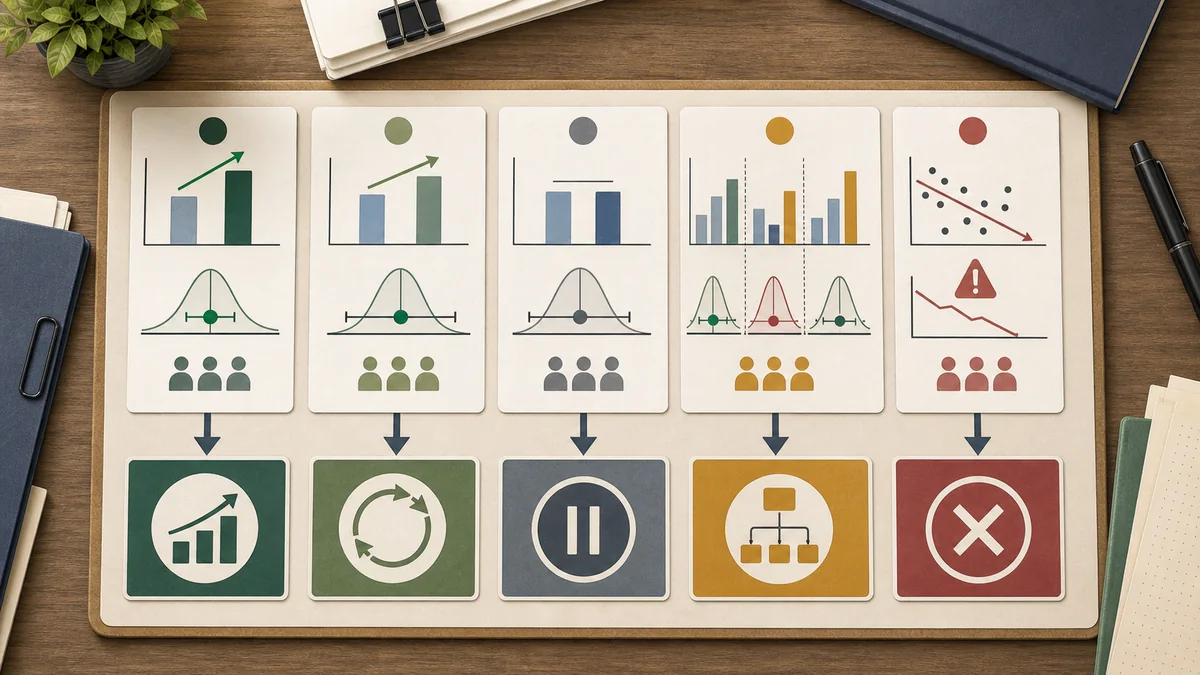
| Result pattern | Reasonable interpretation | Decision posture |
|---|---|---|
| Positive effect, narrow interval, clears profit hurdle | The test supports scaling within the tested population and conditions. | Scale gradually and monitor whether the effect decays. |
| Positive effect, wide interval | The direction is encouraging, but the estimate is too imprecise for a confident decision. | Repeat with more power or lower the decision stakes. |
| Near zero with narrow interval | The tested treatment likely did not create a commercially meaningful effect. | Pause or redesign unless there is a separate strategic reason. |
| Mixed segments | The average hides heterogeneous effects across audiences, geographies, or product groups. | Retest the strongest segment with a pre-stated plan. |
| Broken compliance or leakage | The contrast no longer estimates the intended counterfactual. | Do not treat the result as causal evidence. |
Language to avoid
| Weak claim | Cleaner claim |
|---|---|
| "The campaign drove a 14% lift." | "In this test population and window, the estimated incremental lift was 14%, with the reported interval and caveats below." |
| "The channel works." | "The tested setup produced incremental value under these conditions; other audiences, bids, seasons, and creatives need separate evidence." |
| "The test was inconclusive, but directionally positive." | "The test did not reach the pre-stated decision threshold. The point estimate alone should not justify scale." |
| "Platform attribution confirms the test." | "Attribution can explain observed paths, but the holdout contrast is the causal evidence to inspect." |
Takeaway
An incrementality test is strongest when its humility is designed in. Define the decision, protect the comparison, pre-state the readout, and make uncertainty visible. The goal is not to produce a flattering number. The goal is to learn what the next dollar is likely to change.
Choose the next lift-test check before launch.
Use these routes when the test plan needs a clearer power threshold, leakage review, readout rule, or broader method choice before the campaign result becomes decision evidence.
Method deskPlace the test in the method routeCompare incrementality, MMM, attribution, brand lift, attention, and uncertainty before choosing the evidence standard.
Power checkConfirm the action thresholdTranslate the business hurdle into sample, base rate, effect size, outcome maturity, and allowed decision language.
Leakage reviewProtect the counterfactualCheck suppression, overlap, household spillover, reseller exposure, and observation parity before launch.
Readout QAAudit the finished lift resultInspect assignment integrity, base rates, absolute lift, intervals, exclusions, segments, and generalization limits.