Incrementality
Randomized lift test readout checklist
Organization byline: Measurement Press editorial desk. This page does not list an individual author or reviewer. Read the editorial method and corrections policy.
About 12 min read
A randomized lift test can be the cleanest evidence a campaign team receives. It can also be misread when the report hides assignment details, treatment leakage, weak outcomes, noisy intervals, or segment cuts chosen after the result was visible.
Use this checklist after a conversion-lift, brand-lift, store-lift, or account-level experiment arrives. The question is not whether the report contains a positive number. The question is whether the design still estimates the effect the decision needs.
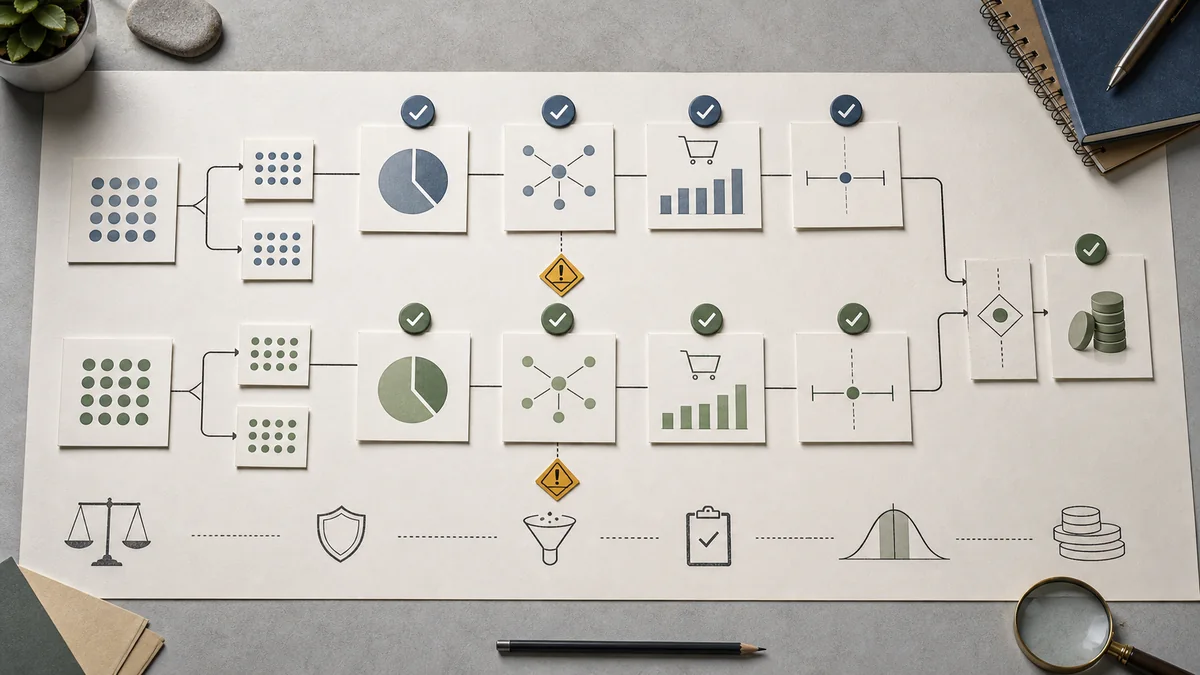
What must be visible first
| Readout field | What to check | Why it matters |
|---|---|---|
| Decision | The budget, audience, creative, market, or vendor decision the test was meant to inform. | A precise test can still be irrelevant if it answers the wrong business question. |
| Assigned unit | User, household, account, store, market, device, or another unit, plus why that unit could be separated. | The effect is only as credible as the separation between treatment and control. |
| Randomization rule | How eligible units were assigned, when assignment happened, and whether assignment stayed fixed. | Post-assignment filtering can turn a randomized test into a selected comparison. |
| Eligible population | Inclusion rules, exclusions, customer status, geography, device coverage, and any minimum activity rules. | The result should not be generalized beyond the population that could enter the test. |
| Exposure delivery | Impressions, reach, frequency, budget, pacing, creative, placement, and delivery quality by treatment group. | A weak or uneven treatment can produce a weak result for operational reasons, not because the idea had no effect. |
| Control protection | Suppression logs, control exposure, overlapping campaigns, partner delivery, and household or account spillover. | A contaminated control group shrinks or distorts the measured contrast. |
| Outcome source | Conversion, revenue, margin, lead quality, brand metric, store visit, or retention definition, with the data owner and lag. | Outcome data quality determines whether the lift number measures the decision outcome or a convenient proxy. |
| Uncertainty | Confidence or credible interval, sample base, minimum detectable effect, and the pre-stated decision threshold. | A positive point estimate is not enough when the interval is too wide for the decision. |
Assignment integrity checks
Balance before exposureTreatment and control should look similar on pre-period outcomes, customer mix, geography, device coverage, sales status, and prior engagement. Randomization does not excuse skipping balance checks when the sample is small or filtered later.
Stable membershipThe report should show whether units stayed in their assigned cells. Removing low-activity users, unmatched records, or difficult geographies after assignment can make the treatment group look cleaner than the control.
Equal observationTreatment and control outcomes should be captured with the same rules. If buyer-side matching, store reporting, CRM status, or survey recruitment differs by cell, the readout may be measuring observation quality.
Control leakageAsk how many control units received the tested exposure through audience extension, retargeting, reseller media, shared households, sales outreach, or another campaign. The readout should state how leakage was estimated.
Lift math that should be shown
A credible readout gives enough arithmetic to reconstruct the claim. Relative lift alone is not enough because it hides the base rate, the absolute effect, and the commercial scale.
| Metric | Useful readout | Common weak version |
|---|---|---|
| Treatment and control base | Assigned units, analyzed units, exposed units, matched units, and exclusions by cell. | Only reporting total conversions or total survey completes. |
| Base rates | Treatment outcome rate and control outcome rate with the same denominator definition. | Only reporting a percentage lift. |
| Absolute lift | Percentage-point difference between treatment and control. | Only reporting relative lift, which can sound large when the base rate is small. |
| Incremental outcome count | Incremental conversions, qualified leads, revenue, margin, or brand responses with the readout window. | Reporting attributed outcomes as if they were incremental outcomes. |
| Interval and power | Uncertainty interval, minimum detectable effect, and whether the test could detect the action threshold. | Calling a noisy positive estimate a win without showing precision. |
| Commercial threshold | Lift translated into margin, payback, qualified pipeline, or another pre-stated decision hurdle. | Stopping at statistical lift even when the effect is too small to matter. |
Source and method notes
This checklist treats a lift readout as an evidence chain, not just a platform headline. Google Ads' official Experiment Center documentation distinguishes campaign experiments from lift studies and describes randomized treatment and control comparisons as the basis for estimating incremental impact. Read the Google Ads Experiment Center documentation.
For the surrounding test plan, Google's experiment guidance recommends a stated hypothesis, a limited test variable, and success metrics chosen before the result is visible. Those practices support the pre-stated thresholds and segment discipline used here. Read Google's experiment guidance.
If the outcome is assembled from GA4, document the event parameters and conversion definition that create the denominator. Google Analytics explains that event parameters add context to an interaction and that conversions are created from Analytics events, so a named outcome still needs a stable collection and counting rule. These official pages were re-read for this source trail; their definitions support the checklist's field requirements but do not validate this page's fictional counts. GA4 event parameters and GA4 conversions.
Simulated worked example: a favorable estimate that stays in learning language
Simulated Worked Example. The numbers below are fictional and are included to make the arithmetic reproducible. They are not a report from a real advertiser, platform, or campaign.
Assume a test assigns 20,000 units to treatment and 20,000 to control. After the same 500 pre-specified exclusions in each cell, both groups have 19,500 analyzed units. Treatment records 585 qualified conversions; control records 507. The readout also estimates that 390 control units saw the tested exposure through an overlapping campaign, and the pre-stated action threshold is +0.50 percentage points.
| Calculation | Arithmetic | Result |
|---|---|---|
| Treatment rate | 585 ÷ 19,500 | 3.00% |
| Control rate | 507 ÷ 19,500 | 2.60% |
| Absolute lift | 3.00% − 2.60% | +0.40 percentage points |
| Relative lift | 0.40% ÷ 2.60% | +15.38% |
| Estimated incremental conversions | 19,500 × 0.004 | 78 |
| Control leakage rate | 390 ÷ 19,500 | 2.00% |
Suppose the illustrative uncertainty interval around absolute lift is +0.05 to +0.75 percentage points. The point estimate is favorable, but it is below the +0.50-point action threshold, the interval spans outcomes below that threshold, and 2.00% control leakage weakens the comparison. The bounded decision is to fix suppression, verify the outcome rule in both cells, and rerun or extend the test—not to claim that the campaign proved scalable incremental demand.
Assumptions and limits: the example assumes equal analyzed denominators, a qualified conversion counted once per unit, and a descriptive leakage estimate. It does not estimate a leakage-corrected effect, confidence level, cost, margin, or power. Those require the actual assignment log, outcome extract, test design, and pre-stated analysis plan.
Readout acceptance gate: when the lift can change the decision
Simulated Worked Example. This gate applies the page's fictional 20,000-per-cell example. It is a review worksheet, not evidence from a real campaign. A single favorable rate does not pass the gate unless its denominator, comparison, uncertainty, and decision threshold are visible together.
| Gate | Evidence in the example | Result |
|---|---|---|
| Assignment and denominator | 20,000 assigned per cell; 500 pre-specified exclusions per cell; 19,500 analyzed per cell. | Pass |
| Outcome parity | 585 and 507 qualified conversions are counted once under the same stated analyzed-unit denominator. | Pass, pending actual outcome-source verification |
| Reconstructable lift | 585 / 19,500 = 3.00%; 507 / 19,500 = 2.60%; absolute lift = +0.40 points; 19,500 x 0.004 = 78 estimated incremental conversions. | Pass |
| Control protection | 390 control units saw the tested exposure through overlap; 390 / 19,500 = 2.00% leakage. | Hold: suppression fix or a bounded leakage analysis is required |
| Uncertainty against threshold | Illustrative interval is +0.05 to +0.75 points; the action threshold is +0.50 points, so the interval includes outcomes below the threshold. | Hold: do not call this a threshold-clearing win |
| Decision scope | The example has no cost, margin, power, or leakage-corrected estimate. | Hold: learning or retest language only |
Worksheet result: 3 of 6 gates pass. The reproducible conclusion is that the arithmetic can be checked, but the example does not justify a scale claim. To move beyond learning language, add the actual outcome-source audit, protect or model the control group, report the uncertainty method and power against the commercial threshold, and translate the effect into the decision's cost or margin rule. If any of those fields remain missing, preserve the missing rows in the review denominator and downgrade the claim.
What would change the result: a protected control, equal outcome capture, an uncertainty interval whose lower bound clears the pre-stated threshold, and a documented margin or payback rule could support a bounded scale decision inside the tested population. None of those facts is supplied by this fictional example.
Lift readout quality score
Score the readout before the number moves into a renewal or scale memo. The point is to separate a valid randomized design from a report that only keeps the word randomized after filtering, leakage, weak outcome capture, or interval width has already weakened the contrast.
| Review field | Green | Yellow | Red |
|---|---|---|---|
| Assignment record | Eligible units, assignment time, cell counts, and post-assignment exclusions are visible by treatment and control. | The design is named, but one eligibility or exclusion field still needs documentation. | The report starts from analyzed or exposed users and does not show who was originally assigned. |
| Control protection | Suppression, overlap, partner delivery, household or account spillover, and leakage estimates are shown together. | Leakage is possible, but the report bounds the affected rows and downgrades language. | Control units could receive the tested message through another route and the readout treats them as clean. |
| Outcome parity | Treatment and control outcomes are collected with the same data owner, match rule, lag window, and suppression standard. | Outcome capture is mostly aligned, but one source, delay, or match-rate gap limits broad claims. | One cell is easier to observe, match, survey, or qualify than the other. |
| Lift math | Base rates, absolute lift, relative lift, incremental count, interval, sample base, and decision threshold are all visible. | The direction is useful, but one arithmetic field or threshold link is missing. | The readout relies on a relative lift headline or attributed outcomes without enough arithmetic to reconstruct it. |
| Segment discipline | Important segment reads were pre-stated and each segment has treatment/control bases and uncertainty. | Segment results are useful for learning, but not strong enough to concentrate budget. | The strongest segment is chosen after the fact and presented as the main result. |
If any row is red, keep the result out of proof language. If two or more rows are yellow, use the readout to design the next test or operating fix before asking for a larger budget decision.
Segments and timing
- Segment reads should be planned before the result is visible or clearly labeled exploratory.
- Segment bases should show treatment and control counts, not only the strongest lift cells.
- Timing windows should include the expected response lag and avoid stopping on the first favorable week.
- High-value outliers should be handled with a rule set before the readout, especially for revenue or margin outcomes.
- If the test reports new customers, repeat customers, leads, or store visits separately, each outcome needs its own denominator and decision limit.
Decision language by result pattern
| Pattern | Careful interpretation | Budget posture |
|---|---|---|
| Positive effect, clean assignment, narrow interval, clears margin hurdle. | The test supports scaling within the tested population, creative, bid, season, and outcome window. | Scale gradually and monitor decay, saturation, and audience expansion effects. |
| Positive point estimate, wide interval, does not clear the pre-stated threshold. | The test is not strong evidence even if the direction is favorable. | Repeat with more power or lower the decision stakes. |
| Near-zero estimate with a narrow interval around the action threshold. | The tested setup likely did not create a commercially meaningful effect. | Pause, redesign, or reallocate unless another strategic objective is documented. |
| Positive aggregate but weak or contradictory planned segments. | The average may be hiding heterogeneous effects or a fragile subgroup result. | Retest the segment with a locked plan before concentrating spend. |
| Control leakage, changed eligibility, or unequal outcome capture. | The contrast no longer cleanly estimates the intended counterfactual. | Use the report operationally, but downgrade causal language. |
Worked readout downgrade
A campaign readout reports a 12% relative lift and calls the test a clean randomized win. The reviewer reconstructs the report and finds three limits: control leakage from an overlapping retargeting campaign, a lower CRM match rate in control, and an interval that includes effects below the margin threshold agreed to before launch.
The decision should not say that the campaign proved scalable incremental demand. A cleaner memo would say the tested setup produced a favorable point estimate, but the contrast is weakened by leakage and unequal observation, and the effect is not precise enough to clear the action threshold.
The next action is bounded: fix suppression rules, align outcome matching by cell, keep the threshold visible, and rerun or extend the test before shifting broad budget. If the same direction repeats with a protected control and a narrower interval, the team can move from learning language to scale language inside the tested population.
Questions for the readout call
- What was the exact assignment unit, and how was assignment protected after launch?
- How many treatment and control units were removed after assignment, and why?
- How much control exposure or cross-cell leakage was observed or estimated?
- Are the treatment and control base rates, absolute lift, relative lift, and interval all visible?
- Which segment cuts were pre-stated before the result, and which were discovered afterward?
- What decision threshold did the team agree to before seeing the lift number?
Takeaway
A randomized test deserves more trust than ordinary attribution, but it still needs inspection. If assignment, control protection, outcome capture, and uncertainty are visible, the result can guide a bounded decision. If those pieces are missing, the lift number may be a polished version of a weaker comparison.
Choose the follow-up before the lift claim hardens.
Use these routes when a randomized lift result needs a stronger power check, leakage review, campaign decision record, or worked failure-mode comparison before it supports budget language.
Power checkCompare lift to the thresholdCheck whether the design could detect the smallest effect that would change the campaign decision.
Leakage reviewAudit control exposureReview suppression, cross-cell exposure, overlap, household spillover, and downgrade rules for contaminated tests.
Readout QAConvert evidence into decision languageSeparate delivery quality, outcome maturity, comparison strength, uncertainty, exclusions, and final posture.
Failure modesCompare against worked examplesUse selection, targeting, timing, survey, and attribution cases before generalizing a favorable result.