Incrementality
Comparison market and holdout planning guide
Organization byline: Measurement Press editorial desk. This page does not list an individual author or reviewer. Read the editorial method and corrections policy.
About 11 min read
Most advertising measurement claims depend on one quiet question: compared with what? A campaign can look persuasive when the comparison group was easier to convert, exposed through another route, already trending differently, or chosen after the result was visible.
This guide helps a team choose the right comparison before launch, protect it during the campaign, and write a readout that does not claim more than the design can support.
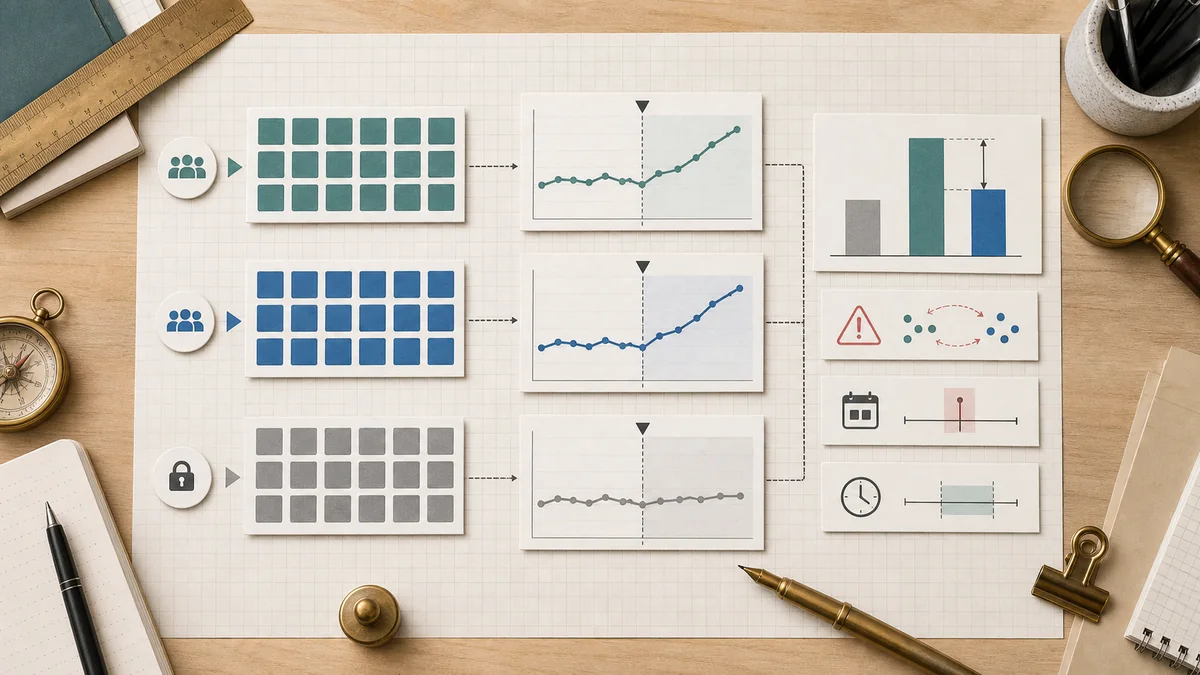
Choose the comparison type
| Design | Use when | Main risk | Minimum protection |
|---|---|---|---|
| User or household holdout | Exposure can be suppressed for eligible users, households, accounts, or devices. | Identity gaps, cross-device exposure, or other campaigns reaching the control group. | Fixed eligibility, suppression audit, exposure leakage check, and one primary outcome window. |
| Geo or store holdout | Media, retail activity, pricing, or operations can be changed by market, store, or region. | Markets differ in trend, seasonality, distribution, or competitor pressure. | Pre-period trend checks, matched controls, logged local events, and market-level readout. |
| Matched-market comparison | Random assignment is not practical, but untreated markets can be chosen before launch. | Convenient controls that match on size while missing the business trend. | Matching locked before results, placebo period checks, and sensitivity analysis. |
| Business-as-usual benchmark | No clean holdout exists and the decision can tolerate weaker evidence. | Seasonality, pricing, distribution, or demand changes masquerade as campaign impact. | Plain language that labels the result directional rather than causal. |
The pre-launch planning sheet
The planning sheet should be written before the campaign team can see the answer. It does not need to be long. It needs to remove avoidable judgment calls from the readout.
DecisionName the action the result will inform: renew a package, scale spend, change audience, adjust bids, approve a market rollout, or pause the tactic.
Eligible populationDefine who can enter treatment or control before exposure begins. Include geography, customer status, product availability, audience rules, and any exclusions.
Comparison ruleExplain how the control group, holdout, or matched market is chosen. The rule should not depend on which option later produces the strongest lift.
Primary outcomeChoose one outcome with a source of truth, reporting lag, and fixed readout window. Keep secondary metrics useful but clearly subordinate.
Downgrade triggersList events that would weaken the claim: suppression failure, budget underdelivery, tracking changes, stockouts, price changes, overlapping launches, or large unplanned promotions.
Stress-test the holdout tradeoff
Use illustrative planning assumptions to see how holdout share changes the treatment sample and the opportunity cost of withholding exposure. This is arithmetic for a planning conversation, not a sample-size, power, or uncertainty model.
+120.0 expected incremental conversionsTreatment and holdout counts will appear here.
Defaults are a simulated planning example, not a forecast. A larger holdout can increase the control sample while withholding more exposure; a smaller holdout preserves more delivery but may produce less information. Real study feasibility also depends on historical volume, conversion definitions, study duration, traffic split, conversion lag, contamination, and uncertainty.
Score the comparison before launch
A fast comparison score keeps the team from discovering the evidence standard only after the readout is persuasive. It is not a statistical model. It is a pre-launch decision rule for deciding whether the campaign can support lift language, directional language, or only operational reporting.
| Factor | Green-light condition | Directional-only condition | Downgrade trigger |
|---|---|---|---|
| Assignment rule | Treatment and control are assigned or matched before launch and cannot be swapped after results are visible. | Controls are pre-selected, but the rule depends on judgment rather than randomization. | Controls are replaced, trimmed, or explained away after the first result is known. |
| Pre-period trend | Treatment and control move similarly across the same business cycle before launch. | Levels match, but one side is already accelerating or decelerating. | The campaign group was already improving faster before media changed. |
| Exposure separation | Control units have a documented suppression path and a leakage audit. | Some spillover is possible, but the team can estimate where it happened. | Control users, stores, or markets receive meaningful treatment through another route. |
| Outcome source | The primary outcome has a stable definition, source of truth, and reporting lag. | The outcome is useful but depends on matching, modeled status, or delayed closeout. | The outcome definition changes, excludes weak rows, or arrives from a different system mid-test. |
| Operating context | Price, distribution, sales coverage, inventory, and local events are logged and materially similar. | One side has known changes that can be disclosed and bounded. | A major promotion, stockout, sales push, or local event explains the observed movement. |
If two or more factors are directional-only, write the test plan as a monitored comparison unless the team can redesign assignment, extend the pre-period, or narrow the decision. If any downgrade trigger is likely before launch, the strongest honest result is usually a learning readout, not a causal lift claim.
Primary source trail and a simulated holdout check
The Google Ads Conversion Lift documentation defines incrementality through a controlled comparison between people who see ads and a control group that does not. Google’s Experiment Center methodology describes randomized experiment groups and lift studies that can split an eligible audience by user or geography. Its holdout setup guidance notes the tradeoff between a larger holdout and the opportunity cost of withholding exposure. For the readout itself, Google’s Conversion Lift metric definitions distinguish incremental conversions, relative lift, and attributed conversions.
| Source | It establishes | It does not establish |
|---|---|---|
| Conversion Lift overview | Incrementality is estimated by comparing a treatment group that sees ads with a control group that does not. | That an arbitrary before-and-after or matched-market result is causal. |
| Experiment Center | Google describes randomized experiment groups and separates campaign-setting experiments from lift studies. | That every platform, audience, or geography has the same eligibility, power, or implementation quality. |
| Holdout setup guidance | Holdout size involves a tradeoff between study sensitivity and the opportunity cost of withholding exposure. | The appropriate holdout fraction for a specific business without its history, volume, and decision threshold. |
| Conversion Lift metrics | Incremental conversions and relative lift use treatment/control differences, while attributed conversions follow configured tracking rules. | That the fictional arithmetic below is a measured Google Ads result or has passed uncertainty and maturity checks. |
Simulated worked example - not a real campaign, study, or forecast: assume a pre-registered holdout has 2,000 eligible records in each arm, uses the same 30-day conversion definition, and protects the control from the tested ad. Treatment records 120 conversions; control records 90.
| Measure | Calculation | Interpretation |
|---|---|---|
| Treatment rate | 120 / 2,000 = 6.0% | Observed conversion rate for the simulated exposed arm. |
| Control rate | 90 / 2,000 = 4.5% | Observed rate for the simulated counterfactual arm. |
| Absolute difference | 6.0% - 4.5% = 1.5 percentage points | The unadjusted between-arm difference under the stated design. |
| Relative lift | 1.5% / 4.5% = 33.3% | A relative comparison whose control denominator must be named. |
| Treatment-sized increment | 2,000 x 1.5% = 30 | An illustrative planning quantity for this tested population. |
The narrow conclusion is: “Under the simulated assignment, conversion was 1.5 percentage points higher in treatment, equivalent to 30 additional conversions at the treatment-group size.” That is not proof that the campaign caused 30 conversions if assignment, pre-period balance, exposure separation, outcome maturity, or competing events are not documented. If market populations differ, calculate rates first rather than subtracting raw counts; if the result is generalized beyond the tested markets or users, label that as an additional assumption. A real readout should attach the assignment rule, balance checks, leakage audit, outcome definition, maturity date, uncertainty interval, exclusions, and deviations from plan.
A reproducible launch-decision gate
Simulated planning packet - not a real campaign, study, or forecast: use this gate before calling a comparison ready for a causal-lift readout. Mark each row 1 only when the packet contains the stated evidence; do not infer a pass from a positive forecast or an attractive matched-market story.
| Gate | Packet evidence | Simulated result |
|---|---|---|
| Assignment | Eligible treatment and control units, assignment rule, and lock date are recorded before delivery. | 1 |
| Pre-period fit | Comparable trends are shown for the same outcome, cadence, and business cycle. | 1 |
| Exposure separation | Suppression or geographic delivery logs can identify control leakage. | 0 — reseller exposure is not logged. |
| Outcome maturity | One outcome definition, source, reporting lag, and finalization date are named. | 1 |
| Operating context | Price, inventory, distribution, promotions, and local events are logged by comparison unit. | 0 — distribution changes are only described in a narrative. |
| Readout bound | The report names its uncertainty method, exclusions, and the decision it can actually inform. | 1 |
Reproduce the result: add the six binary entries: 1 + 1 + 0 + 1 + 0 + 1 = 4; divide by six: 4 / 6 = 66.7%. In this simulated packet, the team may use the result to repair leakage logging and document distribution changes, but it must not label a later difference as causal lift. A six-of-six score is not a statistical proof: it only confirms that the minimum decision packet is available for review.
The source trail above supports the controlled-treatment/control framing and the difference-based lift definitions. It does not establish that every matched-market design is randomized, that a positive difference will be statistically reliable, or that a tested result will transfer to other markets, products, or time periods.
Balance checks that matter
| Check | What to compare | Why it matters |
|---|---|---|
| Starting level | Revenue, conversions, traffic, account base, distribution, store count, or eligible customers before launch. | A much larger or smaller control can make normal movement look like lift. |
| Pre-period trend | Daily or weekly movement before treatment, including seasonality and promotion cycles. | A treatment group already accelerating before launch is not a neutral comparison. |
| Outcome volatility | Historic swings, outlier weeks, small-market instability, and high-value transactions. | A noisy comparison can produce confident-looking but fragile readouts. |
| Business drivers | Price, inventory, retail distribution, sales coverage, product launches, local events, and competitor pressure. | Untracked operating changes can become hidden causes in the readout. |
| Exposure separation | Suppression logs, geography boundaries, audience extension, frequency overlap, and partner delivery. | A control group that receives the treatment no longer estimates what would have happened without it. |
Simulated worked example: when to downgrade the claim
Simulated worked example - not a real campaign or retailer case: A regional retailer wants to test extra media in eight treatment markets and compare them with eight matched markets. The markets are similar in starting revenue and store count, but the treatment markets had a distribution expansion two weeks before launch and were already trending upward. The plan can still teach the team something, but it should not be sold as a clean causal test unless the design is repaired before launch.
| Finding before launch | Why it weakens the readout | Better move | Allowed language if unchanged |
|---|---|---|---|
| Treatment markets already outpaced controls in the pre-period. | The post-period difference may extend an existing trend rather than measure media impact. | Rematch on trend, add more pre-period weeks, or choose a different treatment set. | Observed markets outperformed selected controls during the campaign window. |
| One side received new product distribution before the campaign. | Availability can create revenue movement without any advertising effect. | Exclude affected markets, wait for distribution to stabilize, or make distribution a documented covariate. | The result is directional because operations changed near launch. |
| Control markets may receive reseller, social, or national media exposure. | Leakage compresses the difference and makes the control group a partial treatment group. | Audit delivery logs by market and write a leakage threshold before launch. | The comparison estimates performance under partial spillover, not a clean no-media counterfactual. |
| The readout goal is a national budget decision. | Eight markets may not represent national seasonality, distribution, or competitive pressure. | Frame the result as a market-level learning test and plan a broader follow-up if the signal holds. | This market set supports a next-test decision, not national proof. |
Protect the control during the campaign
- Keep treatment and control eligibility fixed unless a pre-stated rule says otherwise.
- Log delivery by the same units used for assignment: user, household, store, market, account, or region.
- Check that control units were not reached by audience extension, reseller media, retargeting, sales outreach, or overlapping promotions.
- Record budget underdelivery, pacing changes, creative substitutions, tracking outages, product availability issues, and price changes as they happen.
- Do not replace weak-looking controls after the campaign starts unless the readout is explicitly downgraded.
Readout language by evidence strength
| Design condition | Stronger language | Language to avoid |
|---|---|---|
| Clean randomized holdout, limited leakage, clear outcome window. | The test estimates incremental effect for this eligible population and campaign setup. | The channel always drives this lift. |
| Matched markets with strong pre-period trend similarity and logged controls. | The tested markets outperformed a pre-selected comparison estimate under these conditions. | The campaign proved national incrementality. |
| Control contamination or major operating changes. | The result is directional because the comparison no longer cleanly represents business as usual. | The positive result confirms the tactic. |
| No holdout, only before-and-after reporting. | The report shows observed movement after launch, not a causal estimate of lift. | The campaign caused the full change from the prior period. |
Useful questions for a vendor call
- Who was eligible for treatment and control before the campaign began?
- What exact rule assigned or matched the comparison group?
- How much treatment exposure reached the control group?
- Which events, markets, users, or outcomes were excluded, and were those rules set before results were visible?
- What result would have been called inconclusive even if the point estimate was positive?
Takeaway
A comparison group is not a formality. It is the claim. If the holdout or matched market does not represent what would have happened anyway, the readout may still be useful as operational reporting, but it should not be treated as strong causal evidence.