Marketing mix modeling
MMM readout QA checklist
Organization byline: Measurement Press editorial desk. This page does not list an individual author or reviewer. Read the editorial method and corrections policy.
About 11 min read
A marketing mix model readout is a budget argument. It asks a team to believe that historical spend, controls, priors, and model assumptions can guide future allocation.
Use this checklist before accepting a channel rank, moving budget, cutting a channel, or treating a modeled ROAS number as a causal fact. The question is not whether the model is useful. The question is what decision the readout can support without overstating certainty.
In plain language, this is a speed check. A model can help a team choose a direction, set a guardrail, or design the next test. It should not turn a fragile rank order into a confident spending order just because the chart is clean.
Source trail for the QA boundaries
These first-party references anchor the checks below. Google’s Meridian documentation describes MMM as a Bayesian modeling and causal-inference workflow, recommends examining model health and budget optimization after modeling, and documents geo-level structure, nonlinear media transformations, priors, and calibration choices. Google Ads’ Conversion Lift guidance supplies the contrasting controlled treatment/control boundary: incremental conversions are the difference between treatment and control, not the same thing as attributed conversions.
- Google Meridian MMM overview for the pre-modeling, applied-modeling, post-modeling, and causal-inference workflow.
- Meridian model specification for geo-level data, nonlinear media transformations, priors, and the assumptions that shape the readout.
- Google Ads Conversion Lift measurement data for the treatment/control definition of incremental conversions and the distinction from standard attribution.
- Google Ads Conversion Lift setup guidance for study power, holdout percentage, duration, and why directional results should not be treated as conclusive proof.
Source-to-decision handoff
Use the primary references to change the readout packet, not to decorate it. The consequence column is the claim ceiling when the required field is missing.
| Verified source finding | Readout field to show | Decision consequence |
|---|---|---|
| Meridian model-fit guidance separates predictive fit from causal validation and calls for experiments with the same estimand. | Show the estimand, counterfactual, outcome, population, time window, and uncertainty beside fit metrics. | Fit evidence alone supports historical tracking language, not a causal budget mandate. |
| Meridian diagnostics guidance treats R-squared, MAPE, and wMAPE as predictive-accuracy checks rather than a complete causal assessment. | Separate train/test fit and model-health diagnostics from calibration, confounding, and sensitivity evidence. | Do not use a clean fit chart as proof of channel incrementality or optimal allocation. |
| Meridian configuration guidance warns that a period-specific ROI calibration may not improve overall ROI estimation. | Show the calibration period, the modeled decision period, and with/without-calibration sensitivity. | Stage or narrow the budget action if the recommendation depends on one calibration window. |
| Google Ads Conversion Lift measurement data distinguishes treatment/control incremental conversions from standard attributed conversions. | Label any controlled-study result by estimand, assignment, outcome, attribution rule, and study window. | Do not translate an attribution result or mismatched lift result into a causal MMM claim. |
Start with the decision
A model readout should begin with the business move it is meant to inform. Different decisions need different evidence quality.
| Decision | Evidence the readout should show | Weak substitute |
|---|---|---|
| Shift budget between channels | Incremental contribution, uncertainty, response curves, and sensitivity to assumptions. | A rank-ordered ROAS table with no interval or robustness check. |
| Increase total spend | Marginal return at the proposed spend level, saturation risk, and business constraints. | Average historical ROAS applied to a larger future budget. |
| Cut a channel | Low contribution across model variants, calibration checks, and clear opportunity cost. | A low point estimate from one model specification. |
| Defend brand or upper-funnel spend | Lag structure, proxy outcomes, calibration evidence, and uncertainty around long-run effects. | Short-window sales response treated as the whole value of the channel. |
| Plan a test | Specific channel, geography, audience, outcome, and effect size the model cannot resolve. | A generic request to validate the model after budget decisions are already made. |
Minimum readout packet
Ask for the packet before debating recommendations. A useful MMM readout makes the model's assumptions visible enough to inspect.
Decision statementThe exact action under consideration: hold spend, move budget, add budget, reduce budget, change flighting, or run a follow-up experiment.
Data dictionaryOutcome source, media inputs, spend granularity, impressions, reach proxies, pricing, promotions, distribution, seasonality, macro controls, and missing-data handling.
Model specificationTime window, geography, channel grouping, adstock assumptions, saturation functions, priors, constraints, transformations, and excluded variables.
Calibration evidenceLift tests, geo tests, holdouts, or other evidence used to anchor channel effects, including whether the estimand matches the modeled effect.
Uncertainty and sensitivityIntervals, model variants, prior sensitivity, control sensitivity, time-window sensitivity, and whether recommended budget moves survive those checks.
Decision limitThe strongest action the readout can support: directional planning, test prioritization, budget guardrails, or a material allocation move.
Budget-change checklist
| Question | Good evidence | Do not accept |
|---|---|---|
| What is the modeled outcome? | A clear outcome definition and time grain that match the decision. | A sales, lead, visit, or revenue label with no source or counting rule. |
| What would have happened anyway? | Controls and baseline demand structure that cover known confounders. | Seasonality and promotions treated as background noise. |
| Are media inputs comparable? | Consistent spend, delivery, and timing definitions across channels. | One channel measured by spend, another by impressions, and another by attributed conversions without reconciliation. |
| Are priors doing the work? | Transparent priors, constraints, and sensitivity runs. | Channel rankings that change materially when assumptions are relaxed but are still presented as firm. |
| Is the response curve plausible? | Marginal returns shown near current and proposed spend levels. | Average historical ROAS used as if returns stay constant. |
| Was the model calibrated? | Calibration against credible experiments or clearly labeled external evidence. | A model-fit chart presented as causal validation. |
| How fragile is the recommendation? | Scenario ranges that show when the recommendation holds or breaks. | One budget optimizer output treated as the final plan. |
| What should be tested next? | A follow-up test tied to the largest uncertainty or highest budget risk. | A vague instruction to keep measuring. |
Causal language ladder
MMM readouts often fail by using language that sounds more certain than the model design deserves. Match the wording to the evidence.
| Evidence available | Stronger wording | Weaker wording |
|---|---|---|
| Predictive fit only. | The model tracks historical outcome patterns under this specification. | The model proves each channel's causal contribution. |
| Controls and plausible priors. | The model supports a directional contribution estimate, subject to assumptions. | The channel generated exactly the reported return. |
| Calibration with relevant tests. | Experimental evidence and modeled estimates point in the same direction for this effect. | One calibration result validates all future budget moves. |
| Sensitivity-tested recommendation. | The proposed budget move remains reasonable across tested assumptions. | The optimizer found the optimal budget. |
| Fragile or mixed model variants. | The readout identifies uncertainty and a testable decision risk. | The model says to cut or scale the channel with confidence. |
Response curve audit
The most important MMM chart is often not the channel ranking. It is the shape of the response curve near the budget being considered.
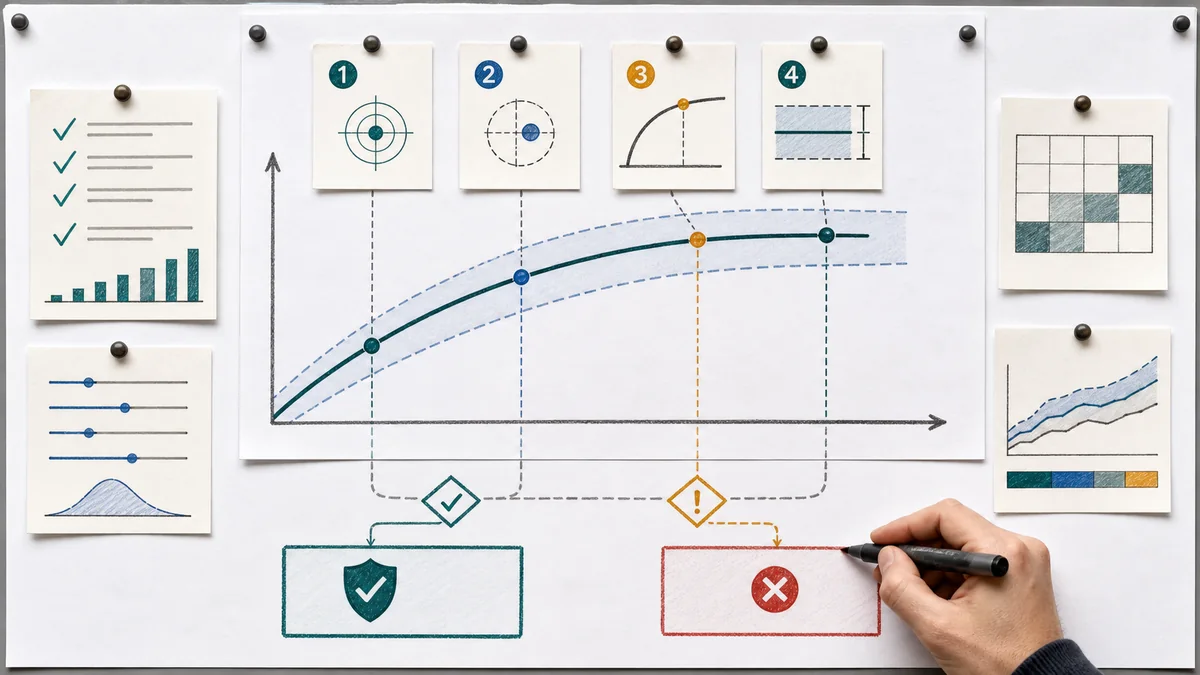
Adstock
Ask how quickly each channel's effect appears and decays, and whether the lag matches the purchase cycle.
Saturation
Check whether recommended spend sits in a plausible range or relies on extrapolating beyond observed history.
Constraints
Separate real business limits from modeling constraints that were added to force plausible-looking answers.
Interactions
Ask whether channels are modeled independently even when campaign strategy depends on sequencing or reinforcement.
Time window
Inspect whether the model window includes unusual shocks, launch periods, promotions, or distribution changes.
Marginal return
Use marginal return for budget moves. Average return can make mature channels look more scalable than they are.
Worked downgrade example
A planning team receives a readout that recommends a large shift from one channel into another. The rank table is clean, the model fit looks strong, and the optimizer has a crisp answer. The QA pass changes the claim because the decision risk sits in the evidence, not in the chart design.
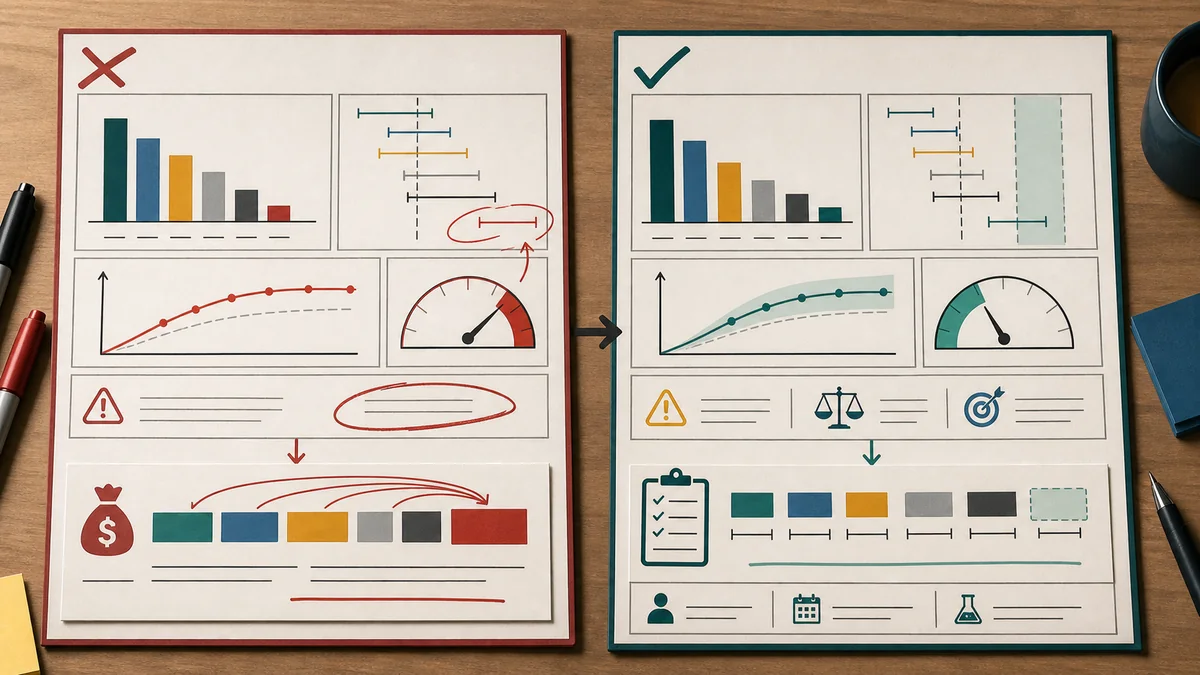
| What the readout showed | What the QA pass found | Better recommendation |
|---|---|---|
| One channel ranked first by modeled marginal return. | The interval overlapped with peer channels under reasonable specifications. | Use the result as a shortlist signal, not a winner claim. |
| The optimizer recommended a large immediate shift. | The proposed spend sat near the flat part of the response curve and above the observed spend range. | Approve a smaller phased move with a review threshold. |
| Calibration evidence supported brand demand. | The budget decision needed qualified pipeline evidence, not only upper-funnel movement. | Pair the MMM with a pipeline-focused test before using causal sales language. |
| The deck said the model proved the better channel. | The evidence supported direction, but not exact channel credit or a full reallocation. | Write: "The model supports a testable budget hypothesis within a guarded spend range." |
Simulated Worked Example: turn a rank into a guarded decision
Simulated Worked Example - not a real model output or benchmark. Assume a planning team receives the following fictional scenario outputs for a proposed additional $20,000 in each channel. The point estimates look different, but the intervals overlap; the calculation makes the decision boundary visible without pretending that the numbers came from a live campaign.
| Channel | Modeled incremental outcomes at proposed spend | Illustrative 80% interval | Marginal return calculation | QA reading |
|---|---|---|---|---|
| Search | 150 | 70-230 | 150 / $20,000 = 7.50 per $1,000 | Highest point estimate, but uncertainty is wide. |
| Video | 135 | 85-205 | 135 / $20,000 = 6.75 per $1,000 | Point estimate trails Search; interval overlaps it. |
| Display | 95 | 60-135 | 95 / $20,000 = 4.75 per $1,000 | Lower point estimate, with a different uncertainty range. |
Bounded decisionThe simulation supports a shortlist and a phased test of the proposed range; it does not support saying that Search is the proven winner or that 150 outcomes will occur. Before moving the full budget, ask whether the interval, calibration evidence, observed spend range, and response curve support the same direction. If they do not, record the result as a budget hypothesis and define the test or review threshold.
Assumptions and limits: the three rows use the same outcome definition, the same $20,000 scenario increment, and intervals that are comparable on the same model scale. The numbers are deliberately fictional and do not estimate a real advertiser’s return. A real readout would also show the modeled time window, geo or national unit, priors, controls, calibration source, response-curve location, and the decision rule agreed before the scenario was run. A controlled treatment/control study is a different estimand; do not relabel these simulated MMM outputs as incremental lift.
Simulated readout acceptance gate
Apply this gate to the same fictional packet before turning a rank into a budget instruction. A Pass means the field is visible and comparable in the example; a Hold means the missing field is decision-critical and must not be filled with an assumption.
| Gate | Packet evidence | Result | Why it changes the claim |
|---|---|---|---|
| Common outcome definition | All three rows use modeled incremental outcomes. | Pass | The channel rows are on the same stated outcome scale. |
| Common scenario increment | Each row evaluates an additional $20,000. | Pass | The marginal-return arithmetic is reproducible: outcomes ÷ $20,000 × 1,000. |
| Comparable uncertainty | Each row includes an illustrative 80% interval on the same model scale. | Pass | Overlapping ranges prevent a point-estimate winner claim. |
| Calibration matches the decision | No experiment, holdout, or calibration estimand is supplied. | Hold | A modeled rank cannot be relabeled as causal lift. |
| Response curve is observed near the move | Current spend, proposed spend, saturation, and observed range are not supplied. | Hold | A $20,000 move may be extrapolating beyond the evidence. |
| Pre-set action threshold | No agreed rule says when to move, phase, stop, or retest. | Hold | The packet supports a hypothesis and follow-up test, not automatic allocation. |
Reproduction: count the three Pass rows and three Hold rows to get 3/6 = 50% packet readiness. Recalculate each marginal return from the displayed outcome and common $20,000 increment, then mark a gate Pass only when the named field is present. The bounded action is to shortlist Search or Video for a phased test; the full-budget decision remains on hold until calibration, response-curve, and action-threshold evidence are attached.
What would change the result: a relevant calibration result, an observed-spend response curve covering the proposed range, and a pre-specified decision threshold could move the packet toward a guarded allocation. They would not make the fictional numbers real or remove the need to report uncertainty.
Meeting script
- What exact budget decision is this readout meant to support?
- Which modeled outcome is closest to the business outcome we care about?
- Which controls changed the answer most, and why are they included?
- What prior, constraint, or response-curve assumption would most alter the recommendation?
- Which channels have overlapping uncertainty rather than clearly different returns?
- Which recommendation survives reasonable sensitivity checks?
- What experiment or holdout would reduce the highest-value uncertainty before the next planning cycle?
Pair with
Use this checklist after the MMM causal validity checklist and before a budget recommendation is finalized. Pair it with the MMM calibration evidence checklist when experiments, holdouts, or benchmarks are used as model anchors, the measurement method selector when MMM is being asked to answer a question better suited to a lift test, the incrementality test plan template when a model uncertainty needs experimental evidence, the comparison market and holdout planning guide for test design, and the campaign readout QA checklist when a model result is being blended with campaign reporting.