Marketing mix modeling
MMM calibration evidence checklist
Organization byline: Measurement Press editorial desk. This page does not list an individual author or reviewer. Read the editorial method and corrections policy.
About 13 min read
Calibration is the bridge between a marketing mix model and real-world experiments. It can make a model more useful, but only when the evidence being used as an anchor actually matches the effect the model is asked to estimate.
Use this checklist before a lift test, geo experiment, holdout, brand study, or external benchmark is used to tune a model, validate a channel contribution, or defend a budget recommendation. A calibration point is not a trophy. It is evidence with a unit, population, outcome, window, uncertainty, and decision boundary.
The most common failure is not that a team ignores experiments. It is that the experiment answers a narrower question than the model readout. A clean retargeting lift test, for example, can be useful evidence without being a clean anchor for the full paid social contribution curve.
Start with the calibration job
Teams often say an MMM is calibrated without saying what the calibration is supposed to do. Name the job before accepting the evidence.
| Calibration job | Evidence needed | Weak substitute |
|---|---|---|
| Anchor one channel's incremental effect. | A credible test for the same channel, audience, market, outcome, and time window the model estimates. | A platform lift number from a different audience, season, or outcome treated as a universal truth. |
| Constrain a response curve. | Tests or historical spend variation near the current and proposed spend range. | A single average return applied to every future budget level. |
| Set priors for a sparse channel. | Transparent prior source, relevance test, uncertainty range, and sensitivity run. | A benchmark inserted without showing how much it drives the answer. |
| Validate channel ranking. | Multiple calibration points or sensitivity checks showing whether rank survives uncertainty. | One favorable experiment used to justify a full channel order. |
| Plan the next test. | A model uncertainty that maps to a practical audience, market, outcome, and detectable effect. | A generic plan to run a test after the budget decision has already been made. |
Calibration packet
Ask for this packet before debating whether the model has been validated. The point is to make the calibration evidence auditable.
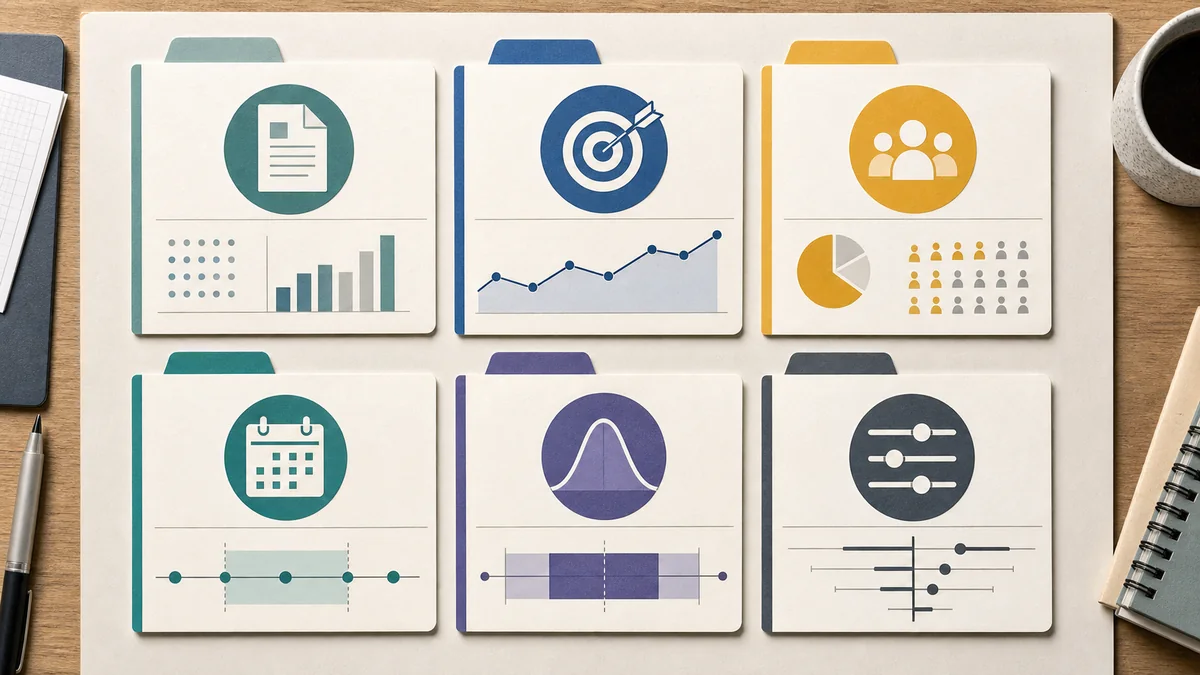
Evidence sourceTest owner, method, field dates, channel, media tactic, geography, audience, creative mix, delivery quality, and whether the readout was completed before model fitting.
Estimand matchThe effect the evidence estimates and the effect the MMM estimates. Check whether both use incremental revenue, conversions, qualified leads, store visits, awareness, or another outcome.
Unit and populationUser, household, account, market, store, region, or time-series unit, plus the eligible population. A user-level test may not cleanly calibrate a market-level model without careful translation.
Window alignmentExposure window, outcome window, conversion lag, carryover, seasonality, and whether the MMM's adstock assumptions line up with the experiment's readout period.
UncertaintyInterval, minimum detectable effect, sample base, leakage risk, and whether the model uses the calibration point as a tight anchor or a broad prior.
Influence checkModel results with and without the calibration evidence, plus sensitivity to reasonable alternative priors or calibration weights.
Method sources
These official references anchor the checks in this page. Google Meridian describes an open-source Bayesian MMM library with modeling, calibration, and post-modeling guidance. Its model configuration guide explains that an ROI-calibration period can be used when an experiment window does not match the model window, while warning that a period-specific calibration may not improve overall ROI estimation. For experimental inputs, Google Ads' Conversion Lift setup guidance connects study power to estimated lift, conversion actions, duration, budget, and holdout share; its measurement-data guide distinguishes incremental conversions from standard attributed conversions. Read these sources alongside the page's match and sensitivity checks rather than treating any platform workflow as proof that an MMM is correct.
Source-to-decision handoff
Each reference should change a review field or lower the claim ceiling. A citation is useful here only when the analyst can show how it affected the calibration choice.
| Verified source finding | Packet field to update | Decision consequence |
|---|---|---|
| Meridian model-fit guidance says causal validation needs a correctly executed experiment with the same estimand as the MMM. | Record the modeled estimand, experiment estimand, outcome, population, counterfactual, and time window side by side. | A related lift result can inform a directional prior, but it cannot validate a different channel-wide effect. |
| Meridian configuration guidance cautions that a period-specific ROI calibration may not improve overall ROI estimation. | Show the calibration window and compare the model with the window, with a wider prior, and without the calibration point. | Hold a large budget move when the recommendation changes materially across those views. |
| Google Ads Conversion Lift measurement data defines incremental conversions as treatment conversions minus control conversions and distinguishes them from attributed conversions. | Label the metric, assignment, holdout, attribution rule, and outcome source explicitly. | Do not relabel an attributed or mismatched platform metric as causal calibration evidence. |
| Google Ads setup guidance ties study duration to conversion lag and holdout feasibility. | Record study duration, average conversion lag, holdout share, power or detectable-effect check, and late-outcome handling. | Downgrade the calibration when the study window cannot capture the modeled outcome timing. |
Influence and sensitivity check
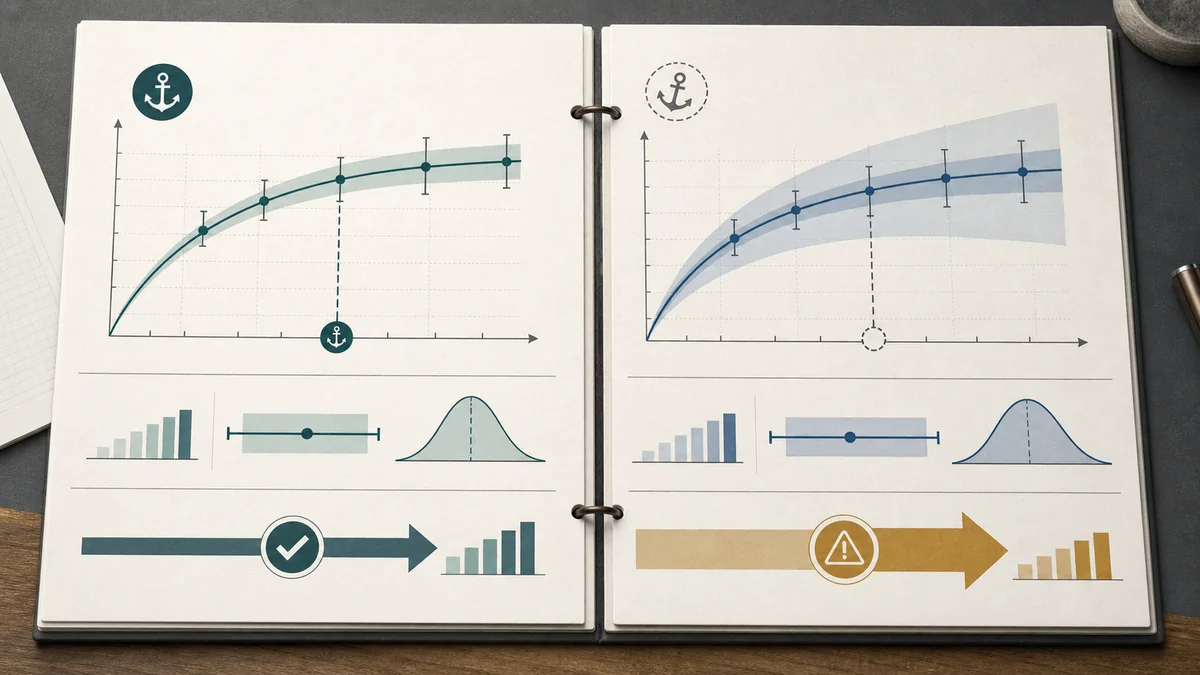
A calibration point can look authoritative because it is close to an experiment. That does not mean it should be allowed to steer the whole model. Ask the analyst to show a with-calibration readout, a loosened-prior readout, and a no-calibration readout for any channel recommendation that changes the budget.
If the same budget move survives those views, the calibration evidence is probably improving confidence. If the decision flips, the readout should say the recommendation depends on a calibration assumption and identify the next test needed before the team acts.
| What changes in sensitivity | Interpretation | Decision rule |
|---|---|---|
| Channel rank and budget move stay stable. | The calibration point improves confidence without carrying the whole recommendation. | Use the evidence as an anchor, but still report the uncertainty range. |
| Rank stays stable, but return interval widens. | The direction is useful, but the amount of spend change is less certain. | Use a smaller budget move or a staged test instead of a full reallocation. |
| Rank flips when the prior is loosened. | The decision depends on the calibration assumption. | Downgrade the claim to directional and name the experiment needed next. |
| Only a narrow tactic supports the channel-wide result. | The evidence estimates a smaller population than the model contribution. | Anchor the tactic if appropriate, but do not generalize to the full channel. |
| External benchmark overwhelms internal history. | The prior is filling a data gap rather than validating the model. | Treat it as a broad plausibility range until internal evidence exists. |
Simulated worked calibration check
This is a Simulated Worked Example, not a Measurement Press model or campaign result. It shows how to decide whether one experiment is a usable anchor, a directional prior, or a reason to collect better evidence. Assume a channel-level MMM reports $2.40 of modeled incremental revenue per $1 of spend for a 12-week period. A randomized holdout study covers only a retargeting audience during four weeks: 1,000 treatment users produce 80 conversions and 1,000 control users produce 60.
| Check | Simulated record | What it means |
|---|---|---|
| Observed test rates | 80 / 1,000 = 8.0%; 60 / 1,000 = 6.0% | The test shows a 2.0 percentage-point difference, or 20 incremental conversions per 1,000 treatment users under the stated comparison. |
| Audience match | Retargeting users in the test; prospecting plus retargeting in the MMM | The test may inform the retargeting tactic, but it does not automatically identify the full channel response curve. |
| Window match | Four-week test; 12-week model readout | Seasonality, carryover, and conversion lag need a sensitivity check before the test is used as a 12-week ROI anchor. |
| Outcome match | Conversions in the test; incremental revenue in the MMM | A conversion lift cannot be translated into revenue without order-value, margin, and downstream-quality evidence. |
| Influence check | Modeled ROI: $2.40 with the test; $2.10 with a broad prior; $1.70 without the test | The ranking may be stable, but the spend amount depends materially on the calibration assumption. |
Simulated decision: directional prior, not channel-wide validationThe arithmetic is reproducible: 8.0% − 6.0% = 2.0 percentage points, and 1,000 × 0.02 = 20 illustrative incremental conversions. The test earns a directional-prior posture because assignment and control protection are assumed, but the audience, window, and outcome do not match the full MMM estimand. Keep the channel ranking provisional, narrow the budget claim, and plan a broader test or calibrated revenue bridge before calling the model validated.
Assumptions: treatment and control are mutually exclusive, assignment was set before outcomes were observed, the conversion definition is fixed, and the displayed rates are complete for the study window. Limitations: every number is invented for this example; no uncertainty interval, power calculation, revenue distribution, margin, carryover estimate, or leakage audit is shown. A point estimate or platform lift result is not evidence that the full channel response curve is causal.
Calibration handoff and decision sensitivity
Use this handoff to keep a calibration point from silently changing the question. The example below reuses the simulated test above; it is not evidence from a real campaign. A reviewer should be able to trace each field to the model decision, then reproduce the sensitivity without a private analyst notebook.
| Handoff field | Simulated record | Decision consequence |
|---|---|---|
| Estimand | Test: incremental conversions; MMM: incremental revenue per $1. | Do not convert the 2.0-point lift into ROI without order-value, margin, and downstream-quality evidence. |
| Population and tactic | 1,000 retargeting treatment users versus 1,000 controls; MMM includes prospecting and retargeting. | Use the result as a retargeting prior only. A channel-wide claim requires evidence that the effect transports to the other tactics. |
| Time window | Four-week experiment; 12-week model readout. | Run a lag, seasonality, and carryover sensitivity before using the point as a 12-week anchor. |
| Model influence | $2.40 ROI with the test; $2.10 with a broad prior; $1.70 without the test. | The budget answer is materially assumption-sensitive, so the point should not be described as full model validation. |
| Claim ceiling | Directional evidence for a retargeting conversion effect. | Hold a channel-wide revenue or profit claim until a matched revenue bridge or broader experiment is available. |
| Scenario | Reproducible calculation | Illustrative $2.00 ROI gate |
|---|---|---|
| With calibration point | $2.40 - $2.00 = +$0.40 per $1. | Passes the numeric gate, but only with a narrow, tactic-level interpretation. |
| Broad prior | $2.10 - $2.00 = +$0.10 per $1. | Passes narrowly; a small staged move is more defensible than a full reallocation. |
| No calibration point | $1.70 - $2.00 = -$0.30 per $1. | Fails the gate; the decision changes when the evidence is removed. |
| Influence spread | $2.40 - $1.70 = $0.70 per $1; $0.70 / $1.70 = 41.2% relative to the no-calibration readout. | Re-run the decision with the prior loosened and document the next test before treating the result as a budget instruction. |
Reproduction and hold ruleCopy the five simulated records into a worksheet, calculate each rate as conversions / eligible users, calculate lift as treatment rate - control rate, and calculate each gate margin as modeled ROI - $2.00. If the recommendation changes sign across the three model scenarios, label the result assumption-sensitive and keep the budget move staged. The $2.00 gate is an illustration, not a universal threshold.
Source boundary: Google Meridian documentation supports checking custom priors, model configuration, holdout structure, and the limits of a period-specific ROI calibration; Google Ads documentation supports distinguishing incremental conversions from attributed conversions and planning experiment inputs. Those sources do not validate these invented records, establish a universal ROI gate, or prove that a retargeting result generalizes to a channel-wide MMM.
Evidence match matrix
| Evidence type | Strong fit for MMM calibration | Downgrade when |
|---|---|---|
| Randomized conversion lift test | Assignment was protected, outcome source matches the MMM outcome, and the tested population is close to the modeled population. | Control leakage, post-assignment filtering, narrow retargeting eligibility, or a proxy outcome makes the test estimate a different effect. |
| Geo or store lift test | Treatment and control markets had similar pre-period trends, logged operating changes, and an outcome that maps to the model grain. | Markets were chosen after results were visible, local shocks were unlogged, or the test window is too short for the modeled carryover. |
| Matched-market comparison | Matching rule was locked before launch and sensitivity checks show the estimate is not driven by one convenient control. | The comparison is mainly size-matched while trend, seasonality, distribution, or competitor pressure differ. |
| Brand lift study | The model includes a brand or demand proxy and the survey design has balanced exposed and control respondents. | Survey lift is used to calibrate sales, revenue, or profit without evidence connecting the perception outcome to business impact. |
| External benchmark | The benchmark is used as a wide prior, with source, category, channel, outcome, and uncertainty visible. | It replaces internal evidence or forces a channel contribution because the model is otherwise unstable. |
Red flags
- The calibration section says "validated by lift tests" but does not name the tests, dates, audiences, outcomes, intervals, or model influence.
- A narrow platform test calibrates a broad channel that includes prospecting, retargeting, brand search, partner media, or different creative.
- A short-window experiment is used to confirm a long-run response curve without showing lag or carryover sensitivity.
- A brand metric is used to anchor sales contribution without explaining the bridge from perception to business outcome.
- The model recommendation changes materially when calibration priors are loosened, but the readout still presents one firm budget answer.
How to write the calibration note
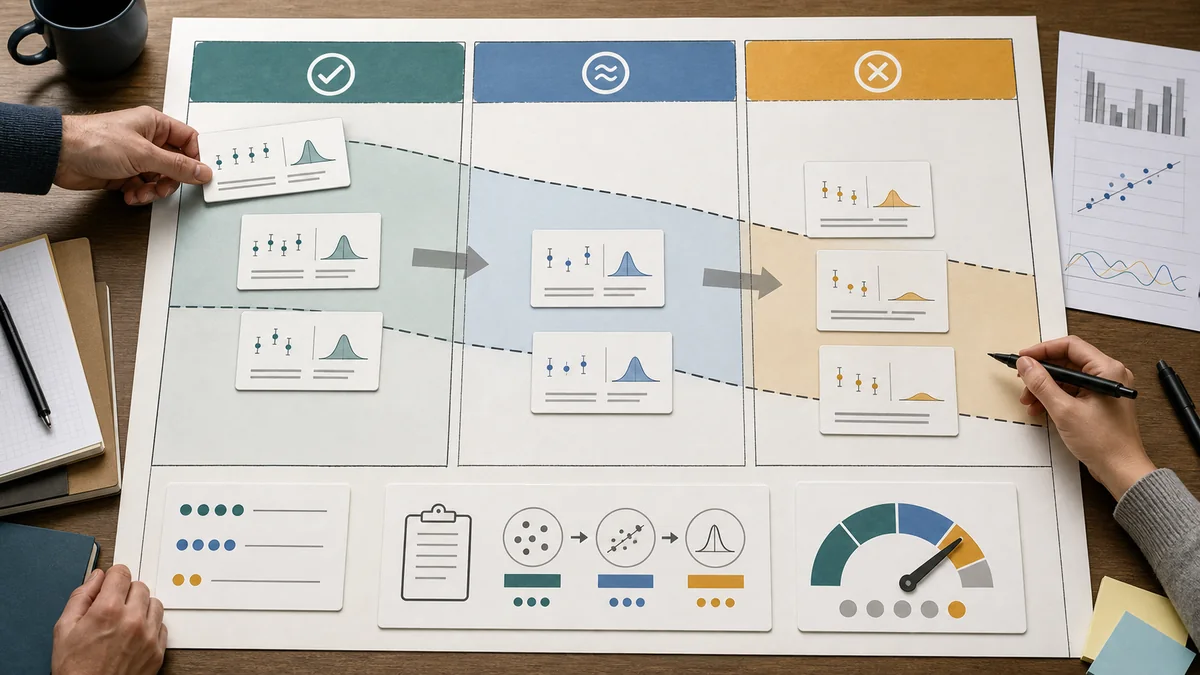
A useful readout makes the calibration note short, specific, and bounded. It should say what evidence was used, how it entered the model, how much it changed the answer, and where it should not be generalized.
| Evidence condition | Careful wording | Wording to avoid |
|---|---|---|
| Relevant test with clean assignment and aligned outcome. | The model is calibrated to experimental evidence for this channel, population, and outcome range. | The model is proven correct. |
| Relevant but noisy test. | The test informs the prior, but uncertainty remains wide enough to limit budget-change confidence. | The test validates the channel return. |
| Different audience or outcome. | The evidence is directional because it estimates a related but different effect. | The same lift applies to the modeled channel. |
| External benchmark only. | The benchmark supplies a broad plausibility range until internal experiments are available. | The benchmark confirms expected performance. |
| Conflicting calibration points. | The model should show sensitivity and identify the next testable uncertainty. | The average of conflicting tests settles the question. |
Meeting questions
- Which calibration points were used, and which were rejected?
- Do the calibration points estimate the same outcome, population, and time window as the model?
- How does the model result change when each calibration point is removed?
- Are calibration points treated as tight constraints or broad priors?
- Which channel recommendation depends most on calibration assumptions?
- What experiment would most reduce uncertainty before the next budget decision?
Pair with
Use this checklist with the MMM causal validity checklist before accepting model contribution claims and the MMM readout QA checklist before budget allocation. When calibration evidence comes from experiments, pair it with the randomized lift test readout checklist, geo lift test design checklist, and comparison market and holdout planning guide. Use the source library for official references on MMM, outcomes, attention, and measurement quality.