Exposure quality
Viewability and invalid traffic measurement checklist
Organization byline: Measurement Press editorial desk. This page does not list an individual author or reviewer. Read the editorial method and corrections policy.
About 11 min read
Campaign readouts often jump from served impressions to attributed outcomes. The missing middle is exposure quality: whether the ad had a measurable chance to be seen by a valid audience in the intended context.
Use this checklist before accepting a programmatic, direct-sold, sponsorship, video, or private marketplace report. It helps marketers, publishers, agencies, and analysts separate delivery hygiene from attention, brand movement, and incrementality.
Picture the first renewal meeting after a contextual campaign. The report shows strong delivery and a lift chart, but the buyer asks a simpler question first: how much of the delivery was measurable, viewable, valid, and not concentrated in a small frequency tail? If the team cannot answer that, the outcome claim is being asked to carry more weight than the exposure record can support.
Put the metric in the right lane
Viewability and invalid-traffic controls are quality gates. They can make a campaign report more trustworthy, but they do not prove that exposure changed behavior.
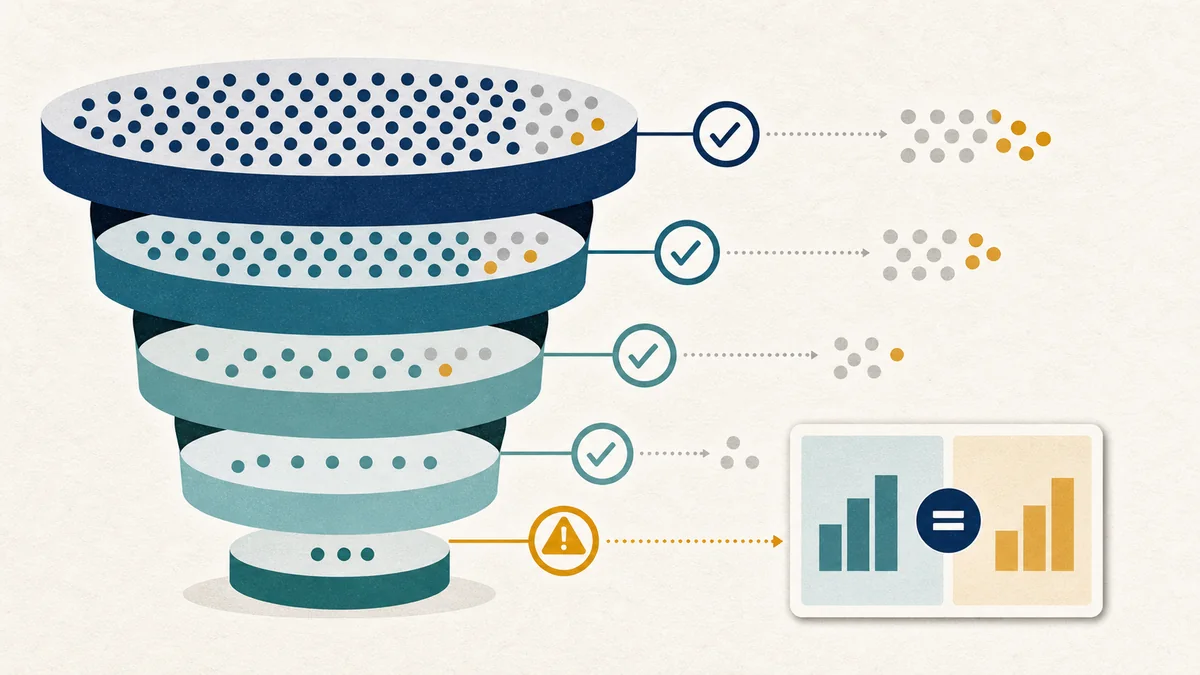
| Metric or check | What it can show | What it cannot prove alone |
|---|---|---|
| Served impressions | The ad system delivered responses that counted toward pacing and billing logic. | That the ad was measurable, viewable, noticed, or valid. |
| Measurable impressions | The measurement system could determine viewability or exposure status for a defined subset. | That the measured subset represents all delivered impressions. |
| Viewable impressions | The impression met the selected viewability definition for the format and device context. | That the person paid attention, remembered the message, or changed behavior. |
| Invalid-traffic filtering | The report applied defined checks for non-human, ineligible, or otherwise invalid activity. | That every invalid impression was removed or that remaining traffic is high quality. |
| Frequency distribution | How exposure is concentrated across users, browsers, devices, households, or modeled people. | That repeated exposure created incremental outcomes. |
| Attention signal | Whether the format and environment produced stronger exposure-quality indicators. | That attention is a causal business outcome without a comparison design. |
Pre-flight controls
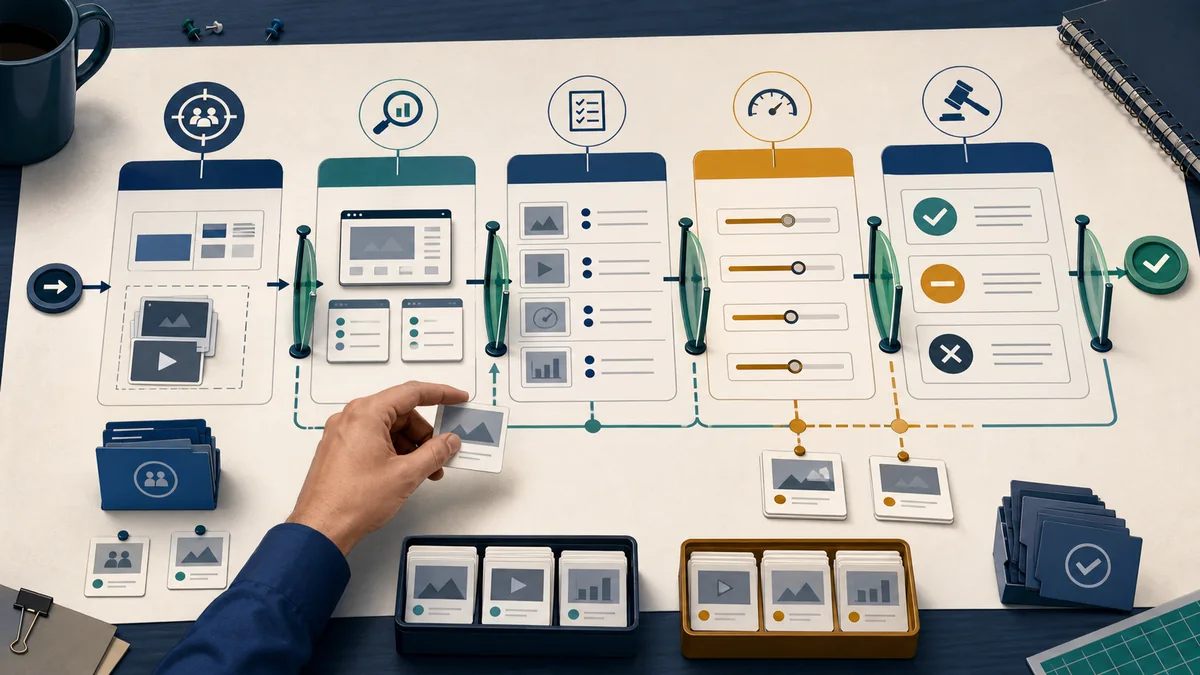
1. Define the eligible inventoryList the sites, page groups, content desks, placement IDs, formats, device classes, geographies, and exclusions that count as qualified delivery. A viewability rate is less useful when the inventory pool is vague.
2. Name the measurement sourceDocument whether viewability, invalid traffic, frequency, and reach come from the ad server, publisher, agency platform, verification provider, panel, clean room, or advertiser analytics. Different systems can count different universes.
3. Set the minimum reportable fieldsRequire served, measurable, viewable, filtered, unmeasured, and suppressed counts by placement, creative, device class, date, and buying path. Percentages without counts can hide small or unstable cells.
4. Preserve quality thresholds before launchWrite the acceptable measurable rate, viewable rate, invalid-traffic review threshold, frequency cap, and excluded inventory rule before results are visible.
5. Decide what happens when a gate failsAgree whether low measurability, high invalid-traffic flags, hidden placement context, or frequency concentration triggers a makegood, optimization, exclusion, or descriptive-only readout.
Report QA table
| Check | What the report should show | Why it matters |
|---|---|---|
| Measurability | Measured and unmeasured impressions by placement, device, format, and date. | A high viewable rate on a small measured subset can overstate exposure quality. |
| Viewability definition | The standard, format, duration, pixel threshold, device coverage, and any vendor-specific method notes. | Served, measurable, viewable, completed, audible, and attentive exposure are different claims. |
| Invalid traffic | Filtered counts, post-filter delivery, suspicious groupings, excluded placements, and whether filtration happened before or after billing. | Invalid-traffic handling changes the denominator for every downstream metric. |
| Placement context | Page group, slot ID, ad unit path, refresh rule, position, size, and creative version. | Exposure quality can differ because of context and format, not because the message was stronger. |
| Frequency tail | Reach, average frequency, high-frequency share, and outcome concentration by frequency band. | A small overexposed group can make outcomes look more scalable than they are. |
| Outcome denominator | Whether clicks, visits, leads, conversions, or survey completes are tied to served, measurable, viewable, or valid impressions. | The result changes when the denominator changes. |
Readout ladder
Move from delivery hygiene to impact only when each lower step is visible. A report can be useful even if it stops at exposure quality, as long as the claim language stops there too.
| Step | Question | Evidence needed | Careful conclusion |
|---|---|---|---|
| Delivery | Did the campaign run in the planned inventory? | Qualified impressions by slot, page group, device, date, geography, and creative. | The campaign delivered the intended context. |
| Measurability | Could exposure quality be measured? | Measured and unmeasured counts, method notes, and coverage gaps. | The exposure readout is strong or limited for these placements. |
| Viewability and validity | Was delivery likely to create a valid opportunity for exposure? | Viewable, valid, filtered, and excluded counts with denominator clarity. | The campaign met or missed exposure-quality gates. |
| Engagement | Did valid exposure produce observed behavior? | Clicks, sessions, leads, or survey starts tied to the same denominator and context. | The campaign produced observed engagement under these conditions. |
| Incrementality | Did exposure change outcomes? | Holdout, geo test, switchback, balanced control, or calibrated model with uncertainty. | The campaign produced measured lift for this design and window. |
Common failure modes
- Calling a served impression a viewed impression when measurability and viewability are not shown.
- Reporting only viewability percentages without the measured and unmeasured impression counts.
- Pooling desktop display, mobile web, video, CTV, and native placements into one exposure-quality number.
- Removing invalid traffic from one metric while leaving it in another metric's denominator.
- Using high viewability to justify sales lift when no comparison group exists.
- Ignoring frequency concentration when a small group drives most clicks, leads, or survey completes.
Worked decision map
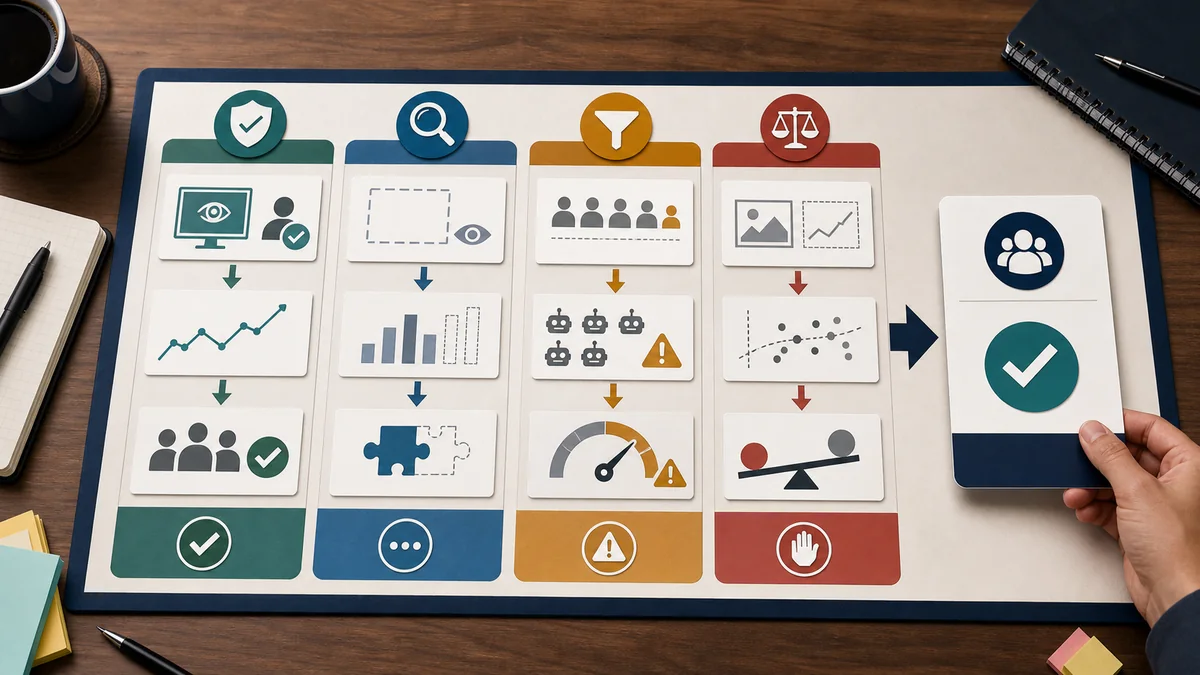
The same viewability and invalid-traffic evidence can lead to different decisions. Use the map below before writing renewal language or moving budget: it separates clean exposure-quality claims from measurement gaps, traffic review issues, and causal claims that need a comparison.
| What the evidence shows | Question to ask before wording | Status band | Careful readout language |
|---|---|---|---|
| Eligible inventory, measurable counts, viewable counts, post-filter valid delivery, placement context, and frequency bands are all visible. | Does the claim stay limited to exposure quality unless a comparison design is present? | Clean exposure-quality readout | The campaign delivered valid, measurable, viewable exposure in the planned placements under the stated definitions. |
| Viewability looks strong, but a large share of delivery was unmeasured or suppressed in one placement, device class, or date range. | Can the report separate the measured subset from the unmeasured delivery before totals are summarized? | Limited readout | The measured subset met exposure-quality gates, while the unmeasured delivery limits confidence in the total campaign readout. |
| Invalid-traffic filters removed a meaningful share, suspicious placements cluster in one path, or filtration timing changes the denominator. | Were filtered, post-filter, and excluded impressions kept separate for billing, optimization, and outcome reporting? | Traffic review required | Post-filter results should be read separately from pre-filter delivery until the affected placements and buying paths are reviewed. |
| Viewable exposed users converted more often, but the campaign has no holdout, geo test, switchback, balanced control, or calibrated model. | What comparison would tell whether exposure changed behavior rather than selected higher-intent people? | Comparison needed | Observed outcomes were higher among viewable exposed users; incremental impact remains unproven without a comparison design. |
| High-frequency users drive most clicks, leads, survey starts, or conversions. | Does the recommendation depend on broader reach, controlled frequency, or a frequency-specific test? | Frequency-tail review | Results are concentrated among high-frequency exposed users and should not be scaled without reach and frequency controls. |
Readout language
| If the evidence shows | Cleaner wording | Overclaim to avoid |
|---|---|---|
| High viewability and no outcome test. | The campaign delivered strong measured exposure quality in the planned placements. | The campaign drove incremental results. |
| Low measurability in one placement. | The placement's exposure quality is difficult to interpret because too much delivery was unmeasured. | The placement underperformed the audience. |
| Invalid-traffic filtering removed a meaningful share. | Post-filter results should be separated from pre-filter delivery and reviewed by placement source. | The remaining traffic is automatically high value. |
| One creative has higher attention. | The creative produced stronger observed exposure-quality signals and needs an outcome test before budget claims. | The creative is the highest-ROI message. |
| Viewable exposed users converted more often. | Observed conversion rates were higher among viewable exposed users; causal confidence depends on the comparison design. | Viewability caused those conversions. |
Simulated worked example: keep the denominators separate
This fictional audit shows how an exposure-quality review can support a bounded readout without turning viewability or traffic filtering into proof of lift. The counts are invented for method demonstration; replace them with one consistent export and preserve the field definitions before making a campaign decision.
| Audit field | Simulated count | Calculation | What the number supports |
|---|---|---|---|
| Eligible impressions | 120,000 | Report total | The declared denominator for the exposure-quality audit. |
| Measurable impressions | 96,000 | 96,000 / 120,000 = 80.0% | Four-fifths of eligible delivery had a measured viewability opportunity. |
| Viewable impressions | 67,200 | 67,200 / 96,000 = 70.0%; 67,200 / 120,000 = 56.0% | Viewability under the named method, shown against both the measurable and eligible denominators. |
| Invalid-traffic flags | 6,000 | 6,000 / 120,000 = 5.0% | A traffic-review signal; it does not prove that the remaining 95.0% is uniformly valid. |
| High-frequency user band | 2,400 of 12,000 users; 24,000 of 60,000 user-level exposures | 2,400 / 12,000 = 20.0%; 24,000 / 60,000 = 40.0% | A concentration warning: one-fifth of users account for two-fifths of the user-level exposure count in this fictional slice. |
| Observed conversions after viewable exposure | 480 | 480 / 67,200 = 0.714% | An observed rate only; without a comparison group it cannot establish incremental impact. |
Decision: accept the exposure-quality portion as a limited readout (80.0% measurable; 70.0% viewable among measurable impressions), send the 5.0% flagged share and frequency concentration to traffic and reach review, and hold any causal or scale claim. Do not subtract invalid-traffic flags from the viewable count unless the export documents that both fields use the same universe and filter timing.
Reproduce it: export eligible, measurable, viewable, filtered, user-frequency, and outcome counts at the same placement, device, date, and buying-path grain; calculate each rate from its stated denominator; then rerun the decision if filter timing, measurement coverage, or a control comparison changes. The conclusion changes if post-filter viewability is materially different, the flagged traffic clusters in a high-volume placement, or the 480 conversions are compared with a credible unexposed group.
Limitations: this example does not estimate people reached, deduplicate users across devices, establish attention, or separate selection from treatment. The high-frequency slice uses user-level exposure counts rather than ad-server impressions, so it must not be added to the impression rows.
Source notes
Read Google's Ad Manager overview of viewability and its Active View metric definitions before naming eligible, measurable, and viewable counts. The MRC viewable impression guideline provides the industry measurement boundary, while the MRC invalid-traffic detection and filtration addendum is relevant when filtering changes a denominator. For publisher-side traffic responsibility, use Google's invalid-traffic guidance. These sources define methods and responsibilities; none proves that a specific campaign changed outcomes. Use the source library to keep the source role visible in the final readout.
Source-to-decision boundary
The source trail below was checked against the page's decision rules. It clarifies what the references can support and keeps the simulated counts, vendor outputs, and causal conclusions separate from the standards themselves.
| Verified source boundary | Use it for this decision | Do not infer from it |
|---|---|---|
| Google Ad Manager Active View metric definitions place eligible, measurable, and viewable impressions in nested measurement sets. | Keep the denominator ladder visible and calculate measurable and viewable rates from the stated parent set. | A viewable rate proves attention, memory, conversion, or incremental lift. |
| MRC viewable impression guidance defines a display viewability boundary using in-focus pixels and continuous time, with format and environment limitations. | Record the format, device, method, pixel/time rule, and any exception before comparing rates. | The same threshold can be silently applied to mobile, in-app, video, or CTV measurement without a method note. |
| MRC invalid-traffic standards treat invalid traffic as activity that fails quality or completeness criteria and require ongoing, disclosed filtration controls. | Report gross, filtered, post-filter, and unknown or undetermined states with filter timing and material exclusions. | Net traffic is guaranteed human, uniformly valid, or comparable across vendors and buying paths. |
| Google AdSense invalid-traffic guidance includes artificial or repeated clicks/impressions and places responsibility on publishers to protect traffic quality. | Keep acquisition, ad-placement, and review controls focused on genuine user activity and investigate suspicious concentration. | Traffic quality guidance validates this page's simulated 5.0% flag rate or proves a campaign outcome. |
Pair with
Use this checklist with the campaign KPI dictionary for metric definitions, the reach and frequency checklist for deduplication, caps, and high-frequency tails, the private marketplace campaign measurement checklist for planning, the CTV and video checklist for video-specific reporting, the attention measurement decision guide for exposure-quality signals, and the incrementality test plan template when the decision needs a causal estimate.