Campaign reporting
Campaign reporting worksheet for contextual media buys
Organization byline: Measurement Press editorial desk. This page does not list an individual author or reviewer. Read the editorial method and corrections policy.
About 12 min read
A campaign report is easier to judge when the team fills in the claim, evidence, missing fields, and next decision on one page.
Use this worksheet during a campaign readout meeting, renewal review, or buyer-seller handoff. It is built for contextual display, direct sponsorship, and private marketplace campaigns where delivery quality, traffic quality, lead status, and comparison rules need to stay separate.
Imagine a buyer looking at a strong top-line click report for a topic package. The renewal question is not simply whether the chart went up. The team needs to know whether the package delivered in the promised contexts, whether the destination and lead-status fields were mature enough to judge quality, and whether the next recommendation is a renewal, a fix, or a stronger test. The worksheet keeps those questions on the same page before anyone writes the final sentence.
Source trail for the reporting choices
These first-party references support the worksheet structure: Google Ads documents using report dimensions, segments, and destinations to inspect campaign performance; Google Analytics explains that event parameters carry context into dimensions and metrics; and Google Ads experiment guidance recommends a clear hypothesis, limited variables, preselected success metrics, and retained records. I checked these documents for this source trail. Those platform instructions help organize a report and a future test, but they do not turn this simulated worksheet or an observational readout into proof of lift.
- Measure your results - Google Ads Help for campaign-level reporting, segments, devices, time, and landing-page views.
- Understand what is shown in reports - Google Ads Help for report dimensions and performance interpretation.
- [GA4] Event parameters - Analytics Help for preserving event context that feeds dimensions and metrics.
- Test with confidence with the Experiments page - Google Ads Help for pre-specified hypotheses, variables, success metrics, and experiment records.
How to use the worksheet
Fill the worksheet before debating whether the campaign worked. If a field is unavailable, write that down and lower the strength of the conclusion. The point is not to punish missing data; it is to keep the final recommendation inside the evidence actually available.
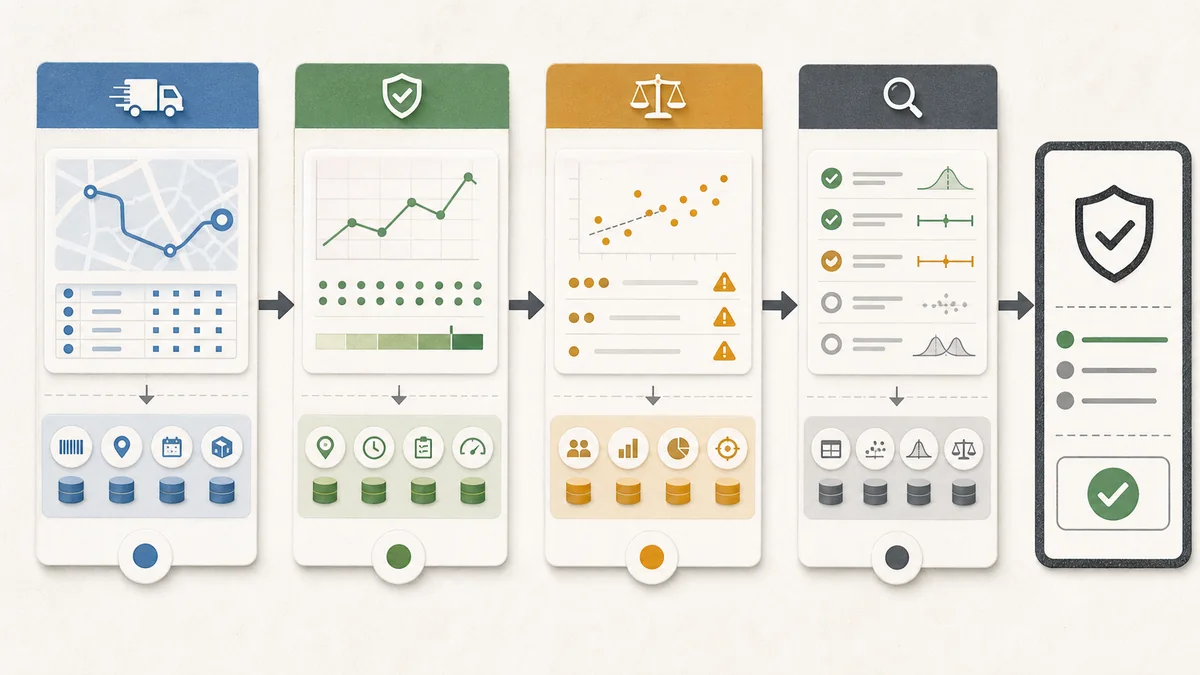
| Step | Meeting action | Output | Common failure |
|---|---|---|---|
| 1. Name the decision | State whether the meeting is about delivery acceptance, renewal, creative changes, budget shift, or test design. | A single decision line. | The readout tries to answer every possible performance question. |
| 2. Lock the evidence level | Mark whether the campaign has descriptive reporting, a prior baseline, a matched comparison, or a designed holdout. | A conclusion boundary. | Observed response is described as lift. |
| 3. Check package delivery | Compare actual placement, context, size, device, date, and geography against the sold package. | A delivery-fit score. | Total impressions hide off-package or uneven delivery. |
| 4. Separate response quality | Review traffic-quality, destination, lead-status, and outcome-status fields separately from clicks or form fills. | A response-quality note. | The strongest volume metric becomes the recommendation. |
| 5. Write the next action | Choose renew, renew with changes, shift mix, retest, add lift test, or pause. | A bounded recommendation. | The action asks for more certainty than the report can support. |
Worksheet fields
These fields are deliberately compact. They should fit into a meeting note, shared brief, or campaign-readout appendix without becoming another dashboard.
The safest habit is to fill the fields in order. First name the decision, then lock the evidence level, then check whether the sold package and the delivered package match, then separate response volume from response quality, and only then write the next action. That order prevents a high click count from hiding a weak source trail or an immature outcome window.
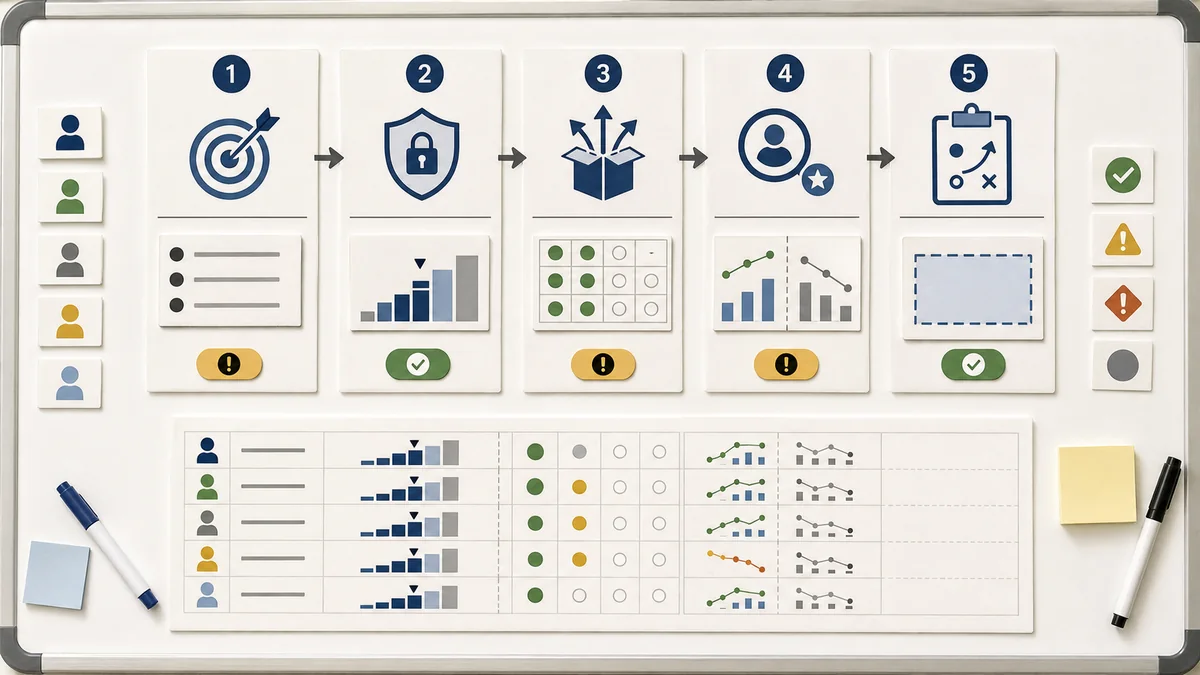
| Field | Fill this in | Good answer | Weak answer |
|---|---|---|---|
| Campaign job | The reader or buyer decision the campaign was meant to inform. | Qualified visits from measurement-planning readers. | Awareness and conversions. |
| Package and placement scope | Package ID, deal key, eligible contexts, placement IDs, sizes, device classes, and exclusions. | measurement-science-desk, article-inline-1, article-inline-2, rail only on desktop, archive leaderboard included. | Measurement audience. |
| Primary signal | The metric selected before results were visible. | Qualified visits plus lead-status completeness. | Whichever metric rose most. |
| Comparison rule | No comparison, prior flight, matched context, matched market, survey control, or holdout. | Prior contextual flight; no protected holdout. | Compared to expectations. |
| Source trail | Fields that connect impressions, clicks, sessions, leads, and outcomes to package, placement, creative, destination, and device. | campaign_id, package_id, placement_id, creative_id, destination_id, device_class, outcome_status. | Campaign total only. |
| Quality flags | Low delivery cells, missing outcome status, uneven creative rotation, device mix shifts, invalid-traffic review, or destination friction. | Mobile destination friction and two low-delivery placement cells. | No flags shown. |
| Claim boundary | The strongest language the evidence supports. | Observed qualified traffic was strongest in upper-body guide contexts; lift was not measured. | The package created incremental demand. |
| Next action | The action the team can take now. | Renew guide contexts with revised mobile destination and add a holdout if the next decision needs lift. | Scale based on top-line response. |
Score the readout
Use a simple 0-2 score for each evidence area. The total is not a universal grade. It is a way to decide whether the next conversation should be renewal, revision, or stronger measurement.
| Evidence area | 0 points | 1 point | 2 points | What the score controls |
|---|---|---|---|---|
| Package fit | Package boundaries unclear or off-package delivery is not visible. | Most delivery matches the package, with some unresolved exceptions. | Delivery is shown by agreed context, placement, device, size, and date. | Whether renewal can be tied to the sold package. |
| Reporting grain | Only campaign totals are available. | Some package, placement, creative, or device fields are visible. | Rows preserve package, placement, creative, device, destination, and outcome status. | Whether the team can diagnose the result. |
| Outcome quality | Clicks, visits, or form fills are treated as the final result. | Some quality fields exist, but status is incomplete or uneven. | Qualified visits, lead status, match status, or buyer-side quality fields are visible with missing-data notes. | Whether volume can inform a business decision. |
| Comparison quality | No comparison is named. | A prior period or matched context is named with limits. | A holdout, matched market, survey control, or test design was defined before launch. | Whether the readout can use causal language. |
| Decision language | The recommendation overstates what the evidence can show. | The recommendation is mostly bounded but leaves some ambiguity. | The recommendation names the action, evidence level, missing fields, and next-test trigger. | Whether the report is ready for a budget conversation. |
Translate the score into a meeting decision
The total score should change the meeting agenda. A low score is not a failed campaign by itself; it means the report is not ready for a strong claim. A high score does not prove lift unless the comparison design supports lift language.
| Total score | Best meeting posture | Allowed recommendation | Evidence to request next |
|---|---|---|---|
| 0-3 | Repair the record before renewal. | Pause, rebrief, or hold the recommendation until package scope, source rows, or outcome status are visible. | Package delivery rows, placement IDs, status coverage, and a clean decision line. |
| 4-6 | Use directional language and fix the weak lane. | Renew only the verified scope, revise creative or destination, or retest a promising slice before scale. | The one missing field or comparison rule most likely to change the recommendation. |
| 7-8 | Make a bounded renewal decision. | Renew or revise with named limits, missing fields, and conditions for the next flight. | Stronger comparison, status-window closeout, or minimum-cell evidence if the next decision is larger. |
| 9-10 | Use the report for a confident operating decision. | Renew, narrow, or shift within the observed scope while keeping causal language tied to the actual comparison design. | A holdout, matched-market design, or calibrated model input if the next claim needs incrementality. |
Filled worksheet example
This example shows how a concise worksheet can keep the discussion practical. The values are placeholders for structure, not performance benchmarks.
| Worksheet line | Example entry | Interpretation |
|---|---|---|
| Decision | Renew the measurement-science package, revise mobile destination, or add a lift test. | The meeting is about the next buy, not a broad proof of impact. |
| Evidence level | Descriptive delivery and outcome-status reporting with a prior-flight comparison. | Directional readout language is acceptable; causal lift language is not. |
| Package fit | Guide pages and archive leaderboard delivered as planned; rail delivery was desktop-only. | Delivery mostly fits the package, and device rules are visible. |
| Strongest observed signal | Upper-body guide placements produced the most qualified visits per valid click. | This supports package-fit discussion, not a universal placement ranking. |
| Main quality flag | Mobile clicks had lower qualified-visit depth and higher destination bounce. | Review landing-page friction before judging mobile inventory quality. |
| Missing field | Lead status was missing for 14% of form fills at close of reporting. | Outcome interpretation may change when buyer-side status is completed. |
| Recommendation | Renew guide contexts with revised mobile destination and require full status return before the next renewal review. | The action follows the observed evidence and names the missing field. |
Simulated worked example: calculate before recommending
Simulated Worked Example - not a real campaign or benchmark. Suppose a contextual package records 100,000 impressions, 400 clicks, 180 qualified visits, and 35 form fills. At the reporting cutoff, 20 leads are qualified, 10 are disqualified, and 5 remain pending. The calculations below show how to keep the denominator and status window visible.
| Calculation | Formula | Result | What the worksheet can say |
|---|---|---|---|
| Click-through rate | 400 clicks / 100,000 impressions | 0.40% | Describes observed click response in the reported rows; it is not an efficiency benchmark. |
| Qualified-visit rate | 180 qualified visits / 400 clicks | 45.00% | Useful only if "qualified visit" has one documented rule across destinations and devices. |
| Resolved lead-qualification rate | 20 qualified / (20 qualified + 10 disqualified) | 66.67% | Describes resolved lead status while excluding the five pending records from the resolved denominator. |
| Pending-status share | 5 pending / 35 total form fills | 14.29% | The recommendation should name the open status window instead of treating pending as success or failure. |
| Qualified visits per 1,000 impressions | 180 / 100,000 x 1,000 | 1.80 | A descriptive delivery-normalized rate; it does not estimate incremental demand. |
Bounded decisionIn this simulation, the team can describe observed response and renew only the verified package scope if the same field definitions and status rules continue. It cannot claim that the package caused the qualified visits without a pre-specified comparison, protected holdout, or other valid design. If the five pending records later resolve differently, the lead-quality interpretation changes and the worksheet should be recalculated.
Assumptions and limits: each impression, click, visit, and form fill is deduplicated under the stated campaign window; the qualified-visit rule is stable; resolved lead statuses are comparable; and no rows were selectively excluded. If any assumption fails, split the calculation by the affected placement, device, destination, or status window and lower the claim strength.
Simulated worked example: readiness before renewal
Simulated Worked Example - not a real campaign or benchmark. Apply one binary gate to the same sample packet before the meeting turns into a renewal recommendation. A passed gate means the packet contains enough documented evidence for that narrow question; it does not mean the campaign caused the outcome.
| Gate | Packet check | Result | Why it matters |
|---|---|---|---|
| 1. Decision named | Renew guide contexts, revise mobile destination, or add a lift test. | Pass | The reader can tell which action the worksheet is meant to support. |
| 2. Delivery scope | Guide pages and archive leaderboard match the stated package; desktop-only rail delivery is recorded. | Pass | The recommendation can be limited to the observed scope instead of the whole campaign. |
| 3. Reporting grain | Placement, device, destination, and outcome-status fields are available for the readout rows. | Pass | The team can inspect where the result came from and reproduce the worksheet. |
| 4. Outcome closeout | Five of 35 form fills are still pending at the cutoff. | Hold | The 14.29% pending share leaves a material portion of the outcome denominator unresolved. |
| 5. Comparison strength | The packet names a prior-flight comparison but has no protected holdout or matched-market design. | Hold | A prior flight can support directional context, not an incremental-lift claim. |
Reproduction: 3 passed gates / 5 total gates = 60%. Use Revise before renewal for this packet: close or label the pending status window, preserve the package and device exceptions, and write a separate test plan if the next decision needs lift. Treat 5/5 as readiness for a bounded operating decision, 3-4/5 as revise-before-renewal, and 0-2/5 as hold/rebrief. Those thresholds are this worksheet's operating rule, not an industry benchmark.
What could change the result: if the five pending leads resolve and the evidence rows remain comparable, gate 4 can be rerun. If a protected holdout or matched-market design is added before the next flight, gate 5 can be rerun for that new claim; neither change retroactively turns this descriptive packet into a lift study.
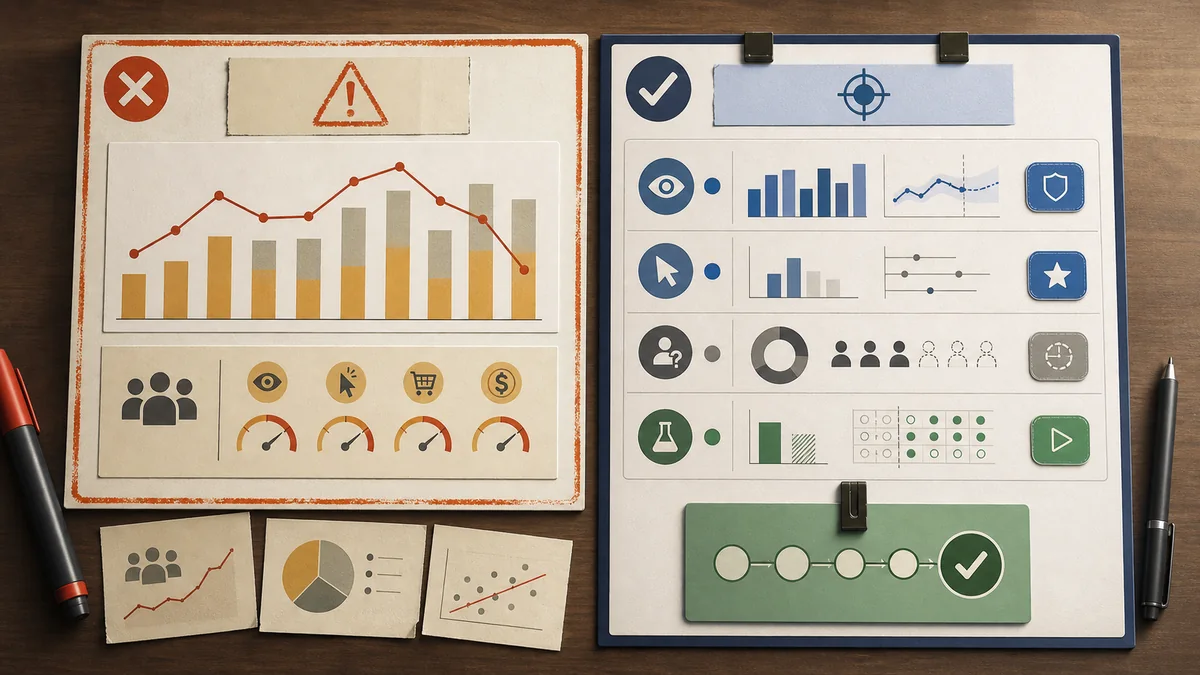
Decision language blocks
Copy one of these blocks into the final readout, then edit the details so the language matches the actual evidence.
Renew as reportedUse when delivery matched the sold package, reporting fields are complete enough to interpret, and the observed response supports another similar flight without claiming lift.
Renew with revisionsUse when the package fit is credible but creative, destination, device mix, placement allocation, or outcome-status return needs a tighter second flight.
Retest before shifting budgetUse when the strongest result depends on a small cell, uneven creative rotation, missing status, or a weak comparison.
Add lift designUse when the next decision requires incrementality, brand movement, or matched-market evidence that the current readout was not designed to estimate.
Pause or rebriefUse when package scope, delivery records, source trails, or outcome definitions are too incomplete to support a confident renewal.
Readout meeting questions
- Which decision should this report influence today?
- Was the campaign delivered in the contexts, placements, sizes, and devices the buyer approved?
- Which result changes if clicks, raw visits, or form fills are replaced with qualified outcomes?
- Which missing field would change the recommendation most?
- Does the next action require a stronger comparison than this campaign used?
Pair with
Use this worksheet with the campaign reporting sample for a full readout structure, the campaign readout QA checklist for evidence review, the private marketplace readout export sample for row-level fields, the private marketplace renewal scorecard for final action scoring, the campaign issue log and renewal register for unresolved rows, the campaign status-window closeout checklist when delayed outcome fields are not yet final, the campaign status-window closeout register when final and preliminary rows need exportable closeout fields, the campaign renewal memo template for final renew, revise, retest, or hold wording, the campaign renewal evidence archive for preserving final limits across flights, the contextual package proof sheet for the pre-launch handoff, the campaign data-layer spec for source-trail fields, the outcome quality scorecard for traffic and lead interpretation, the media kit for package and placement definitions, and the inventory readiness matrix for reporting keys.