Measurement operations
First-party signal readiness checklist
Organization byline: Measurement Press editorial desk. This page does not list an individual author or reviewer. Read the editorial method and corrections policy.
About 14 min read
First-party signals are useful only when the readout can explain what each record represents, where it came from, and which comparison it can support. A cleaner signal trail can improve campaign reporting, but it does not create lift by itself.
Use this checklist before a private marketplace campaign, direct sponsorship, lead-generation program, clean-room matchback, lift test, MMM calibration input, or brand study handoff. The goal is to make source quality visible before a report turns partial records into confident performance language.
Imagine a renewal meeting for a contextual campaign. Delivery was strong, a few pages produced high-quality visits, the buyer-side lead file arrived late, and the analyst wants to connect matched accounts to budget value. The first question is not whether the number looks good. The first question is whether the record trail is ready to support that kind of sentence.
In plain language, a first-party signal is information captured by the publisher, advertiser, or campaign owner through its own sites, forms, events, systems, or customer records. It can be powerful because it is close to the actual reader or buyer interaction. It can also mislead when source fields, consent state, eligibility, duplicate rules, or comparison design are missing.
Method sources for this guide
The source-trail and consent checks here follow the Google Analytics introduction to user consent management, which separates obtaining consent, sending the user's choice, and verifying that tags respect it. For lead and matchback fields, the Google Ads enhanced conversions for leads implementation checklist calls for distinct conversion actions, accurate conversion times, upload coverage, match keys, and diagnostics rather than an unexplained matched total.
For imported outcomes, the Google Ads offline conversion imports FAQs documents duplicate handling, conversion timing, and the limits of the imported record. A causal readout needs a designed comparison: Google Ads Conversion Lift describes treatment and control groups and frames incrementality as a controlled experiment, not as a post-hoc comparison of matched records.
| Source establishes | Use it to check | It does not establish |
|---|---|---|
| Consent management | Obtain the user's choice, send the consent signal, and verify tag behavior. | That a record is legally usable in every jurisdiction or that a measurement result is unbiased. |
| Enhanced conversions for leads | Conversion actions, match keys, conversion time, upload coverage, deduplication, and diagnostics. | That a matched lead is qualified, closed, incremental, or representative without business and comparison evidence. |
| Offline conversion imports | Conversion-time reporting, rejected rows, timing limits, funnel-stage separation, and duplicate handling. | That upload totals equal outcomes by click date or that a late or matched record proves campaign value. |
| Conversion Lift | Treatment/control design and the distinction between incremental and attributed conversions. | That a post-hoc matched-record comparison, simulated packet, or contaminated test proves lift. |
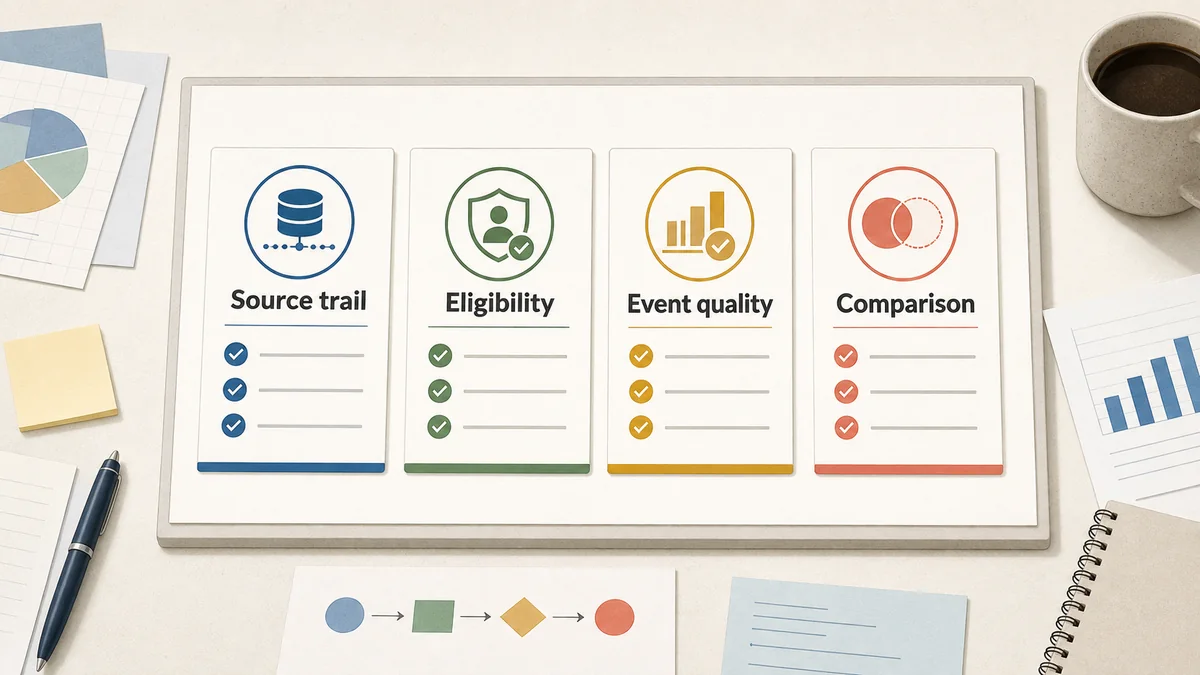
What counts as ready
A ready signal is not just available. It has a defined owner, scope, timestamp, eligibility rule, join rule, and claim boundary.
Think of the signal map as a chain. Page context and exposure records describe what was eligible to happen. Visit, lead, account, outcome, and survey records describe what was observed later. The comparison record says whether the readout can make only a descriptive statement or a stronger decision statement.
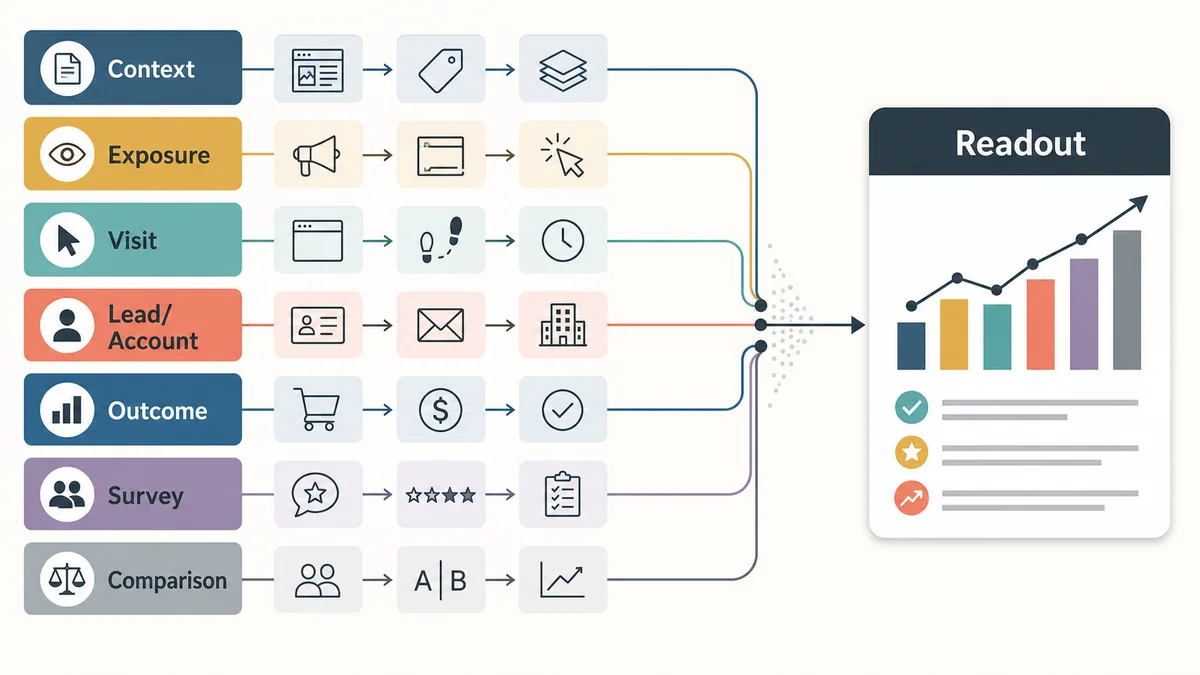
| Signal family | What to record | What it can support |
|---|---|---|
| Page and context signal | Page URL, topic desk, reader job, content group, ad slot, package ID, and placement ID. | Contextual delivery, package proof, and page-level performance comparisons. |
| Exposure signal | Eligible impression, measurable status, viewable status where available, timestamp, device class, market, creative ID, and frequency rule. | Delivery and exposure-quality evidence, not sales or brand lift by itself. |
| Visit signal | Click ID where available, session ID, referrer category, landing page, URL parameter set, and duplicate rule. | Observed traffic quality and destination behavior under the stated source trail. |
| Permission and eligibility signal | Whether the record is eligible for the planned measurement join, why it is eligible or excluded, and when that state was observed. | Clear denominators for match rates, excluded records, and reporting coverage. |
| Lead or account signal | Event ID, form version, source trail, duplicate flag, qualification status, disqualification reason, and follow-up status. | Lead quality and sales-process evidence, not incremental demand without a comparison. |
| Outcome signal | Outcome source, value basis, timestamp, conversion window, identity unit, match method, unmatched count, and dedupe rule. | Matched outcome reporting and calibration inputs when limitations are visible. |
| Survey signal | Sample source, exposed/control flag, recruitment path, field date, question version, weighting status, and base size. | Perception movement for the measured sample and window. |
| Comparison signal | Holdout, matched market, prior baseline, no-comparison flag, suppression rule, or planned follow-up test. | Evidence-level language that separates descriptive reporting from lift claims. |
Readiness levels
Use the levels as gates, not as a grade. A campaign can be quality ready for a traffic or lead-quality discussion and still not be comparison ready for a lift claim. The right level is the highest level where the missing fields are visible and the decision language still stays honest.
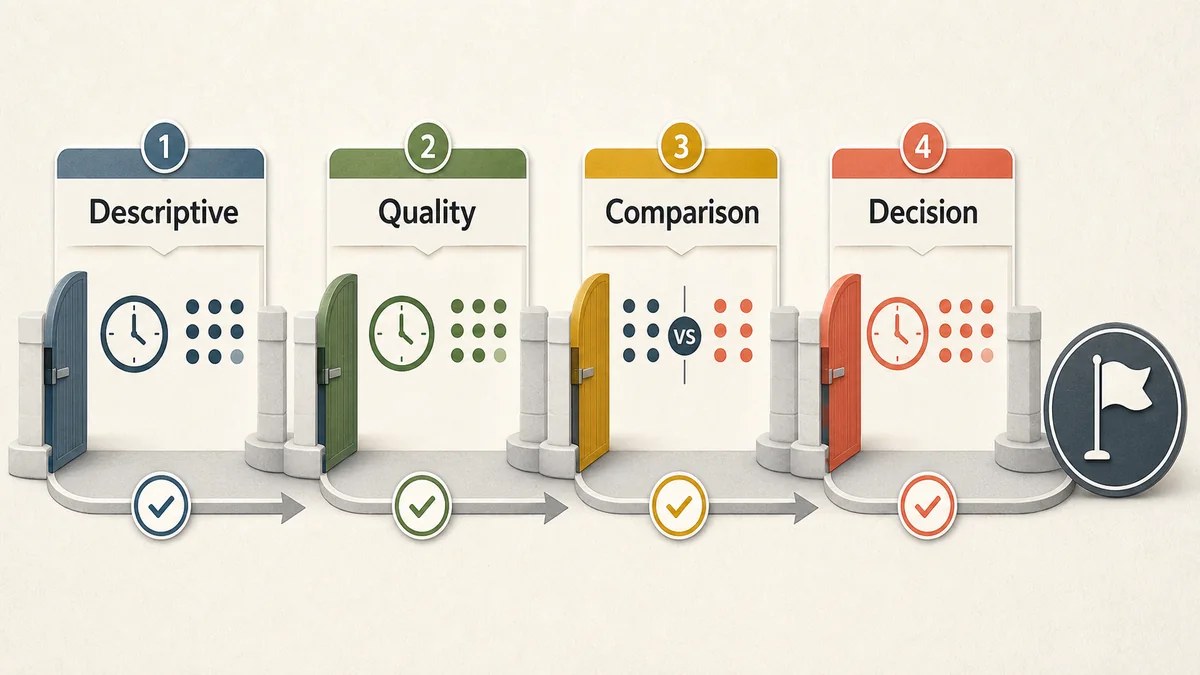
| Level | Required evidence | Strongest responsible readout |
|---|---|---|
| Not ready | Signals exist in separate systems, but IDs, eligibility rules, missing values, and timestamps are inconsistent. | Operational notes only. Do not use the data for campaign conclusions. |
| Descriptive ready | Campaign, placement, creative, destination, and event fields can be joined with visible missing-value rules. | The campaign delivered observed activity under the stated source trail. |
| Quality ready | Traffic, lead, matchback, survey, or outcome fields include dedupe, eligibility, and quality status. | The campaign produced measured response or quality signals under named definitions. |
| Comparison ready | A holdout, matched context, prior baseline, or explicit no-comparison flag was locked before results were visible. | The readout can compare planned cells inside the design limits. |
| Decision ready | The signal trail, outcome definition, comparison, uncertainty, leakage checks, and decision threshold are all visible. | The evidence can support a bounded renewal, budget, creative, or test decision. |
Minimum field map
Stable campaign and package IDsUse IDs that survive proposal, trafficking, analytics, export, invoice, and renewal records. Presentation labels can change; measurement IDs should not.
Event timestamps and timezoneEvery exposure, visit, lead, survey, match, and outcome record needs a time basis. Without it, lag, windowing, and sequence claims become guesswork.
Eligibility and exclusion stateA readout should show which records could enter each join and which records could not. Excluded records are part of the denominator, not a footnote.
Missing-value vocabularyBlank, unavailable, not applicable, filtered, suppressed, and unmatched should be separate values. Collapsing them creates false precision.
Comparison and suppression fieldsIf a holdout, market split, suppression rule, or prior baseline matters to the claim, it should be present before launch and retained in the readout.
Change logCreative swaps, destination edits, audience expansion, tracking changes, pauses, outages, and routing changes should be dated so the readout can separate media effects from operational changes.
Preflight QA
Run the preflight while launch records are still repairable. A readiness review after the report arrives can explain gaps, but it cannot recreate missing source fields, consent states, or locked comparison rules.
| Question | Pass condition | Downgrade if missing |
|---|---|---|
| Can the page context be recovered from the report? | Topic desk, content group, package ID, placement ID, and slot format survive into export fields. | Do not compare package or placement performance. |
| Can records be joined without presentation labels? | Campaign, creative, destination, event, and outcome IDs are stable across systems. | Report only source-system totals. |
| Can ineligible records be counted? | Eligibility, excluded, suppressed, unmatched, and unknown states are distinct. | Do not use match rate or response rate as a quality claim. |
| Can outcomes mature before the readout? | Conversion window, lag rule, follow-up status, and reporting cutoff are visible. | Label outcomes as immature or directional. |
| Can matched records be deduped? | Identity unit, duplicate rule, match method, unmatched count, and outcome source are documented. | Do not treat matched records as incremental outcomes. |
| Can a comparison be protected? | Holdout, matched market, prior baseline, or no-comparison status is locked before results are visible. | Use descriptive language only. |
Use cases
The same source trail can serve different measurement jobs, but each job needs a different ceiling on language. A signal trail that is good enough for a placement-quality report may still be too thin for a causal budget claim.
| Measurement use | Signal readiness needed | Main overclaim to avoid |
|---|---|---|
| Private marketplace readout | Package, placement, device, creative, traffic-quality, and outcome-status fields. | Pooling unlike contexts into one performance story. |
| Lead quality report | Source trail, form version, duplicate status, qualification status, disqualification reason, and follow-up status. | Calling raw form volume qualified demand. |
| Clean-room or matchback report | Identity unit, eligible universe, match method, unmatched count, conversion window, and outcome source. | Calling matched outcomes incremental outcomes. |
| Lift test | Assignment or suppression field, exposure compliance, leakage checks, primary outcome, and uncertainty. | Treating a contaminated or post-hoc comparison as causal evidence. |
| MMM calibration input | Experiment design notes, market or audience scope, timing, uncertainty, and outcome definition. | Using a narrow or noisy result as a universal model anchor. |
| Brand study | Recruitment source, exposed/control balance, question version, field dates, base size, and weighting status. | Treating respondent movement as broad market impact. |
Common failure modes
Most first-party signal problems are not dramatic tracking failures. They are small translation breaks: a label changes, a denominator disappears, a consent state is collapsed, or a comparison is added after the team has already seen results.
Silent exclusions
Records that are unmatched, ineligible, filtered, or suppressed disappear from the denominator.
Context loss
Page, package, and placement fields are stripped before the buyer-facing report.
Identity over-merge
Users, households, accounts, devices, and companies are treated as interchangeable units.
Outcome immaturity
Lead follow-up, sales cycle, conversion lag, or survey fielding is incomplete when the report is written.
Join-rate selection
The matched population is easier to identify, higher intent, or more loyal than the unmatched population.
Comparison contamination
Control, holdout, or prior-period records receive overlapping media, offers, sales contact, or tracking changes.
Worked readiness score
Before writing the final readout, give each layer a pass, warning, or hold state. The score is not for decoration. It decides which sentence the report is allowed to use.
| Review layer | Pass | Warning | Hold | Allowed language |
|---|---|---|---|---|
| Source trail | Campaign, package, placement, creative, destination, and event IDs survive into the export. | One system uses a presentation label that needs translation. | Rows cannot be joined without guessing. | Pass supports source-specific reporting; hold limits the report to system totals. |
| Eligibility denominator | Eligible, excluded, suppressed, unmatched, duplicate, and unknown states are distinct. | One exclusion reason is grouped but counted. | Excluded records disappear from the denominator. | Pass supports rate language; hold blocks match-rate or response-rate quality claims. |
| Event quality | Timestamp, timezone, event version, duplicate rule, and maturity window are visible. | Late events are expected but labeled immature. | Event timing or duplicate handling is unknown. | Pass supports observed response language; hold requires directional or operational language. |
| Outcome join | Identity unit, match method, unmatched count, outcome source, and conversion window are documented. | Matched outcomes are usable but the unmatched group is materially different. | The matched file is the only visible universe. | Pass supports matched outcome reporting; hold blocks value or incrementality language. |
| Comparison boundary | Holdout, matched context, prior baseline, or no-comparison status was locked before results. | The comparison is useful but has known leakage or context differences. | The comparison was chosen after seeing results. | Pass can support bounded comparison language; hold means descriptive language only. |
Simulated worked example: 1,000 exposure records
Simulated scenario: assume a campaign export contains 1,000 exposure rows. The numbers below are illustrative and do not describe a real campaign, advertiser, or outcome. They show why a source-ready denominator and a comparison boundary must be reported separately.
| Gate | Simulated record | Arithmetic | Responsible readout |
|---|---|---|---|
| Stable source trail | 920 rows retain campaign, package, placement, creative, and event IDs. | 920 ÷ 1,000 = 92.0%; 80 rows need repair or exclusion. | Report source-specific activity only for the rows whose join fields survive. |
| Consent and eligibility | 800 rows have a documented measurement-eligibility state. | 800 ÷ 1,000 = 80.0%; the missing 200 rows stay visible. | Use 800 as the eligible base for a match-rate or response-rate calculation, not 1,000. |
| Qualified outcome | 152 qualified outcomes are observed among those 800 eligible rows. | 152 ÷ 800 = 19.0%; 152 ÷ 1,000 = 15.2% is a different all-export share. | Label the 19.0% as an observed eligible-base rate; do not call it incremental value. |
| Comparison boundary | No holdout or matched comparison was locked before results were visible. | 0 causal comparisons ÷ 1 planned comparison = 0 available. | Keep the claim ceiling descriptive or operational until a credible comparison exists. |
The conclusion would change if the excluded rows were reconciled, the eligibility rule changed, the outcome window matured, or a pre-registered holdout became available. Until then, the packet can document observed signal quality and the next measurement repair; it cannot establish lift, incremental demand, or future performance.
Decision packet: repair, report, or test
Simulated packet -- not a real campaign, advertiser, matchback, forecast, or recommendation: Apply six gates to the same 1,000-row example. One gate passes for descriptive rate arithmetic, four require repair, and the comparison gate is a hard hold. The packet therefore supports a bounded operational report, not a quality, value, or incrementality claim.
| Gate | Simulated result | Arithmetic | Decision effect |
|---|---|---|---|
| Source trail | 920 of 1,000 rows retain the full join key set. | 920 / 1,000 = 92.0% | Revise before source-specific performance comparisons; 80 rows need repair or exclusion. |
| Consent and eligibility | 800 of 1,000 rows have a documented measurement-eligibility state. | 800 / 1,000 = 80.0% | Revise the denominator; 200 unknown rows cannot silently be treated as eligible. |
| Observed qualified outcome rate | 152 qualified outcomes are recorded among the 800 eligible rows. | 152 / 800 = 19.0% | Passes descriptive arithmetic only; it does not establish incremental demand. |
| Outcome maturity | 120 of the 152 outcomes have completed the stated follow-up window. | 120 / 152 = 78.9% | Revise the readout or label 32 outcomes immature; do not present the total as final. |
| Join and dedupe | 144 outcomes are unique under the stated identity rule; 8 remain duplicate-risk rows. | 144 / 152 = 94.7% | Revise the matched total until duplicate handling and the unmatched group are documented. |
| Comparison boundary | No holdout or matched comparison was locked before results were visible. | 0 / 1 planned comparison = 0% | Hard hold: descriptive or operational language only; no lift or causal value sentence. |
Sensitivity check: If all 200 unknown eligibility rows are added to the denominator, the observed rate becomes 152 / 1,000 = 15.2%, down 3.8 percentage points from 19.0%. If the 32 immature outcomes are excluded until follow-up closes, the interim rate becomes 120 / 800 = 15.0%, down 4.0 points. If the eight duplicate-risk rows are removed from the numerator, the rate becomes 144 / 800 = 18.0%, down 1.0 point. A later, post-result comparison of 152 treatment outcomes among 800 records against 136 among 800 comparison records would be 19.0% - 17.0% = 2.0 percentage points, but it would not become causal evidence because the comparison was not protected before results were seen.
Action rule: Repair the source and eligibility fields, keep the current 19.0% figure labeled as an observed eligible-base rate, close the maturity and dedupe checks, and pre-register a holdout or matched design before using budget, lift, or incremental-value language. If those records cannot be supplied, report the missingness and stop at the descriptive claim.
Assumptions and limits: Every number in this packet is simulated; the rows are assumed to be mutually countable, and the rates are arithmetic rather than confidence intervals, significance tests, or forecasts. The packet does not resolve selection into the eligible or matched population, consent-law requirements, cross-channel exposure, conversion lag beyond the stated window, or a valid causal design. Those limitations are part of the result, not cleanup to add later.
Decision language ladder
The final readout should translate readiness into a claim ceiling. A claim ceiling is the strongest responsible sentence the evidence can support. If the comparison is weak, the report can still be useful, but it should talk about observed activity, quality, and next tests rather than guaranteed outcomes.
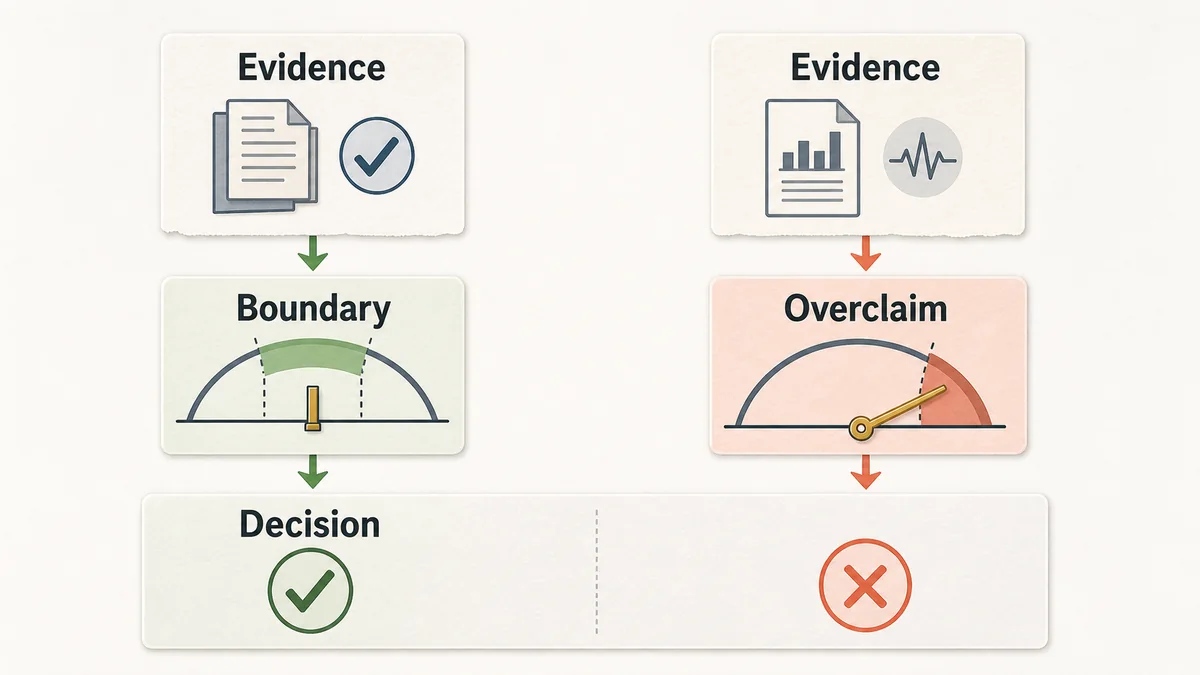
| Signal state | Stronger wording | Weaker wording |
|---|---|---|
| Source fields inconsistent. | The source trail is incomplete and should be repaired before performance is interpreted. | The campaign underperformed or overperformed. |
| Delivery and visit signals ready. | The campaign produced measured delivery and observed traffic under the stated definitions. | The campaign created incremental demand. |
| Lead and outcome quality ready. | The report can separate raw response, qualified response, matched outcomes, and excluded records. | The campaign generated all reported value. |
| Comparison ready. | The readout supports a bounded comparison inside the locked design and observed window. | The result proves future performance in every context. |
| Decision ready with uncertainty. | The evidence supports the stated renewal, creative, budget, or test decision within the disclosed limits. | The measurement has settled the channel's exact value. |
Meeting script
- Which reader, buyer, or budget decision will this signal trail support?
- Which fields must survive from page context through the final readout?
- Which records are eligible, excluded, suppressed, unmatched, or unknown?
- Which identity unit is being joined, and where could duplicates enter?
- Which outcome window, follow-up window, or survey field date needs to mature before reporting?
- Which comparison rule keeps the readout from overstating observed activity?
Pair with
Use this checklist before the campaign data-layer spec, campaign tagging QA checklist, landing page launch QA worksheet, contextual package proof export template, and private marketplace reporting field dictionary. After launch, pair it with the private marketplace readout export sample, campaign readout QA checklist, identity matchback checklist, reach and frequency checklist, and private marketplace renewal scorecard. When the decision requires causal evidence, write the incrementality test plan before results are visible.